Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
Loading...
One platform to optimize how you access and control data.
Immuta gives everyone fast, governed access to data with the built-in controls, collaboration workflows, automated provisioning, and continuous monitoring you need to keep risk low and compliance high.
This section illustrates how to install Immuta on Kubernetes using the Immuta Enterprise Helm chart.
This reference guide provides an overview of the Immuta Enterprise Helm chart version requirements and infrastructure recommendations.
The guides in this section illustrate how to install and deploy Immuta in your Kubernetes environment.
This guide illustrates how to upgrade Immuta.
The guides in this section illustrate how to configure your Immuta Enterprise Helm chart for various scenarios, including optimizing your deployment for production environments.
This guide provides links to additional resources for disaster recovery strategies.
This page provides troubleshooting guidance and outlines frequently asked questions for the Immuta installation.
This page introduces the core concepts and terminology essential for understanding the installation material.
All application state is stored in the PostgreSQL metadata database; therefore, recovering from a disaster event only entails restoring the aforementioned PostgreSQL database. Consult each cloud provider's point-in-time recovery (PITR) documentation for guidance:
For more details about point-in-time recovery, see the .
Learn about how Immuta generates policy-enforced views in your Azure Synapse Analytics Dedicated SQL pool to govern your data
In this integration, Immuta generates policy-enforced views in a schema in your configured Azure Synapse Analytics Dedicated SQL pool for tables registered as Immuta data sources.
This guide outlines how to integrate Azure Synapse Analytics with Immuta.
Azure Synapse Analytics configuration: Configure the integration in Immuta.
Azure Synapse Analytics integration reference guide: This guide describes the design and components of the integration.
Azure Synapse Analytics pre-configuration details: This guide describes the prerequisites, supported features, and limitations of the integration.
Move your data to Unity Catalog and re-register those securables in Immuta so Immuta can administer Unity Catalog access controls
When you enable Unity Catalog, Immuta automatically migrates your existing Databricks data sources in Immuta to reference the legacy hive_metastore catalog to account for Unity Catalog's three-level hierarchy. New data sources will reference the Unity Catalog metastore you create and attach to your Databricks workspace.
Because the hive_metastore catalog is not managed by Unity Catalog, existing data sources in the hive_metastore cannot have Unity Catalog access controls applied to them. Data sources in the Hive Metastore must be managed by the Databricks Spark integration.
To allow Immuta to administer Unity Catalog access controls on that data, move the data to Unity Catalog and re-register those tables in Immuta by completing the steps below. If you don't move all data before configuring the integration, metastore magic will protect your existing data sources throughout the migration process.
Ensure that all Databricks clusters that have Immuta installed are stopped and the Immuta configuration is removed from the cluster. Immuta-specific cluster configuration is no longer needed with the Databricks Unity Catalog integration.
Move all data into Unity Catalog before configuring Immuta with Unity Catalog. Existing data sources will need to be re-created after they are moved to Unity Catalog and the Unity Catalog integration is configured.
.
Learn how end users can access policy-enforced data in Databricks Unity Catalog
Once data is registered through the Databricks Unity Catalog connection, you will access your data through your Databricks queries as you normally would. If you are subscribed to the data source, Immuta grants you access to the data in Databricks.
When you submit a query, the Databricks Unity Catalog client submits the SQL query to Databricks, which then processes the query and determines what data your group is allowed to see. Then, Databricks queries the database and returns the query results to the Databricks Unity Catalog client, which then returns policy-enforced data to you.
The diagram below illustrates how Immuta, Databricks, and Databricks Untiy Catalog client interact to access data.
Query Databricks Unity Catalog securables exactly how you normally would in Databricks. Because grants are managed through groups and data policies are managed through UDFs, there is no additional setup required from the data consumers.
This guide demonstrates how to verify signed artifacts (i.e., container images, Helm charts) hosted on ocir.immuta.com using from .
The provided key is used to sign the Helm chart and container images.
A DIGESTS.md markdown file comes bundled in the Helm chart and contains a comprehensive list of images and digests referenced. To view the file, follow these steps:
Download and extract the Helm chart into the working directory.
Open file immuta-enterprise/DIGESTS.md
If you're using AWS OpenSearch in your Immuta installation, use this how-to to set up the proper permissions needed for username and password authentication.
In the AWS console, and create a master user. This user will set up the permissions for the audit user.
In the OpenSearch console, . This user will be the audit user. You will enter the username and password for this user when installing Immuta.
for the audit user.
The following conventions are used throughout the installation material.
Phrases wrapped in angle brackets (i.e., <, >) are placeholders used to indicate values that must be substituted with user-provided values. Placeholders are typically written in either , or ; the following placeholders are equivalent:
<the-quick-brown-fox>
Learn how to best implement Immuta with Azure Synapse Analytics in your data ecosystem
The how-to guides linked on this page illustrate how to integrate Azure Synapse Analytics with Immuta. See the for information about the Azure Synapse Analytics integration.
Requirement: A running Dedicated SQL pool
Connect your technology
These guides provide instructions on getting your data set up in Immuta.
Learn about how you can register data from the Databricks legacy Hive metastore and govern access to that data
This integration enforces policies on Databricks securables registered in the legacy Hive metastore. Once these securables are registered as Immuta data sources, users can query policy-enforced data on Databricks clusters.
The guides in this section outline how to integrate Databricks Spark with Immuta.
This getting started guide outlines how to integrate Databricks with Immuta.
: Manually update your cluster to reflect changes in the Immuta init script or cluster policies.
Install a third-party library as trusted to enable that library's code to bypass the Immuta security manager
In the Databricks Clusters UI, install your third-party library .jar or Maven artifact with Library Source Upload, DBFS, DBFS/S3, or Maven. Alternatively, use the Databricks libraries API.
In the Databricks Clusters UI, add the IMMUTA_SPARK_DATABRICKS_TRUSTED_LIB_URIS
Troubleshoot common errors with the Databricks Spark integration
This page provides guidelines for troubleshooting issues with the Databricks Spark integration and resolving Py4J security and Databricks trusted library errors.
For easier debugging of the Databricks Spark integration, follow the recommendations below.
Enable cluster init script logging:
In the cluster page in Databricks for the target cluster, navigate to Advanced Options -> Logging.
Learn how the Databricks Spark integration works to govern data access
The Databricks Spark integration is one of two integrations Immuta offers for Databricks.
In this integration, Immuta installs an Immuta-maintained Spark plugin on your Databricks cluster. When a user queries data that has been registered in Immuta as a data source, the plugin injects policy logic into the plan Spark builds so that the results returned to the user only include data that specific user should see.
The reference guides in this section are written for Databricks administrators who are responsible for setting up the integration, securing Databricks clusters, and setting up users:
: This guide includes information about what Immuta creates in your Databricks environment and securing your Databricks clusters.
Learn about how Immuta uses ephemeral overrides to determine which cluster compute to use when connecting to Databricks for maintenance operations
In the context of the Databricks Spark integration, Immuta uses the term ephemeral to describe data sources where the associated compute resources can vary over time. This means that the compute bound to these data sources is not fixed and can change. All Databricks data sources in Immuta are ephemeral.
Ephemeral overrides are specific to each data source and user. They effectively bind cluster compute resources to a data source for a given user. Immuta uses these overrides to determine which cluster compute to use when connecting to Databricks for various maintenance operations.
The operations that use the ephemeral overrides include
Visibility checks on the data source for a particular user. These checks assess how to apply row-level policies for specific users.
Manage Databricks Unity Catalog integration and connection settings
Navigate to the connection or connection-backed object.
Click Run Object Sync.
Click the Edit button in the Connection details box.
Delete your Snowflake integration
To delete the host,
Click Data in the navigation menu and select Connections.
Click the overflow menu in the Actions column and select Delete Host.
Download the cleanup script from the modal.
Delete your Databricks Unity Catalog connection
To delete the host,
Click Data in the navigation menu and select Connections.
Click the overflow menu in the Actions column and select Delete Connection.
Download the cleanup script from the modal.
Delete your Trino connection
To delete the host,
Click Data in the navigation menu and select Connections.
Click the overflow menu in the Actions column and select Delete Connection.
Click Delete Host again to confirm.
Learn about Immuta's integration for Amazon Redshift
In this integration, Immuta generates policy-enforced views in your configured Redshift schema for tables registered as Immuta data sources.
This guide outlines how to integrate Redshift with Immuta.
: Configure the integration in Immuta.
: Configure Redshift Spectrum in Immuta.
Navigate to Trino and delete the immuta-access-control.properties file and Immuta plugin.
Click Delete Host again to confirm.
Navigate to Snowflake and run the cleanup script in your environment to remove the Immuta-managed roles and policies.
Click Delete Connection again to confirm.
Navigate to Databricks Unity Catalog and run the cleanup script in your environment to remove the Immuta-managed groups and policies.
Customizing the integration: Consult this guide for information about customizing the Databricks Spark integration settings.
Setting up users: Consult this guide for information about connecting data users and setting up user impersonation.
Spark environment variables: This guide provides a list of Spark environment variables used to configure the integration.
Ephemeral overrides: This guide describes ephemeral overrides and how to configure them to reduce the risk that a user has overrides set to a cluster (or multiple clusters) that aren't currently up.
Redshift pre-configuration details: This guide describes the prerequisites, supported features, and limitations of the integration.
Lower the web service cache timeout settings of project UDFs
This page outlines the configuration for setting up project UDFs, which allow users to set their current project in Immuta through Spark. For details about the specific functions available and how to use them, see the Use Project UDFs (Databricks) page.
Lower the web service cache timeout in Immuta:
Click the App Settings icon and scroll to the HDFS Cache Settings section.
Lower the Cache TTL of HDFS user names (ms) to 0.
Click Save.
Raise the cache timeout on your Databricks cluster: In the Spark environment variables section, set the IMMUTA_CURRENT_PROJECT_CACHE_TIMEOUT_SECONDS and IMMUTA_PROJECT_CACHE_TIMEOUT_SECONDS to high values (like 10000).
Note: These caches will be invalidated on cluster when a user calls immuta.set_current_project, so they can effectively be cached permanently on cluster to avoid periodically reaching out to the web service.
The Snowflake low row access policy mode improves query performance in Immuta's Snowflake integration by decreasing the number of Snowflake row access policies Immuta creates and by using table grants to manage user access.
Immuta manages access to Snowflake tables by administering Snowflake row access policies and column masking policies on those tables, allowing users to query them directly in Snowflake while policies are enforced.
Project-scoped purpose exceptions for Snowflake integrations allow you to apply purpose-based policies to Snowflake data sources in a project. As a result, users can only access that data when they are working within that specific project.
This feature allows masked columns to be joined across data sources that belong to the same project. When data sources do not belong to a project, Immuta uses a unique salt per data source for hashing to prevent masked values from being joined. (See the Why use masked joins? guide for an explanation of that behavior.) However, once you add Snowflake data sources to a project and enable masked joins, Immuta uses a consistent salt across all the data sources in that project to allow the join.
For more information about masked joins and enabling them for your project, see the Masked joins section of documentation.

Install a trusted library: Register a Databricks library with Immuta as a trusted library to avoid Immuta security manager errors when using third-party libraries.
Project UDFs cache settings: Raise the caching on-cluster and lower the cache timeouts for the Immuta web service to allow use of project UDFs in Spark jobs.
Run R and Scala spark-submit jobs on Databricks: Run R and Scala spark-submit jobs on your Databricks cluster.
DBFS access: Access DBFS in Databricks for non-sensitive data.
Troubleshooting: Resolve errors in the Databricks Spark configuration.
Databricks Spark integration configuration: This guide describes the design and components of the integration.
Security and compliance: This guide provides an overview of the Immuta features that provide security for your users and Databricks clusters and that allow you to prove compliance and monitor for anomalies.
Registering and protecting data: This guide provides an overview of registering Databricks securables and protecting them with Immuta policies.
Accessing data: This guide provides an overview of how Databricks users access data registered in Immuta.
Change the Destination from NONE to DBFS and change the path to the desired output location. Note: The unique cluster ID will be added onto the end of the provided path.
View the Spark UI on your target Databricks cluster: On the cluster page, click the Spark UI tab, which shows the Spark application UI for the cluster. If you encounter issues creating Databricks data sources in Immuta, you can also view the JDBC/ODBC Server portion of the Spark UI to see the result of queries that have been sent from Immuta to Databricks.
The validation and debugging notebook is designed to be used by or under the guidance of an Immuta support professional. Reach out to your Immuta representative for assistance.
Import the notebook into a Databricks workspace by navigating to Home in your Databricks instance.
Click the arrow next to your name and select Import.
Once you have executed commands in the notebook and populated it with debugging information, export the notebook and its contents by opening the File menu, selecting Export, and then selecting DBC Archive.
Error Message: py4j.security.Py4JSecurityException: Constructor <> is not allowlisted
Explanation: This error indicates you are being blocked by Py4J security rather than the Immuta Security Manager. Py4J security is strict and generally ends up blocking many ML libraries.
Solution: Turn off Py4J security on the offending cluster by setting IMMUTA_SPARK_DATABRICKS_PY4J_STRICT_ENABLED=false in the environment variables section. Additionally, because there are limitations to the security mechanisms Immuta employs on-cluster when Py4J security is disabled, ensure that all users on the cluster have the same level of access to data, as users could theoretically see (policy-enforced) data that other users have queried.
Check the driver logs for details. Some possible causes of failure include
One of the Immuta-configured trusted library URIs does not point to a Databricks library. Check that you have configured the correct URI for the Databricks library.
For trusted Maven artifacts, the URI must follow this format: maven:/group.id:artifact-id:version.
Databricks failed to install a library. Any Databricks library installation errors will appear in the Databricks UI under the Libraries tab.
Validating a custom WHERE clause policy against a data source. When owners or governors create custom WHERE clause policies, Immuta uses compute resources to validate the SQL in the policy. In this case, the ephemeral overrides for the user writing the policy are used to contact a cluster for SQL validation.
High cardinality column detection. Certain advanced policy types (e.g., minimization) in Immuta require a high cardinality column, and that column is computed on data source creation. It can be recomputed on demand and, if so, will use the ephemeral overrides for the user requesting computation.
An ephemeral override request can be triggered when a user queries the securable corresponding to a data source in a Databricks cluster with the Spark plug-in configured. The actual triggering of this request depends on the configuration settings.
Ephemeral overrides can also be set for a data source in the Immuta UI by navigating to a data source page, clicking on the data source actions button, and selecting Ephemeral overrides from the dropdown menu.
Ephemeral override requests made from a cluster for data sources and users where ephemeral overrides were set in the UI will not be successful.
If ephemeral overrides are never set (either through the user interface or the cluster configuration), the system will continue to use the connection details directly associated with the data source, which are set during data source registration.
Ephemeral overrides can be problematic in environments that have a dedicated cluster to handle maintenance activities, since ephemeral overrides can cause these operations to execute on a different cluster than the dedicated one.
To reduce the risk that a user has overrides set to a cluster (or multiple clusters) that aren't currently up, complete one of the following actions:
Direct all clusters' HTTP paths for overrides to a cluster dedicated for metadata queries using the IMMUTA_EPHEMERAL_HOST_OVERRIDE_HTTPPATH Spark environment variable.
Disable ephemeral overrides completely by setting the IMMTUA_EPHEMERAL_HOST_OVERRIDE Spark environment variable to false.
Verify an artifact's signature by referencing Immuta's public key.
<the_quick_brown_fox>helm pull oci://ocir.immuta.com/stable/immuta-enterprise --destination . --untar --version 2026.2.0cosign verify --key ./immuta-cosign.pub <image>computerScientists:
- Alan Turing
- Grace Hopper
- Donald Knuth
- Tim Berners-Lee
- John McCarthy
- <first-name> <last-name>computerScientists:
- Alan Turing
- Grace Hopper
- Donald Knuth
- Tim Berners-Lee
- John McCarthy
- Margaret HamiltonAdd the audit user to the role.
Create the two additional roles to hold the following permission groups. Immuta recommends permission groups for a smooth configuration, but just ensure the user has all the following permissions.
immuta_cluster_permission_grp with the following permissions:
cluster:monitor/health
indices:data/write/bulk
indices:data/write/bulk*
indices:data/read/scroll
indices:data/read/scroll/clear
indices:monitor/settings/get
immuta_index_permission_grp with the following permissions for the * index:
indices:admin/aliases
indices:admin/aliases*
indices:admin/exists
Add the additional roles with the permission to the audit user's role.
After these steps are complete, your audit user should have the required permissions and you can complete the Immuta install using the user's username and password.
Register Azure Synapse Analytics data sources: This will register your data objects into Immuta and allow you to start dictating access through global policies.
Organize your data sources into domains and assign domain permissions to accountable teams: Use domains to segment your data and assign responsibilities to the appropriate team members. These domains will then be used in policies.
Register your users
These guides provide instructions on getting your users set up in Immuta.
Connect an IAM: Bring the IAM your organization already uses and allow Immuta to register your users for you.
Map external user IDs from Azure Synapse Analytics to Immuta: Ensure the user IDs in Immuta, Azure Synapse Analytics, and your IAM are aligned so that the right policies impact the right users.
Add data metadata
These guides provide instructions on getting your data metadata set up in Immuta.
Connect an external catalog: Bring the external catalog your organization already uses and allow Immuta to continually sync your tags with your data sources for you.
Run identification: Identification allows you to automate data tagging using identifiers that detect certain column names.
Start using policies
These guides provide instructions on using policies and audit for the first time.
Author a global subscription policy: Once you add your data metadata to Immuta, you can immediately create policies that utilize your tags and apply to your tables. Subscription policies can be created to dictate access to data sources.
Author a global data policy: Data metadata can also be used to create data policies that apply to data sources as they are registered in Immuta. Data policies dictate what data a user can see once they are granted access to a data source. Using catalog tags you can create proactive policies, knowing that they will apply to data sources as they are added to Immuta with the automated tagging.
: Once you have your data sources and users, and policies granting them access, you can set up audit export. This will export the audit logs from policy changes and tagging updates.
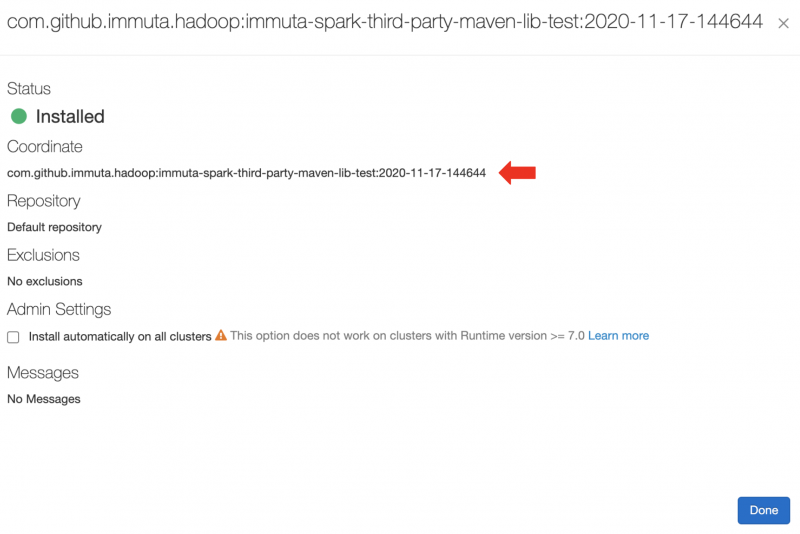
For Maven artifacts, the URI is maven:/<maven_coordinates>, where <maven_coordinates> is the Coordinates field found when clicking on the installed artifact on the Libraries tab in the Databricks Clusters UI. Here's an example of an installed artifact:
In this example, you would add the following Spark environment variable:
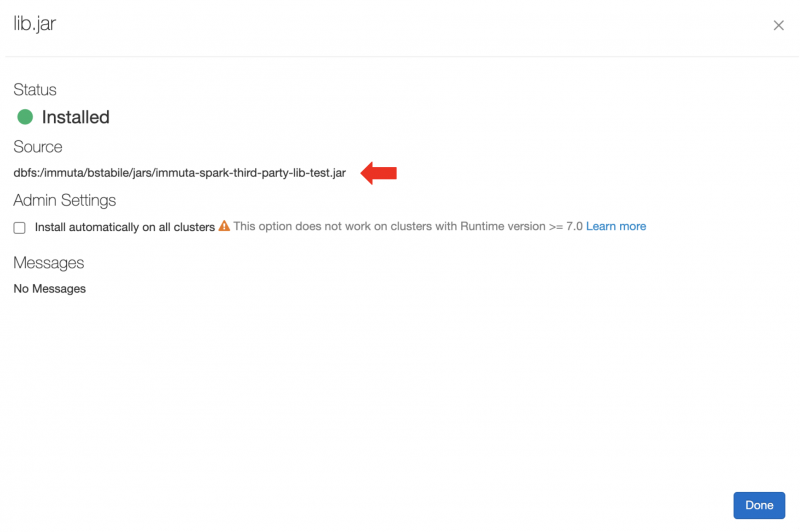
IMMUTA_SPARK_DATABRICKS_TRUSTED_LIB_URIS=maven:/com.github.immuta.hadoop.immuta-spark-third-party-maven-lib-test:2020-11-17-144644For jar artifacts, the URI is the Source field found when clicking on the installed artifact on the Libraries tab in the Databricks Clusters UI. For artifacts installed from DBFS or S3, this ends up being the original URI to your artifact. For uploaded artifacts, Databricks will rename your .jar and put it in a directory in DBFS. Here's an example of an installed artifact:
In this example, you would add the following Spark environment variable:
Once you've finished making your changes, restart the cluster.
Once the cluster is up, execute a command in a notebook. If the trusted library installation is successful, you should see driver log messages like this:
TrustedLibraryUtils: Successfully found all configured Immuta configured trusted libraries in Databricks.
TrustedLibraryUtils: Wrote trusted libs file to [/databricks/immuta/immutaTrustedLibs.json]: true.
TrustedLibraryUtils: Added trusted libs file with 1 entries to spark context.
TrustedLibraryUtils: Trusted library installation complete.Databricks Libraries API: Installing trusted libraries outside of the Databricks Libraries API (e.g., ADD JAR ...) is not supported.
IMMUTA_SPARK_DATABRICKS_TRUSTED_LIB_URIS=maven:/my.group.id:my-package-id:1.2.3Edit the field you want:
Host
Port
HTTP Path
Immuta System Catalog
HTTP Proxy settings
Authentication Method: If you are editing the authentication method to be a different service principal, grant the new service account the .
Select Validate, and once the validation is successful, select Save.
Click the Edit button in the Audit settings box.
Opt to enable or disable Query Audit: If you enable audit, ensure the system account has the required permissions for audit.
Select Validate, and once the validation is successful, select Save.
Click the Edit button in the Object Sync settings box.
Use the dropdown to select a new Start Time or Run Frequency.
Select Save.
Click the Edit button in the Data object settings box.
Opt to enable or disable Policy Sync: When policy sync is enabled, all child objects will be represented by Immuta data sources and policies will be applied to the data sources.
Opt to Add Users and Groups as data owners:
Start typing in the text box and select the user or group from the dropdown.
Click Add Owners.
Click Save.
The following guides offer practical guidance for handling common challenges and configurations.
Configure Ingress to complete your installation and access your Immuta application.
Configure TLS termination for an Ingress resource.
Verify artifacts hosted on the ocir.immuta.com OCI registry.
Follow these best practices when deploying Immuta in your production environment.
Update the credentials referenced in the Immuta Enterprise Helm chart.
Configure an external key-value cache (such as Redis or Memcached) with the Immuta Enterprise Helm chart.
Enable this legacy service for your deployment if you are using any of the legacy data platforms.
Configure pulling images from a private registry.
Tips when installing Immuta without internet access.
This guide demonstrates how to configure an external key-value cache (such as Redis or Memcached) with the Immuta Enterprise Helm chart (IEHC).
The Production best practices guide must be completed before proceeding.
Edit secret immuta-secret that was created in the Immuta in production guide.
kubectl edit secret/immuta-secretAdd key-value IMMUTA_SERVER_CACHE_PROVIDER_OPTIONS_PASSWORD=<cache-password>.
Edit the immuta-values.yaml file to include the relevant Helm values listed below. Update all with your own values.
Perform a to apply the changes made to immuta-values.yaml.
This page describes the Azure Synapse Analytics integration, through which Immuta applies policies directly in Azure Synapse Analytics. For a tutorial on configuring Azure Synapse Analytics see the Azure Synapse Integration page.
The Azure Synapse Analytics is a policy push integration that allows Immuta to apply policies directly in Azure Synapse Analytics Dedicated SQL pools without the need for users to go through a proxy. Instead, users can work within their existing Synapse Studio and have per-user policies dynamically applied at query time.
This integration works on a per-Dedicated-SQL-pool basis: all of Immuta's policy definitions and user entitlements data need to be in the same pool as the target data sources because Dedicated SQL pools do not support cross-database joins. Immuta creates schemas inside the configured Dedicated SQL pool that contain policy-enforced views that users query.
When the integration is configured, the Application Admin specifies the
Immuta database: This is the pre-existing database Immuta uses. Immuta will create views from the tables contained in this database, and all schemas and views created by Immuta will exist in this database, such as the schemas immuta_system, immuta_functions, and the immuta_procedures that contain the tables, views, UDFs, and stored procedures that support the integration.
Immuta schema: The schema that Immuta manages. All views generated by Immuta for tables registered as data sources will be created in this schema.
User profile delimiters: Since Azure Synapse Analytics dedicated SQL pools do not support array or hash objects, certain user access information is stored as delimited strings; the Application Admin can modify those delimiters to ensure they do not conflict with possible characters in strings.
For a tutorial on configuring the integration see the .
Synapse data sources are represented as views and are under one schema instead of a database, so their view names are a combination of their schema and table name, separated by an underscore.
For example, with a configuration that uses IMMUTA as the schema in the database dedicated_pool, the view name for the data source dedicated_pool.tpc.case would be dedicated_pool.IMMUTA.tpc_case.
You can see the view information on the data source details page under Connection Information.
This integration uses webhooks to keep views up-to-date with the corresponding Immuta data sources. When a data source or policy is created, updated, or disabled, a webhook is called that creates, modifies, or deletes the dynamic view in the Immuta schema. Note that only standard views are available because Azure Synapse Analytics Dedicated SQL pools do not support secure views.
The status of the integration is visible on the integrations tab of the Immuta application settings page. If errors occur in the integration, a banner will appear in the Immuta UI with guidance for remediating the error.
The definitions for each status and the state of configured data platform integrations is available in the . However, the UI consolidates these error statuses and provides detail in the error messages.
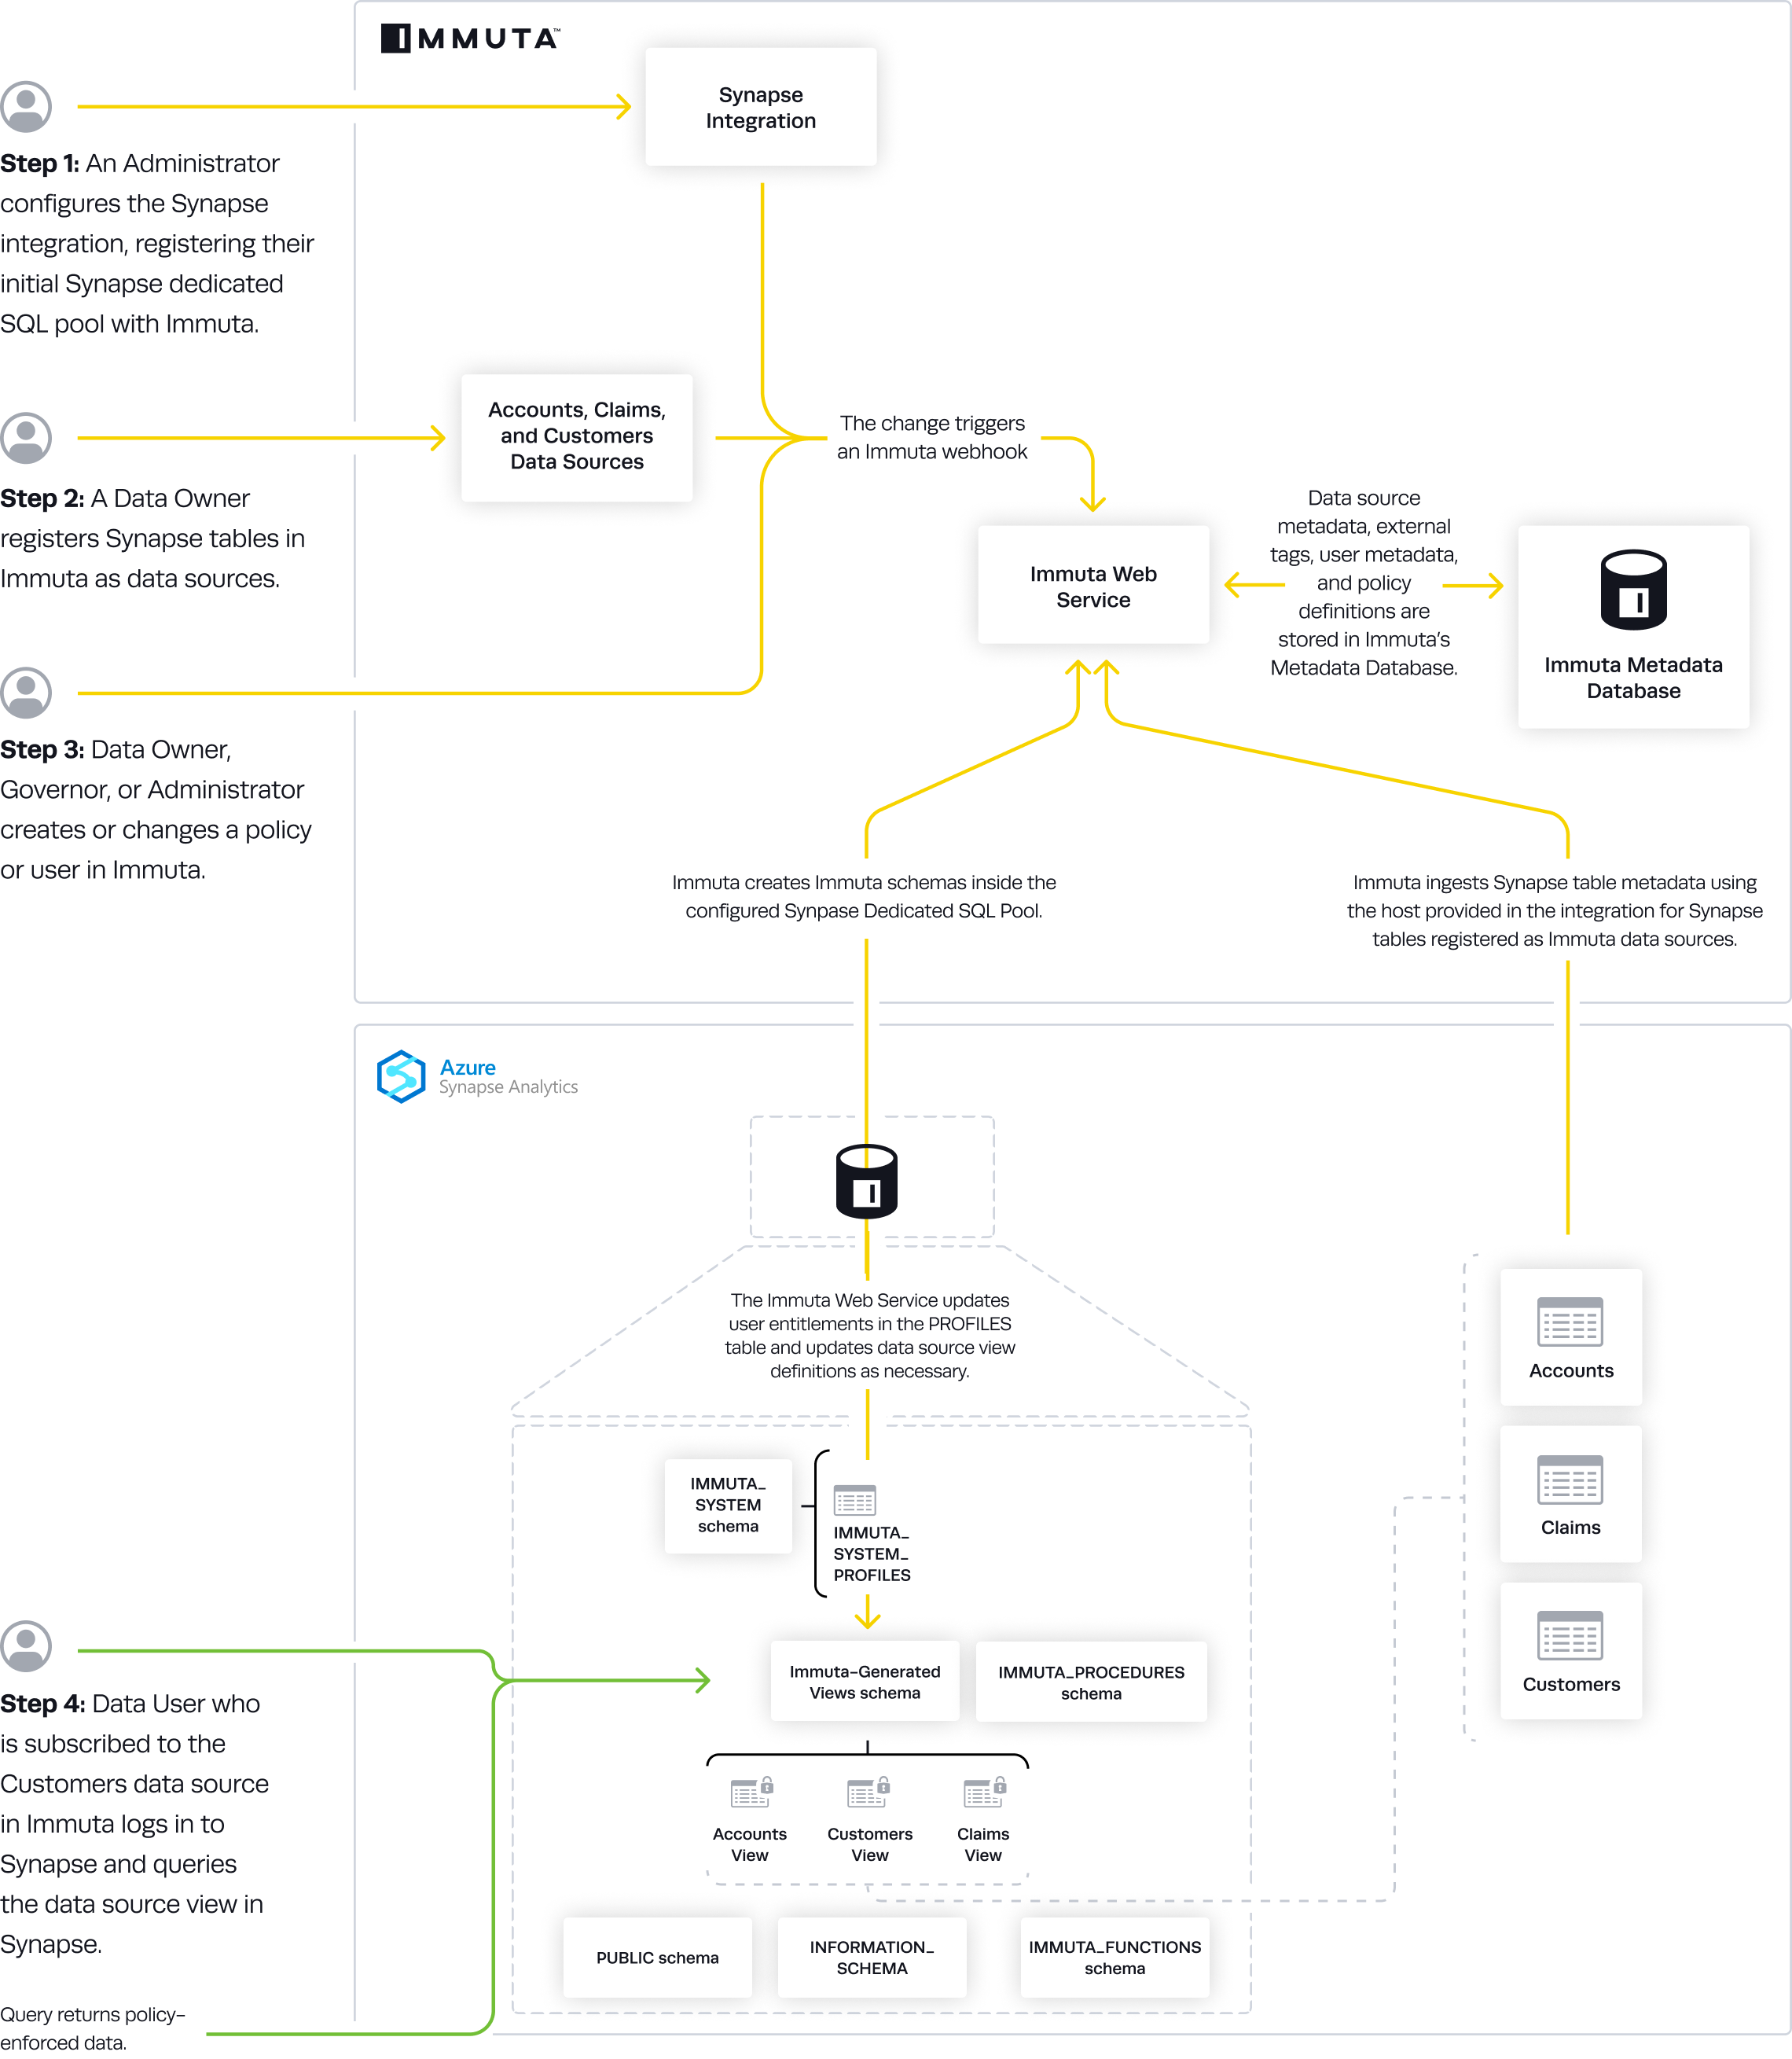
An Immuta Application Administrator , registering their initial Synapse Dedicated SQL pool with Immuta.
Immuta creates Immuta schemas inside the configured Synapse Dedicated SQL pool.
A Data Owner in Immuta as data sources. A Data Owner, Data Governor, or Administrator or in Immuta.
Data source metadata, tags, user metadata, and policy definitions are stored in Immuta's Metadata Database.
The how-to guides linked on this page illustrate how to integrate Databricks Spark with Immuta.
Requirements
If Databricks Unity Catalog is enabled in a Databricks workspace, you must use an Immuta cluster policy when you set up the Databricks Spark integration to create an Immuta-enabled cluster.
If Databricks Unity Catalog is not enabled in your Databricks workspace, you must disable Unity Catalog in your Immuta tenant before proceeding with your configuration of Databricks Spark:
Navigate to the App Settings page and click Integration Settings.
Uncheck the Enable Unity Catalog checkbox.
Click Save.
Connect your technology
These guides provide instructions for getting your data set up in Immuta.
.
Enable DBFS access in Databricks for non-sensitive data
This page outlines how to enable access to DBFS in Databricks for non-sensitive data. Databricks administrators should place the desired configuration in the Spark environment variables.
This Databricks feature mounts DBFS to the local cluster filesystem at /dbfs. Although disabled when using process isolation, this feature can safely be enabled if raw, unfiltered data is not stored in DBFS and all users on the cluster are authorized to see each other’s files. When enabled, the entirety of DBFS essentially becomes a scratch path where users can read and write files in /dfbs/path/to/my/file as though they were local files.
For example,
%sh echo "I'm creating a new file in DBFS" > /dbfs/my/newfile.txtIn Python,
%python
with open("/dbfs/my/newfile.txt", "w") as f:
f.write("I'm creating a new file in DBFS")Note: This solution also works in R and Scala.
To enable the DBFS FUSE mount, set this configuration in the Spark environment variables: IMMUTA_SPARK_DATABRICKS_DBFS_MOUNT_ENABLED=true.
Scratch paths will work when performing arbitrary remote filesystem operations with fs magic or Scala dbutils.fs functions. For example,
To support %fs magic and Scala DBUtils with scratch paths, configure
To use dbutils in Python, set this configuration: immuta.spark.databricks.py4j.strict.enabled=false.
This section illustrates the workflow for getting a file from a remote scratch path, editing it locally with Python, and writing it back to a remote scratch path.
Get the file from remote storage:
Make a copy if you want to explicitly edit localScratchFile, as it will be read-only and owned by root:
Write the new file back to remote storage:
Learn how to use Spark SQL to achieve the same functionality as the Delta Lake API
When using Delta Lake, the API does not go through the normal Spark execution path. This means that Immuta's Spark extensions do not provide protection for the API. To solve this issue and ensure that Immuta has control over what a user can access, the Delta Lake API is blocked.
Spark SQL can be used instead to give the same functionality with all of Immuta's data protections.
Below is a table of the Delta Lake API with the Spark SQL that may be used instead.
See here for a complete list of the .
When a table is created in a project workspace, you can merge a different Immuta data source from that workspace into that table you created.
.
Create a temporary view of the Immuta data source you want to merge into that table.
Use that temporary view as the data source you add to the project workspace.
Run the following command:
Learn how Databricks can enforce Immuta policies automatically across data in your Unity Catalog metastore
The how-to guides linked on this page illustrate how to integrate Databricks Unity Catalog with Immuta. See the reference guide for information about the Databricks Unity Catalog integration.
Requirements:
Unity Catalog metastore created and attached to a Databricks workspace. Immuta supports configuring a single metastore for each configured integration, and that metastore may be attached to multiple Databricks workspaces.
Unity Catalog enabled on your Databricks cluster or SQL warehouse. All SQL warehouses have Unity Catalog enabled if your workspace is attached to a Unity Catalog metastore.
Connect your technology
These guides provide instructions on getting your data set up in Immuta.
: Using a single setup process, connect Databricks Unity Catalog to Immuta. This will register your data objects into Immuta and allow you to start dictating access through global policies.
: Use domains to segment your data and assign responsibilities to the appropriate team members. These domains will then be used to manage permissions for publishing data products, authoring policies, viewing audit and managing identification.
Register your users
These guides provide instructions on getting your users set up in Immuta.
: Bring the IAM your organization already uses and allow Immuta to register your users for you.
: Ensure the user IDs in Immuta, Databricks, and your IAM are aligned so that the right policies impact the right users.
Add data metadata
These guides provide instructions on getting your data metadata set up in Immuta.
: Bring the external catalog your organization already uses and allow Immuta to continually sync your tags with your data sources for you.
: Identification allows you to automate data tagging using identifiers that detect certain data patterns.
Start using policy and audit
These guides provide instructions on using policy and audit for the first time.
: Once you add your data metadata to Immuta, you can immediately create policies that utilize your tags and apply to your tables. Subscription policies can be created to dictate access to data sources.
: Data metadata can also be used to create data policies that apply to data sources as they are registered in Immuta. Data policies dictate what data a user can see once they are granted access to a data source. Using catalog and identification tags you can create proactive policies, knowing that they will apply to data sources as they are added to Immuta with the automated tagging.
The how-to guides linked on this page illustrate how to integrate Redshift with Immuta. See the reference guide for information about the Redshift integration.
Requirement: Redshift cluster with an RA3 node is required for the multi-database integration. For other instance types, you may configure a single-database integration using one of the Redshift Spectrum options.
Connect your technology
These guides provide instructions on getting your data set up in Immuta.
Configure your Redshift integration: Configure a Redshift integration with Immuta so that Immuta can create policy protected views for your users to query.
: This will register your data objects into Immuta and allow you to start dictating access through global policies.
s: Use domains to segment your data and assign responsibilities to the appropriate team members. These domains will then be used in policies and identification.
Register your users
These guides provide instructions on getting your users set up in Immuta.
: Bring the IAM your organization already uses and allow Immuta to register your users for you.
: Ensure the user IDs in Immuta, Redshift, and your IAM are aligned so that the right policies impact the right users.
Add data metadata
These guides provide instructions on getting your data metadata set up in Immuta.
: Bring the external catalog your organization already uses and allow Immuta to continually sync your tags with your data sources for you.
: Identification allows you to automate data tagging using identifiers that detect certain data patterns.
Start using policies
These guides provide instructions on using policies and audit for the first time.
: Once you add your data metadata to Immuta, you can immediately create policies that utilize your tags and apply to your tables. Subscription policies can be created to dictate access to data sources.
: Data metadata can also be used to create data policies that apply to data sources as they are registered in Immuta. Data policies dictate what data a user can see once they are granted access to a data source. Using catalog and identification applied tags you can create proactive policies, knowing that they will apply to data sources as they are added to Immuta with the automated tagging.
Understand the authentication methods and audit features supported by the Snowflake integration to ensure you are meeting your organization's security and compliance needs
The Snowflake integration supports the following authentication methods to register a connection. The credentials provided must be for an account with the permissions listed in the Register a Snowflake connection guide.
Key pair
Snowflake External OAuth
Immuta's OAuth authentication method uses the Client Credentials Flow to integrate with Snowflake External OAuth. When a user configures the Snowflake integration, Immuta uses the token credentials (obtained using a certificate or passing a client secret) to craft an authenticated access token to connect with Snowflake. This allows organizations that already use Snowflake External OAuth to use that secure authentication with Immuta.
This is what will happen if you use Snowflake External OAuth to authenticate your Snowflake connection:
An Immuta application administrator registers the Snowflake connection.
Immuta creates a custom token and sends it to the authorization server.
The authorization server confirms the information sent from Immuta and issues an access token to Immuta.
Immuta sends the access token it received from the authorization server to Snowflake.
The built-in Immuta IAM can be used as a complete solution for authentication and user entitlement. However, you can connect your existing identity management provider to Immuta to use that system for authentication and user entitlement instead.
Each of the supported identity providers includes a specific set of configuration options that enable Immuta to communicate with the IAM system and map the users, permissions, groups, and attributes into Immuta.
See the for a list of supported providers and details.
See the for details about user provisioning and mapping user accounts to Immuta.
Immuta provides auditing features and governance reports so that data owners and governors can monitor users' access to data and detect anomalies in behavior.
You can view the information in these audit logs on .
See the for details about these capabilities and how they work with the Snowflake integration.
Immuta captures queries in Snowflake, making audit records more useful in assessing what users are doing. To audit Snowflake queries, Immuta runs a query in Snowflake to retrieve user query histories. Those histories are then populated into comprehensive audit logs. Immuta will only audit queries from Immuta users on objects registered as Immuta data sources.
Query audit can be . Audit ingestion will run at the schedule set on the . Audit ingestion can be manually requested at any time from the Immuta audit page. When manually requested, it will only search for new queries that were created since the last query that had been audited. The job is run in the background, so the new queries will not be immediately available.
See the for details about the contents of the logs and an example of the resulting audit record.
Immuta governance reports allow users with the GOVERNANCE Immuta permission to use a natural language builder to instantly create reports that delineate user activity across Immuta. These reports can be based on various entity types, including users, groups, projects, data sources, purposes, policy types, or connection types.
See the page for a list of report types and guidance.
The guides in this section illustrate how to install and deploy Immuta in your Kubernetes environment.
Get started quickly with these essential guides. For a more comprehensive understanding and advanced configurations, explore the full suite of guides.
Complete the guide that corresponds with your Kubernetes cluster's distribution.
: This guide includes instructions for
Amazon Elastic Kubernetes Service (EKS)
Google Kubernetes Engine (GKE)
Microsoft Azure Kubernetes Service (AKS)
Complete the guide.
Complete the guide.
Immuta integrates with your data platforms so you can register your data and effectively manage access controls on that data.
This section includes guidance for connecting your data platform and keeping it synced with Immuta.
This reference guide outlines the features, policies, and audit capabilities of each data platform Immuta supports.
The guides in these sections include information about how to connect your data platform to Immuta:
This reference guide outlines the actions and features that trigger Immuta queries in your remote platform that may incur cost.
Immuta integrates with your data platforms so you can register your data and effectively manage access controls on that data. This section includes concept, reference, and how-to guides for registering and managing data sources.
Manage Snowflake integration and connection settings
Navigate to the connection or connection-backed object.
Click Run Object Sync.
Click the Edit button in the Connection details box.
Edit the field you want:
Host
Port
Warehouse
Role: If you edit the role, ensure the new role has the
Select Validate, and once the validation is successful, select Save.
Click the Edit button in the Policy settings box.
Opt to enable or disable Impersonation.
Enter the Impersonation Role.
Select Validate, and once the validation is successful, select
Click the Edit button in the Audit settings box.
Opt to enable or disable Query Audit: If you enable audit, ensure the system account has the .
Select Validate, and once the validation is successful, select Save.
Click the Edit button in the Object settings box.
Opt to enable or disable Policy Synchronization: When policy sync is enabled, all child objects will be represented by Immuta data sources and policies will be applied to the data sources.
Opt to Add Users and Groups as data owners:
Immuta is compatible with Snowflake Secure Data Sharing. Using both Immuta and Snowflake, organizations can share the policy-protected data of their Snowflake database with other Snowflake accounts with Immuta policies enforced in real time. This integration gives data consumers a live connection to the data and relieves data providers of the legal and technical burden of creating static data copies that leave their Snowflake environment.
Requirements:
Snowflake Enterprise Edition or higher
This method requires that the data consumer account is registered as an Immuta user with the Snowflake user name equal to the consuming account.
At that point, the user that represents the account being shared with can have the appropriate attributes and groups assigned to them, relevant to the data policies that need to be enforced. Once that user has access to the share in the consuming account (not managed by Immuta), they can query the share with the data policies from the producer account enforced because Immuta is treating that account as if they are a single user in Immuta.
For a tutorial on this workflow, see the .
Using Immuta with Snowflake Data Sharing allows the sharer to
Only need limited knowledge of the context or goals of the existing policies in place: Because the sharer is not editing or creating policies to share their data, they only need a limited knowledge of how the policies work. Their main responsibility is making sure they properly represent the attributes of the data consumer (the account being shared to).
Leave policies untouched.
Manage Trino integration and connection settings
Navigate to the connection or connection-backed object.
Click Run Object Sync.
Click the Edit button in the Connection details box.
Edit the field you want:
Hostname
Port
SSL Mode
Certificate Validation
Select Validate, and once the validation is successful, select Save.
Click the Edit button in the Object Sync settings box.
Opt to enable or disable object sync.
Opt to update the Start Time and Run Frequency from the dropdown menus.
Opt for all data objects to be scanned despite the policy sync setting using the checkbox.
Click the Edit button in the Object settings box.
Opt to enable or disable Policy Synchronization: When policy sync is enabled, all child objects will be represented by Immuta data sources and policies will be applied to the data sources.
Opt to Add Users and Groups as data owners:
Immuta is compatible with Snowflake Secure Data Sharing. Using both Immuta and Snowflake, organizations can share the policy-protected data of their Snowflake database with other Snowflake accounts with Immuta policies enforced in real time.
Prerequisite
Required Permission: Immuta: GOVERNANCE
Build Immuta data policies to fit your organization's compliance requirements.
It's important to understand that subscription policies are not relevant to Snowflake data shares, because the act of sharing the data is the subscription policy. Data policies can be enforced on the consuming account from the producer account on a share following these instructions.
Required Permission: Immuta: USER_ADMIN
To register the Snowflake data consumer in Immuta,
.
to match the account ID for the data consumer. This value is the output on the data consumer side when SELECT CURRENT_ACCOUNT() is run in Snowflake.
for your organization's policies.
.
Required Permission: Snowflake ACCOUNTADMIN
To share the policy-protected data source,
of the Snowflake table that has been registered in Immuta.
Grant reference usage on the Immuta database to the share you created:
Replace the content in angle brackets above with the name of your Immuta database and Snowflake data share.
Manually update your Databricks cluster to reflect changes in cluster policies or the Immuta init script
If a Databricks cluster needs to be manually updated to reflect changes in the Immuta init script or cluster policies, you can remove and set up your integration again to get the updated policies and init script.
Log in to Immuta as an Application Admin.
Click the App Settings icon in the navigation menu and scroll to the Integration Settings section.
Your existing Databricks Spark integration should be listed here; expand it and note the configuration values. Now select Remove to remove your integration.
Click Add Integration and select Databricks Integration to add a new integration.
Enter your Databricks Spark integration settings again as configured previously.
Click Add Integration to add the integration, and then select Configure Cluster Policies to set up the updated cluster policies and init script.
Select the cluster policies you wish to use for your Immuta-enabled Databricks clusters.
Automatically push cluster policies and the init script (recommended) or manually update your cluster policies.
Automatically push cluster policies
Select Automatically Push Cluster Policies and enter your privileged Databricks access token. This token must have privileges to write to cluster policies.
Restart any Databricks clusters using these updated policies for the changes to take effect.
This guide demonstrates how to point the Immuta Enterprise Helm chart (IEHC) at a private container registry.
If the images keep their original repository paths (for example, stable/immuta-service stays stable/immuta-service), the only value required is the registry itself:
global:
imageRegistry: <private-registry-fqdn>If your registry imposes a path prefix (common with Artifactory or Harbor project layouts), map each repository with global.imageRepositoryMap. Do not override each component's image.repository individually:
global:
imageRegistry: <private-registry-fqdn>
imageRepositoryMap:
stable/immuta-service: <prefix>/stable/immuta-service
stable/audit-service: <prefix>/stable/audit-service
# ...one entry per repositoryList every repository the chart references:
helm show values oci://ocir.immuta.com/stable/immuta-enterprise --version 2026.2.0 | grep 'repository:' | sort -uIf your private registry requires authentication, create a pull secret and reference it globally:
kubectl create secret docker-registry immuta-private-registry \
--docker-server=<private-registry-fqdn> \
--docker-username=<username> \
--docker-password=<password>global:
imagePullSecrets:
- name: immuta-private-registryThis guide demonstrates how to update credentials referenced in the Immuta Enterprise Helm chart (IEHC).
Validate that secret immuta-secret exists in the current namespace.
Edit secret immuta-secret in place.
When installing Immuta, these are the supported options for getting audit logs from events in Immuta:
This page describes the Azure Synapse integration, configuration options, and features. See the for a tutorial on enabling the integration and these features through the app settings page.
Understand the authentication methods and audit features supported by the Databricks Unity Catalog integration to ensure you are meeting your organization's security and compliance needs
The Databricks Unity Catalog integration supports the following authentication methods to register a connection. The credentials provided must be for an account with the permissions listed in the .
Personal access token (PAT)
OAuth machine-to-machine (M2M)
The built-in Immuta IAM can be used as a complete solution for authentication and user entitlement. However, you can connect your existing identity management provider to Immuta to use that system for authentication and user entitlement instead.
Each of the supported identity providers includes a specific set of configuration options that enable Immuta to communicate with the IAM system and map the users, permissions, groups, and attributes into Immuta.
Snowflake table grants simplifies the management of privileges in Snowflake when using Immuta. Instead of having to manually grant users access to tables registered in Immuta, you allow Immuta to manage privileges on your Snowflake tables and views according to subscription policies. Then, users subscribed to a data source in Immuta can view and query the Snowflake table, while users who are not subscribed to the data source cannot view or query the Snowflake table.
Enabling Snowflake table grants gives the following privileges to the Immuta Snowflake role:
MANAGE GRANTS ON ACCOUNT allows the Immuta Snowflake role to grant and revoke SELECT privileges on Snowflake tables and views that have been added as data sources in Immuta.
The warehouse you select when configuring the Snowflake integration uses compute resources to set up the integration, register data sources, orchestrate policies, and run jobs like identification. Snowflake credit charges are based on the size of and amount of time the warehouse is active, not the number of queries run.
This document prescribes how and when to adjust the size and scale of clusters for your warehouse to manage workloads so that you can use Snowflake compute resources the most cost effectively.
In general, increase the size of and number of clusters for the warehouse to handle heavy workloads and multiple queries. Workloads are typically lighter after data sources are onboarded and policies are established in Immuta, so compute resources can be reduced after those workloads complete.
The Snowflake integration uses warehouse compute resources to sync policies created in Immuta to the Snowflake objects registered as data sources and, if enabled, to run and . Follow the guidelines below to adjust the warehouse size and scale according to your needs.
Increase the of and of clusters for the warehouse during large policy syncs, updates, and changes.
Enable Snowflake tag ingestion to pull Snowflake tags and apply them to data sources
To allow Immuta to automatically import table and column tags from Snowflake, enable Snowflake tag ingestion in the external catalog section of the Immuta app settings page.
Requirements
A configured Snowflake connection
The Snowflake user configuring the Snowflake tag ingestion must have the following privileges and should be able to access all securables registered as data sources:
Rotate the system API key to mitigate potential security risks
When you register the Trino connection, Immuta generates an API key for you to add to your Immuta access control properties file for API authentication between Starburst (Trino) and Immuta. You can rotate this shared secret to mitigate potential security risks and comply with your organizational policies.
Required Immuta permission: APPLICATION_ADMIN
.
Navigate to the Trino connection in Immuta.
indices:admin/create
indices:admin/delete
indices:admin/settings/update
indices:admin/get
indices:admin/refresh
indices:admin/refresh*
indices:admin/mapping/put
indices:data/read/search
indices:data/read/scroll
indices:data/read/scroll/clear
indices:data/write/delete
indices:data/write/delete/byquery
indices:data/write/index
indices:data/write/bulk
indices:data/write/bulk*
indices:data/write/update/byquery
indices:monitor/settings/get
Click Save and Confirm to deploy your changes.
Manually update cluster policies
Download the init script and the new cluster policies to your local computer.
Click Save and Confirm to save your changes in Immuta.
Log in to your Databricks workspace with your administrator account to set up cluster policies.
Get the path you will upload the init script (immuta_cluster_init_script_proxy.sh) to by opening one of the cluster policy .json files and looking for the defaultValue of the field init_scripts.0.dbfs.destination. This should be a DBFS path in the form of dbfs:/immuta-plugin/hostname/immuta_cluster_init_script_proxy.sh.
Click Data in the left pane to upload your init script to DBFS to the path you found above.
To find your existing cluster policies you need to update, click Compute in the left pane and select the Cluster policies tab.
Edit each of these cluster policies that were configured before and overwrite the contents of the JSON with the new cluster policy JSON you downloaded.
HTTP Proxy
Authentication Method: If you are editing the authentication method to be a different system account user, grant the new system user the required permissions.
Click Save.
Click Add Owners.
Click Save.
Configure audit: Once you have your data sources and users, and policies granting them access, you can set up audit export. This will export the audit logs from user queries, policy changes, and tagging updates.
Configure audit: Once you have your data sources and users, and policies granting them access, you can set up audit export. This will export the audit logs from policy changes and tagging updates.
Snowflake authenticates the token and grants access to the requested resources from Immuta.
The integration is connected and users can query data.
Scroll to the Policy settings section, and select Edit.
Click Regenerate system API key. The old API key will be invalidated immediately.
Copy the new immuta.apikey. Store it in a secure place; the API key will not be shown again.
Click Finish.
Cluster restart required
To update your API key in Starburst (Trino), you must shut down your cluster, generate and update the API key, and then restart your cluster. If you do not shut down your cluster, generating a new API key using the endpoint below will cause downtime for your deployment.
The Immuta Web Service calls a stored procedure that modifies the user entitlements or policies and updates data source view definitions as necessary.
An Azure Synapse Analytics user who is subscribed to the data source in Immuta queries the corresponding data source view in Azure Synapse Analytics and sees policy-enforced data.
See the Identity managers guide for a list of supported providers and details.
See the Databricks Unity Catalog integration reference guide for details about user provisioning and mapping user accounts to Immuta.
Immuta provides auditing features and governance reports so that data owners and governors can monitor users' access to data and detect anomalies in behavior.
You can view the information in these audit logs on dashboards.
See the Audit documentation for details about these capabilities and how they work with the Databricks Unity Catalog integration.
Immuta uses Databricks tables from the system catalog to understand the queries users make and present them in the query audit logs.
The audit ingest is set when registering the connection and can be scoped to only ingest specific workspaces if needed. The default ingest frequency is every 24 hours, but this can be configured to a different frequency on the Immuta app settings page. Additionally, audit ingestion can be manually requested at any time from the Immuta audit page. When manually requested, it will only search for new queries that were created since the last query that had been audited. The job is run in the background, so the new queries will not be immediately available.
See the Databricks Unity Catalog audit page for details about the contents of the logs and an example of the resulting audit record.
Immuta governance reports allow users with the GOVERNANCE Immuta permission to use a natural language builder to instantly create reports that delineate user activity across Immuta. These reports can be based on various entity types, including users, groups, projects, data sources, purposes, policy types, or connection types.
See the Governance report types page for a list of report types and guidance.
HTTP Proxy
Authentication Method: If you are editing the authentication method to be a different system account user, grant the new system user the connection role and the role created from the setup script.
Object Synchronization: Use the dropdown to select a new Start Time or Run Frequency.
Click Add Owners.
Click Save.
DeltaTable.convertToDelta
CONVERT TO DELTA parquet./path/to/parquet/
DeltaTable.delete
DELETE FROM [table_identifier delta./path/to/delta/] WHERE condition
DeltaTable.generate
GENERATE symlink_format_manifest FOR TABLE [table_identifier delta./path/to/delta]
DeltaTable.history
DESCRIBE HISTORY [table_identifier delta./path/to/delta] (LIMIT x)
DeltaTable.merge
MERGE INTO
DeltaTable.update
UPDATE [table_identifier delta./path/to/delta/] SET column = valueWHERE (condition)
DeltaTable.vacuum
VACUUM [table_identifier delta./path/to/delta]
Enable auto-suspend and auto-resume to optimize resource use in Snowflake. In the Snowflake UI, the lowest auto suspend time setting is 5 minutes. However, through SQL query, you can set auto_suspend to 61 seconds (since the minimum uptime for a warehouse is 60 seconds). For example,
Identification uses compute resources for each table it runs on. Consider turning off autoscanning for your domains with identifiers and dynamic assignment when registering data sources if you have an external catalog available or a tagging strategy in place.
Register data before creating global policies. Immuta does not apply a subscription policy on registered data unless an existing global policy applies to it, which allows Immuta to only pull metadata instead of also applying policies when data sources are created. Registering data before policies are created reduces the workload and the Snowflake compute resources needed.
Begin onboarding with a small dataset of tables, and then review and monitor query performance in the Snowflake Query Monitor. Adjust the virtual warehouse accordingly to handle heavier loads.
Schema monitoring uses the compute warehouse that was employed during the initial ingestion to periodically monitor the schema for changes. If you expect a low number of new tables or minimal changes to the table structure, consider scaling down the warehouse size.
Resize the warehouse after data sources are registered and policies are established. For example,
For more details and guidance about warehouse sizing, see the Snowflake Warehouse Considerations documentation.
Even after your integration is configured, data sources are registered, and policies are established, changes to those data sources or policies may initiate heavy workloads. Follow the guidelines below to adjust your warehouse size and scale according to your needs.
Review your Snowflake query history to identify query performance and bottlenecks.
Check how many credits queries have consumed:
After reviewing query performance and cost, implement strategies above to adjust your warehouse.
IMMUTA_SPARK_DATABRICKS_TRUSTED_LIB_URIS=dbfs:/immuta/bstabile/jars/immuta-spark-third-party-lib-test.jarcache:
enabled: false
secure:
extraConfig:
server:
cache:
provider:
constructor: catbox-redis
options:
host: <redis-fqdn>
port: <port>
# Setting options.tls to an empty dict enables TLS without configuring any other options.
tls: {}
# Dict representation of TLS config options json-object for package ioredis
# https://github.com/redis/ioredis
#
# tls:
# ca:
# key:
# cert:
extraEnvVars:
- name: IMMUTA_SERVER_CACHE_PROVIDER_OPTIONS_PASSWORD
valueFrom:
secretKeyRef:
key: IMMUTA_SERVER_CACHE_PROVIDER_OPTIONS_PASSWORD
name: immuta-secretcache:
enabled: false
secure:
extraConfig:
server:
cache:
provider:
constructor: catbox-memcached
options:
host: <memcached-fqdn>
port: <port>helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0%fs put -f s3://my-bucket/my/scratch/path/mynewfile.txt "I'm creating a new file in S3"
%scala dbutils.fs.put("s3://my-bucket/my/scratch/path/mynewfile.txt", "I'm creating a new file in S3") <property>
<name>immuta.spark.databricks.scratch.paths</name>
<value>s3://my-bucket/my/scratch/path</value>
</property>%python
import os
import shutil
s3ScratchFile = "s3://some-bucket/path/to/scratch/file"
localScratchDir = os.environ.get("IMMUTA_LOCAL_SCRATCH_DIR")
localScratchFile = "{}/myfile.txt".format(localScratchDir)
localScratchFileCopy = "{}/myfile_copy.txt".format(localScratchDir)dbutils.fs.cp(s3ScratchFile, "file://{}".format(localScratchFile))shutil.copy(localScratchFile, localScratchFileCopy)
with open(localScratchFileCopy, "a") as f:
f.write("Some appended file content")dbutils.fs.cp("file://{}".format(localScratchFileCopy), s3ScratchFile)MERGE INTO delta_native.target_native as target
USING immuta_temp_view_data_source as source
ON target.dr_number = source.dr_number
WHEN MATCHED THEN
UPDATE SET target.date_reported = source.date_reportedGRANT REFERENCE_USAGE ON DATABASE "<Immuta database of the provider account>" TO SHARE "<DATA_SHARE>";ALTER WAREHOUSE "WH_NAME" SET WAREHOUSE_SIZE = 'XSMALL' AUTO_SUSPEND = 61 AUTO_RESUME = TRUE MIN_CLUSTER_COUNT = 1 MAX_CLUSTER_COUNT = 2 SCALING_POLICY = 'STANDARD' COMMENT = '';SELECT h.* FROM "SNOWFLAKE"."ACCOUNT_USAGE"."QUERY_HISTORY" h
INNER JOIN "SNOWFLAKE"."ACCOUNT_USAGE"."SESSIONS" s
ON s.session_id = h.session_id
WHERE GET(parse_json(s.client_environment), 'APPLICATION') = 'IMMUTA' limit 25;ALTER WAREHOUSE "INTEGRATION_WH" SET WAREHOUSE_SIZE = 'XSMALL' AUTO_SUSPEND = 120 AUTO_RESUME = TRUE MIN_CLUSTER_COUNT = 1 MAX_CLUSTER_COUNT = 2 SCALING_POLICY = 'STANDARD'; Register your users
These guides provide instructions on setting up your users in Immuta.
Integrate an IAM with Immuta: Connect the IAM your organization already uses and allow Immuta to register your users for you.
Map external user IDs from Databricks to Immuta: Ensure the user IDs in Immuta, Databricks, and your IAM are aligned so that the right policies impact the right users.
Add data metadata
These guides provide instructions on getting your data metadata set up in Immuta for use in policies.
Connect an external catalog: Connect the external catalog your organization already uses and allow Immuta to continually sync your tags with your data sources for you.
Run identification: Identification allows you to automate data tagging using identifiers that detect certain data patterns.
Protect and monitor data access
These guides provide instructions on authoring policies and auditing data access.
Author a global subscription policy: Once you add your data metadata to Immuta, you can immediately create policies that utilize your tags and apply to your tables. Subscription policies can be created to dictate access to data sources.
Author a global data policy: Data metadata can also be used to create data policies that apply to data sources as they are registered in Immuta. Data policies dictate what data a user can see once they are granted access to a data source. Using catalog and identification applied tags you can create proactive policies, knowing that they will apply to data sources as they are added to Immuta with the automated tagging.
: Once you have your data sources and users, and policies granting them access, you can set up audit export. This will export the audit logs from user queries, policy changes, and tagging updates.
immuta-legacy-secretRestart pods.
kubectl rollout restart deployment --selector "app.kubernetes.io/component in (audit, secure)"Validate that secret immuta-legacy-secret exists in the current namespace.
kubectl get secret/immuta-legacy-secretGet the query engine replica count, this value will be referenced in subsequent step(s).
kubectl get statefulset --all --selector "app.kubernetes.io/component=query-engine" --output template='{{ .status.replicas }}'Scale the replica count down to 1.
kubectl scale statefulset --all --replicas 1 --selector "app.kubernetes.io/component=query-engine"Get the query engine pod name, this value will be referenced in subsequent step(s).
Update the with a query engine superuser password.
Update the with a query engine replication password.
Update the with a query engine feature password.
Scale the replica count back up to the previous value by updating the .
Update credentials in the immuta-values.yaml file.
Perform a Helm upgrade to apply the changes made to immuta-values.yaml. Update the placeholder value with your own release name.
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0kubectl get secret/immuta-secretkubectl edit secret/immuta-secretkubectl edit secret/immuta-legacy-secretConnect a SIEM integration to the audit-service pod and use STDOUT to stream audit logs from the container to your SIEM provider. The Helm chart is configured for this by default.
To clear up noise, you can filter the log collection on a custom log level to audit. This will ensure only audit events are collected.
Use your preferred method to export the audit logs from the external Elasticsearch you have configured with your deployment.
The retention period for audit logs in Elasticsearch or OpenSearch is 7 days. However, this is configurable in your database. Before deploying Immuta, set the following in the immuta-values.yaml to configure audit retention. This example updates audit retention to 90 days:
The Immuta UI supports a maximum retention period of 90 days. Any audit logs older than 90 days will not appear in the UI.
The audit-service requires Elasticsearch or OpenSearch to function. If your deployment does not include Elasticsearch or OpenSearch, audit-service must be turned off. See the following deployment examples with the set dependencies and the resulting functionality.
Deployment 1
✅
✅
Full product and audit functionality
See the Requirements page for a high-level overview of the Immuta deployment requirements.
audit-service enabled
Elasticsearch or OpenSearch
audit-service enabled
Elasticsearch or OpenSearch
audit:
init:
extraEnvVars:
- name: AUDIT_RETENTION_POLICY_IN_DAYS
value: "90"The recommended option is to stream logs out of Kubernetes for your audit needs.
✅
❌
✅
A running dedicated SQL pool
The Azure Synapse Analytics integration supports the following authentication methods to configure the integration and create data sources:
Username and password: Immuta supports SQL authentication with username and password for Azure Synapse Analytics. See the SQL Authentication in Azure Synapse Analytics documentation for details.
OAuth authentication with Microsoft Entra ID: You can use this authentication method to register data sources or configure the Azure Synapse Analytics integration using the manual setup method. To use this authentication method, OAuth must be set up via Microsoft Entra ID app registration with a client secret. See the Microsoft Entra documentation for details about using OAuth authentication with Microsoft Entra ID.
Immuta cannot ingest tags from Synapse, but you can connect any of these supported external catalogs to work with your integration.
Impersonation allows users to query data as another Immuta user in Azure Synapse Analytics. To enable user impersonation, see the Configure Azure Synapse Analytics integration guide.
A user can configure multiple integrations of Synapse to a single Immuta tenant.
Immuta does not support the following masking types in this integration because of limitations with dedicated SQL pools (linked below). Any column assigned one of these masking types will be masked to NULL:
Reversible Masking: Synapse UDFs currently only support SQL, but Immuta needs to execute code (such as JavaScript or Python) to support this masking feature. See the Synapse Documentation for details.
Format Preserving Masking: Synapse UDFs currently only support SQL, but Immuta needs to execute code (such as JavaScript or Python) to support this masking feature. See the Synapse Documentation for details.
Regex: The built in string replace function does not support full regex. See the .
The delimiters configured when enabling the integration cannot be changed once they are set. To change the delimiters, the integration has to be disabled and re-enabled.
If the generated view name is more than 128 characters, then the view name is shortened to 128 characters. This could cause collisions between view names if the shortened version is the same for two different data sources.
For proper updates, the dedicated SQL pools have to be running when changes are made to users or data sources in Immuta.
❌
❌
CREATE ROLE ON ACCOUNT allows for the creation of a Snowflake role for each user in Immuta, enabling fine-grained, attribute-based access controls to determine which tables are available to which individuals.Since table privileges are granted to roles and not to users in Snowflake, Immuta's Snowflake table grants feature creates a new Snowflake role for each Immuta user. This design allows Immuta to manage table grants through fine-grained access controls that consider the individual attributes of users.
Each Snowflake user with an Immuta account will be granted a role that Immuta manages. The naming convention for this role is <IMMUTA>_USER_<username>, where
<IMMUTA> is the prefix you specified when enabling the feature on the Immuta app settings page.
<username> is the user's Immuta username.
Users are granted access to each Snowflake table or view automatically when they are subscribed to the corresponding data source in Immuta.
Users have two options for querying Snowflake tables that are managed by Immuta:
Use the role that Immuta creates and manages. (For example, USE ROLE IMMUTA_USER_<username>. See the section above for details about the role and name conventions.) If the current active primary role is used to query tables, USAGE on a Snowflake warehouse must be granted to the Immuta-managed Snowflake role for each user.
USE SECONDARY ROLES ALL, which allows users to use the privileges from all roles that they have been granted, including IMMUTA_USER_<username>, in addition to the current active primary role. Users may also set a value for DEFAULT_SECONDARY_ROLES as an object property on a Snowflake user. To learn more about primary roles and secondary roles in Snowflake, see Snowflake documentation.
Immuta uses an algorithm to determine the most optimal way to group users in a role hierarchy in order to optimize the number of GRANTs (or REVOKES) executed in Snowflake. This is done by determining the least amount of possible permutations of access across tables and users based on the policies in place; then, those become intermediate roles in the hierarchy that each user is added to, based on the intermediate roles they belong to.
As an example, take the below users and data sources they have access to. To do this naively by individually granting every user to the tables they have access to would result in 37 grants:
Conversely, using the Immuta algorithm, we can optimize the number of grants in the same scenario down to 29:
It’s important to consider a few things here:
If the permutations of access are small, there will be a huge optimization realized (very few intermediate roles). If every user has their own unique permutation of access, the optimization will be negligible (an intermediate role per user). It is most common that the number of permutations of access will be many multiples smaller than the actual user count, so there should be large optimizations. In other words, a much smaller number of intermediate roles and the number of total overall grants reduced, since the tables are granted to roles and roles to users.
This only happens once up front. After that, changes are incremental based on policy changes and user attribute changes (smaller updates), unless there’s a policy that makes a sweeping change across all users. The addition of new users who have access becomes much more straightforward also due to the fact above. User’s access will be granted via the intermediate role, and, therefore, a lot of the work is front loaded in the intermediate role creation.
If an Immuta tenant is connected to an external IAM and that external IAM has a username identical to another username in Immuta's built-in IAM, those users will have the same Snowflake role, leading both to see the same data.
Sometimes the role generated can contain special characters such as @ because it's based on the user name configured from your identity manager. Because of this, it is recommended that any code references to the Immuta-generated role be enclosed with double quotes.
IMPORTED PRIVILEGES ON DATABASE snowflake
APPLY TAG ON ACCOUNT
Navigate to the App Settings page.
Scroll to 2 External Catalogs, and click Add Catalog.
Enter a Display Name and select Snowflake from the dropdown menu.
Enter the Account.
Enter the Authentication information based on your authentication method:
Username and password: Fill out Username and Password.
Key pair:
Enter the additional Snowflake details: Port, Default Warehouse, and Role.
Opt to enter the Proxy Host and Proxy Port.
Click the Test Connection button.
Click the Test Data Source Link.
Once both tests are successful, click Save.
This guide demonstrates how to configure TLS termination for an Ingress resource.
The Ingress configuration must be completed before proceeding.
Edit immuta-values.yaml to include the following Helm values.
gateway:
ingress:
hostname: <immuta-fqdn>
annotations:
nginx.ingress.kubernetes.io/auth-tls-secret: <namespace>/<secret-name>Create a TLS secret from a given public/private PEM formatted key pair.
kubectl create secret tls <secret-name> --cert=path/to/tls.cert --key=path/to/tls.keyPerform a to apply the changes made to immuta-values.yaml.
Refer to the for further assistance.
Edit immuta-values.yaml to include the following Helm values.
Perform a to apply the changes made to immuta-values.yaml.
Refer to the for further assistance.
Edit immuta-values.yaml to include the following Helm values.
Perform a to apply the changes made to immuta-values.yaml.
Refer to the for further assistance.
Edit immuta-values.yaml to include the following Helm values.
Perform a to apply the changes made to immuta-values.yaml.
Refer to the for further assistance.
Edit immuta-values.yaml to include the following Helm values.
from a given public/private PEM formatted key pair.
Perform a to apply the changes made to immuta-values.yaml.
Refer to the for further assistance.
The query engine is no longer installed by default. This guide demonstrates how to enable the query engine using the Immuta Enterprise Helm chart (IEHC).
If you are using any of the legacy data platforms, you must enable the query engine.
The Immuta in production guide must be completed before proceeding.
Validate that secret immuta-secret exists in the current namespace.
kubectl get secret/immuta-secretCreate a file named secret-data.env with the following content.
Create secret named immuta-legacy-secret from file secret-data.env
Delete file secret-data.env, as it's no longer needed.
Edit the immuta-values.yaml file to include the following Helm values.
Update all in the immuta-values.yaml file.
Perform a to apply the changes made to immuta-values.yaml.
This guide demonstrates how to move the Immuta Enterprise Helm chart and its container images into an environment with no internet access. Two artifacts cross the boundary:
The Helm chart archive (.tgz)
The container images, copied by digest into archive files
The same process applies to the initial install and to every upgrade: Each release is one chart archive plus one set of images.
Every image is copied by digest, taken from the DIGESTS.md file inside the chart itself. A digest is content-addressed, so an image that arrives in your registry with the expected digest is bit-for-bit the image Immuta published; the transfer method cannot silently alter it.
and on both the connected machine and a machine inside the air-gapped environment (skopeo moves the images; Helm pulls the chart on one side and installs it on the other).
On the connected machine, skopeo and Helm are authenticated with ocir.immuta.com. Credentials are provided by Immuta; there is currently no self-service lookup. Contact your Immuta representative or if you do not have them.
On the air-gapped machine, skopeo is authenticated with your private registry.
Download the Helm chart.
Extract DIGESTS.md (the chart's own manifest of every image it references, with digests) and convert it into a plain image list.
Each line of images.txt is <image>:<tag> <digest>. This file travels with the archives and drives every later step.
(Optional) Verify Immuta's signature on each image before archiving, following the
Move the immuta-2026.2.0 directory into the air-gapped environment using your organization's approved transfer process. Everything needed is in that one directory: the chart archive, images.txt, and one .tar per image.
Push every image to your private registry, preserving each image's repository path and digest. Replace <private-registry-fqdn> with your registry.
If your registry requires a path prefix (for example, an Artifactory repository), push to <private-registry-fqdn>/<prefix>/${path} instead, verify the same location in the next step, and map the repositories as described in the .
Verify the pushed images. Every digest in your registry must equal the digest in images.txt. Any mismatch fails loudly.
Point the chart at your registry. Because the repository paths were preserved, pointing the chart at your registry is a single value — no per-image overrides:
If your registry requires authentication, also create a pull secret and set global.imagePullSecrets, as described in the . The credentials skopeo used to push are not used by Kubernetes to pull.
If your registry requires a path prefix (for example, an Artifactory repository), map the repositories instead of overriding each image. See the for details.
Install or upgrade from the local chart archive. Wherever other guides reference oci://ocir.immuta.com/stable/immuta-enterprise, substitute the archive path and omit --version
This page provides a tutorial for enabling the Azure Synapse Analytics integration on the Immuta app settings page. To configure this integration via the Immuta API, see the Integrations API getting started guide.
For an overview of the integration, see the Azure Synapse Analytics overview documentation.
A running Dedicated SQL pool is required.
If you are using the OAuth authentication method,
Ensure that Microsoft Entra ID is on the same account as the Azure Synapse Analytics workspace and dedicated SQL pool.
Select Accounts in this organizational directory only as the account type.
Click the App Settings icon in the navigation menu.
Click the Integrations tab.
Click the +Add Integration button and select Azure Synapse Analytics from the dropdown menu.
Complete the Host,
You have two options for configuring your Azure Synapse Analytic environment:
: Grant Immuta one-time use of credentials to automatically configure your environment and the integration.
: Run the Immuta script in your Azure Synapse Analytics environment yourself to configure the integration.
Enter the username and password in the Privileged User Credentials section.
Select Manual.
Download, fill out the appropriate fields, and run the bootstrap master script and bootstrap script linked in the Setup section. Note: The master script is not required if you're using the OAuth authentication method.
Select the authentication method:
Click Save.
.
Click the App Settings icon in the navigation menu.
Navigate to the Integrations tab and click the down arrow next to the Azure Synapse Analytics Integration.
Edit the field you want to change. Note any field shadowed is not editable, and the integration must be disabled and re-installed to change it.
Use the authentication method and credentials you provided when initially configuring the integration.
Click the App Settings icon in the navigation menu.
Navigate to the Integrations tab and click the down arrow next to the Azure Synapse Analytics Integration.
Click the checkbox to disable the integration.
Enter the credentials that were used to initially configure the integration.
Learn about Immuta's integrations for Databricks
Immuta offers two integrations for Databricks:
Databricks Unity Catalog integration: This integration supports working with database objects registered in Unity Catalog.
Databricks Spark integration: This integration supports working with database objects registered in the legacy Hive metastore.
To determine which integration you should use, evaluate the following elements:
Cluster runtime
Databricks Runtime 11.3 and newer: See the list below to determine which integration is supported for your data's location.
Location of data: Where is your data?
Legacy Hive metastore: Databricks recommends that you migrate all data from the legacy Hive metastore to Unity Catalog. However, when this migration is not possible, use the to protect securables registered in the Hive metastore.
Unity Catalog: To protect securables registered in the Unity Catalog metastore, use the .
Databricks metastore magic allows you to migrate your data from the Databricks legacy Hive metastore to the Unity Catalog metastore while protecting data and maintaining your current processes in a single Immuta instance.
Databricks metastore magic is for organizations who intend to use the , but must still protect tables in the Hive metastore until they can migrate all of their data to Unity Catalog.
Unity Catalog support is enabled in Immuta.
Databricks has two built-in metastores that contain metadata about your tables, views, and storage credentials:
Legacy Hive metastore: Created at the workspace level. This metastore contains metadata of the registered securables in that workspace available to query.
Unity Catalog metastore: Created at the account level and is attached to one or more Databricks workspaces. This metastore contains metadata of the registered securables available to query. All clusters on that workspace use the configured metastore and all workspaces that are configured to use a single metastore share those securables.
Databricks allows you to use the legacy Hive metastore and the Unity Catalog metastore simultaneously. However, Unity Catalog does not support controls on the Hive metastore, so you must attach a Unity Catalog metastore to your workspace and move existing databases and tables to the attached Unity Catalog metastore to use the governance capabilities of Unity Catalog.
Immuta's Databricks Spark integration and Unity Catalog integration enforce access controls on the Hive and Unity Catalog metastores, respectively. However, because these metastores have two distinct security models, users were discouraged from using both in a single Immuta instance before metastore magic; the Databricks Spark integration and Unity Catalog integration were unaware of each other, so using both concurrently caused undefined behavior.
Metastore magic reconciles the distinct security models of the legacy Hive metastore and the Unity Catalog metastore, allowing you to use multiple metastores (specifically, the Hive metastore or alongside Unity Catalog metastores) within a Databricks workspace and single Immuta instance and keep policies enforced on all your tables as you migrate them. The diagram below shows Immuta enforcing policies on registered tables across workspaces.
In clusters A and D, Immuta enforces policies on data sources in each workspace's Hive metastore and in the Unity Catalog metastore shared by those workspaces. In clusters B, C, and E (which don't have Unity Catalog enabled in Databricks), Immuta enforces policies on data sources in the Hive metastores for each workspace.
With metastore magic, the Databricks Spark integration enforces policies only on data in the Hive metastore, while the Unity Catalog integration enforces policies on tables in the Unity Catalog metastore.
To enforce plugin-based policies on Hive metastore tables and Unity Catalog native controls on Unity Catalog metastore tables, enable the and the Databricks Unity Catalog integration. Note that some Immuta policies are not supported in the Databricks Unity Catalog integration. See the for details.
Databricks SQL cannot run the Databricks Spark plugin to protect tables, so Hive metastore data sources will not be policy enforced in Databricks SQL.
To enforce policies on data sources in Databricks SQL, use to manually lock down Hive metastore data sources and the Databricks Unity Catalog integration to protect tables in the Unity Catalog metastore. Table access control is enabled by default on SQL warehouses, and any Databricks cluster without the Immuta plugin must have table access control enabled.
Learn about user impersonation and how to map your Databricks users into Immuta
When the Databricks Spark plugin is running on a Databricks cluster, all Databricks users running jobs or queries are either a privileged user or a non-privileged user:
Privileged users: Privileged users can effectively read from and write to any table or view in the cluster Metastore, or any file path accessible by the cluster, without restriction. Privileged users are either Databricks workspace admins or users specified in IMMUTA_SPARK_ACL_ALLOWLIST. Any user writing queries or jobs impersonating another user is a non-privileged user, even if they are impersonating a privileged user.
Privileged users have effective authority to read from and write to any securable in the cluster metastore or file path, because in almost all cases Databricks clusters running with the Immuta Spark plug-in installed have disabled Hive metastore table access control. However, if Hive metastore table access control is enabled on the cluster, privileged users will have the authority granted to them that is specified by table access control.
Non-privileged users: Non-privileged users are any users who are not privileged users, and all authorization for non-privileged users is determined by Immuta policies.
Whether a user is a privileged user or a non-privileged user, for a given query or job, is cached once first determined, based on . This caching can be disabled entirely by setting the value of that environment variable to 0.
Usernames in Databricks must match the usernames in the connected Immuta tenant. By default, the Immuta Spark plugin checks the Databricks username against the username within Immuta's internal IAM to determine access. However, you can integrate your existing IAM with Immuta and use that instead of the default internal IAM. Ideally, you should use the same identity manager for Immuta that you use for Databricks. See the for a list of supported identity providers and protocols.
It is possible within Immuta to have multiple users share the same username if they exist within different IAMs. In this case, the cluster can be configured to look up users from a specified IAM. To do this, the value of the must be updated to be the targeted IAM ID configured within the Immuta tenant. The targeted IAM ID can be found on the . Each Databricks cluster can only be mapped to one IAM.
Databricks user impersonation allows a Databricks user to impersonate an Immuta user. With this feature,
the Immuta user who is being impersonated does not have to have a Databricks account, but they must have an Immuta account.
the Databricks user who is impersonating an Immuta user does not have to be associated with Immuta. For example, this could be a service account.
When acting under impersonation, the Databricks user loses their privileged access, so they can only access the tables the Immuta user has access to and only perform DDL commands when that user is acting under an allowed circumstance (such as workspaces, scratch paths, or non-Immuta reads/writes).
Use the to enable user impersonation.
Audited queries include an impersonationUser field, which identifies the Databricks user impersonating the Immuta user:
Learn how end users can access policy-enforced data in Databricks Spark
Once a Databricks securable is registered in Immuta as a data source and you are subscribed to that data source, you must access that data through SQL:
df = spark.sql("select * from immuta.table")import org.apache.spark.sql.SparkSession
%sql
select * from immutalibrary(SparkR)
df <- SparkRWith R, you must load the SparkR library in a cell before accessing the data.
See the sections below for more guidance on accessing data using Delta Lake, direct file reads in Spark for file paths, and user impersonation.
When using Delta Lake, the API does not go through the normal Spark execution path. This means that Immuta's Spark extensions do not provide protection for the API. To solve this issue and ensure that Immuta has control over what a user can access, the Delta Lake API is blocked.
Spark SQL can be used instead to give the same functionality with all of Immuta's data protections. See the for a list of corresponding Spark SQL calls to use.
In addition to supporting direct file reads through workspace and scratch paths, Immuta allows direct file reads in Spark for file paths. As a result, users who prefer to interact with their data using file paths or who have existing workflows revolving around file paths can continue to use these workflows without rewriting those queries for Immuta.
When reading from a path in Spark, the Immuta Databricks Spark plugin queries the Immuta Web Service to find Databricks data sources for the current user that are backed by data from the specified path. If found, the query plan maps to the Immuta data source and follows existing code paths for policy enforcement.
Users can read data from individual parquet files in a sub-directory and partitioned data from a sub-directory (or by using a where predicate). Expand the blocks below to view examples of reading data using these methods.
Direct file reads for Immuta data sources only apply to data sources created from tables, not data sources created from views or queries.
If more than one data source has been created for a path, Immuta will use the first valid data source it finds. It is therefore not recommended to use this integration when more than one data source has been created for a path.
In Databricks, multiple input paths are supported as long as they belong to the same data source.
CSV-backed tables are not currently supported.
User impersonation allows Databricks users to query data as another Immuta user. To impersonate another user, see the .
If you're using AWS OpenSearch in your Immuta installation, use this how-to to set up the proper access and permissions needed for AWS role authentication.
An OpenSearch domain
The user setting up the permissions must have the following permissions:
Administrative access to your AWS account
Complete prerequisites and create R and Scala spark-submit jobs
This guide illustrates how to run R and Scala spark-submit jobs on Databricks, including prerequisites and caveats.
Before you can run spark-submit jobs on Databricks, complete the following steps.
Initialize the Spark session:
Enter these settings into the R submit script to allow the R script to access Immuta data sources, scratch paths, and workspace tables:
Understand the authentication methods, cluster security, and audit features supported by the Databricks Spark integration to ensure you are meeting your organization's security and compliance needs
Immuta offers several features to provide security for your users and Databricks clusters and to prove compliance and monitor for anomalies.
Immuta supports the following authentication methods to configure the Databricks Spark integration and register data sources:
OAuth machine-to-machine (M2M): Immuta uses the to integrate with , which allows Immuta to authenticate with Databricks using a client secret. Once Databricks verifies the Immuta service principal’s identity using the client secret, Immuta is granted a temporary OAuth token to perform token-based authentication in subsequent requests. When that token expires (after one hour), Immuta requests a new temporary token. See the for more details.
Allow Immuta to create secure views of your external tables through one of these methods:
that contains the external tables: Instead of creating an immuta database that manages all schemas and views created when Redshift data is registered in Immuta, the integration adds the Immuta-managed schemas and views to an existing database in Redshift
and re-create all of your external tables in that database.
For an overview of the integration, see the documentation.
This page provides an overview of the Redshift integration in Immuta. For a tutorial detailing how to enable this integration, see the .
Redshift is a policy push integration that allows Immuta to apply policies directly in Redshift. This allows data analysts to query Redshift views directly instead of going through a proxy and have per-user policies dynamically applied at query time.
The Redshift integration will create views from the tables within the database specified when configured. Then, the user can choose the name for the schema where all the Immuta generated views will reside. Immuta will also create the schemas immuta_system, immuta_functions, and immuta_procedures to contain the tables, views, UDFs, and stored procedures that support the integration. Immuta then creates a system role and gives that system account the following privileges:
Learn how end users can access policy-enforced data in Snowflake
Once data is registered through the Snowflake connection, you will access your data through your Snowflake queries as you normally would. If you are subscribed to the data source, Immuta grants you access to the data in Snowflake.
When you submit a query, the Snowflake client submits the SQL query to the Snowflake server, which then processes the query and determines what data your role is allowed to see. Then, the Snowflake server queries the database and returns the query results to the Snowflake client, which then returns policy-enforced data to you.
The diagram below illustrates how Immuta, the Snowflake server, and Snowflake client interact to access data.
Because subscription policies are managed through roles, you must be acting under the role Immuta creates for you to get access to your subscribed data sources. When querying data in Snowflake, do one of the following:
that Immuta creates and manages. (For example, USE ROLE <prefix>_USER_<username>
Learn about how you can register data from Starburst (Trino) and govern access to that data
This page describes the recommended workflow for setting up Immuta with Starburst (Trino). Following these steps connects your Starburst (Trino) environment, registers users, ingests metadata, and enables automated governance through global policies and access requests.
To complete this workflow, ensure you have:
Access to a Starburst (Trino) account and the permissions required to configure the connection
Access to install a plugin on your Trino cluster
Click Upload Certificates to enter in the Certificate Authority, Certificate File, and Key File.
Close the modal and opt to enter the Encrypted Key File Passphrase.
Deployment 2
✅
❌
Unsupported configuration
Deployment 3
❌
❌
Functional product with no audit
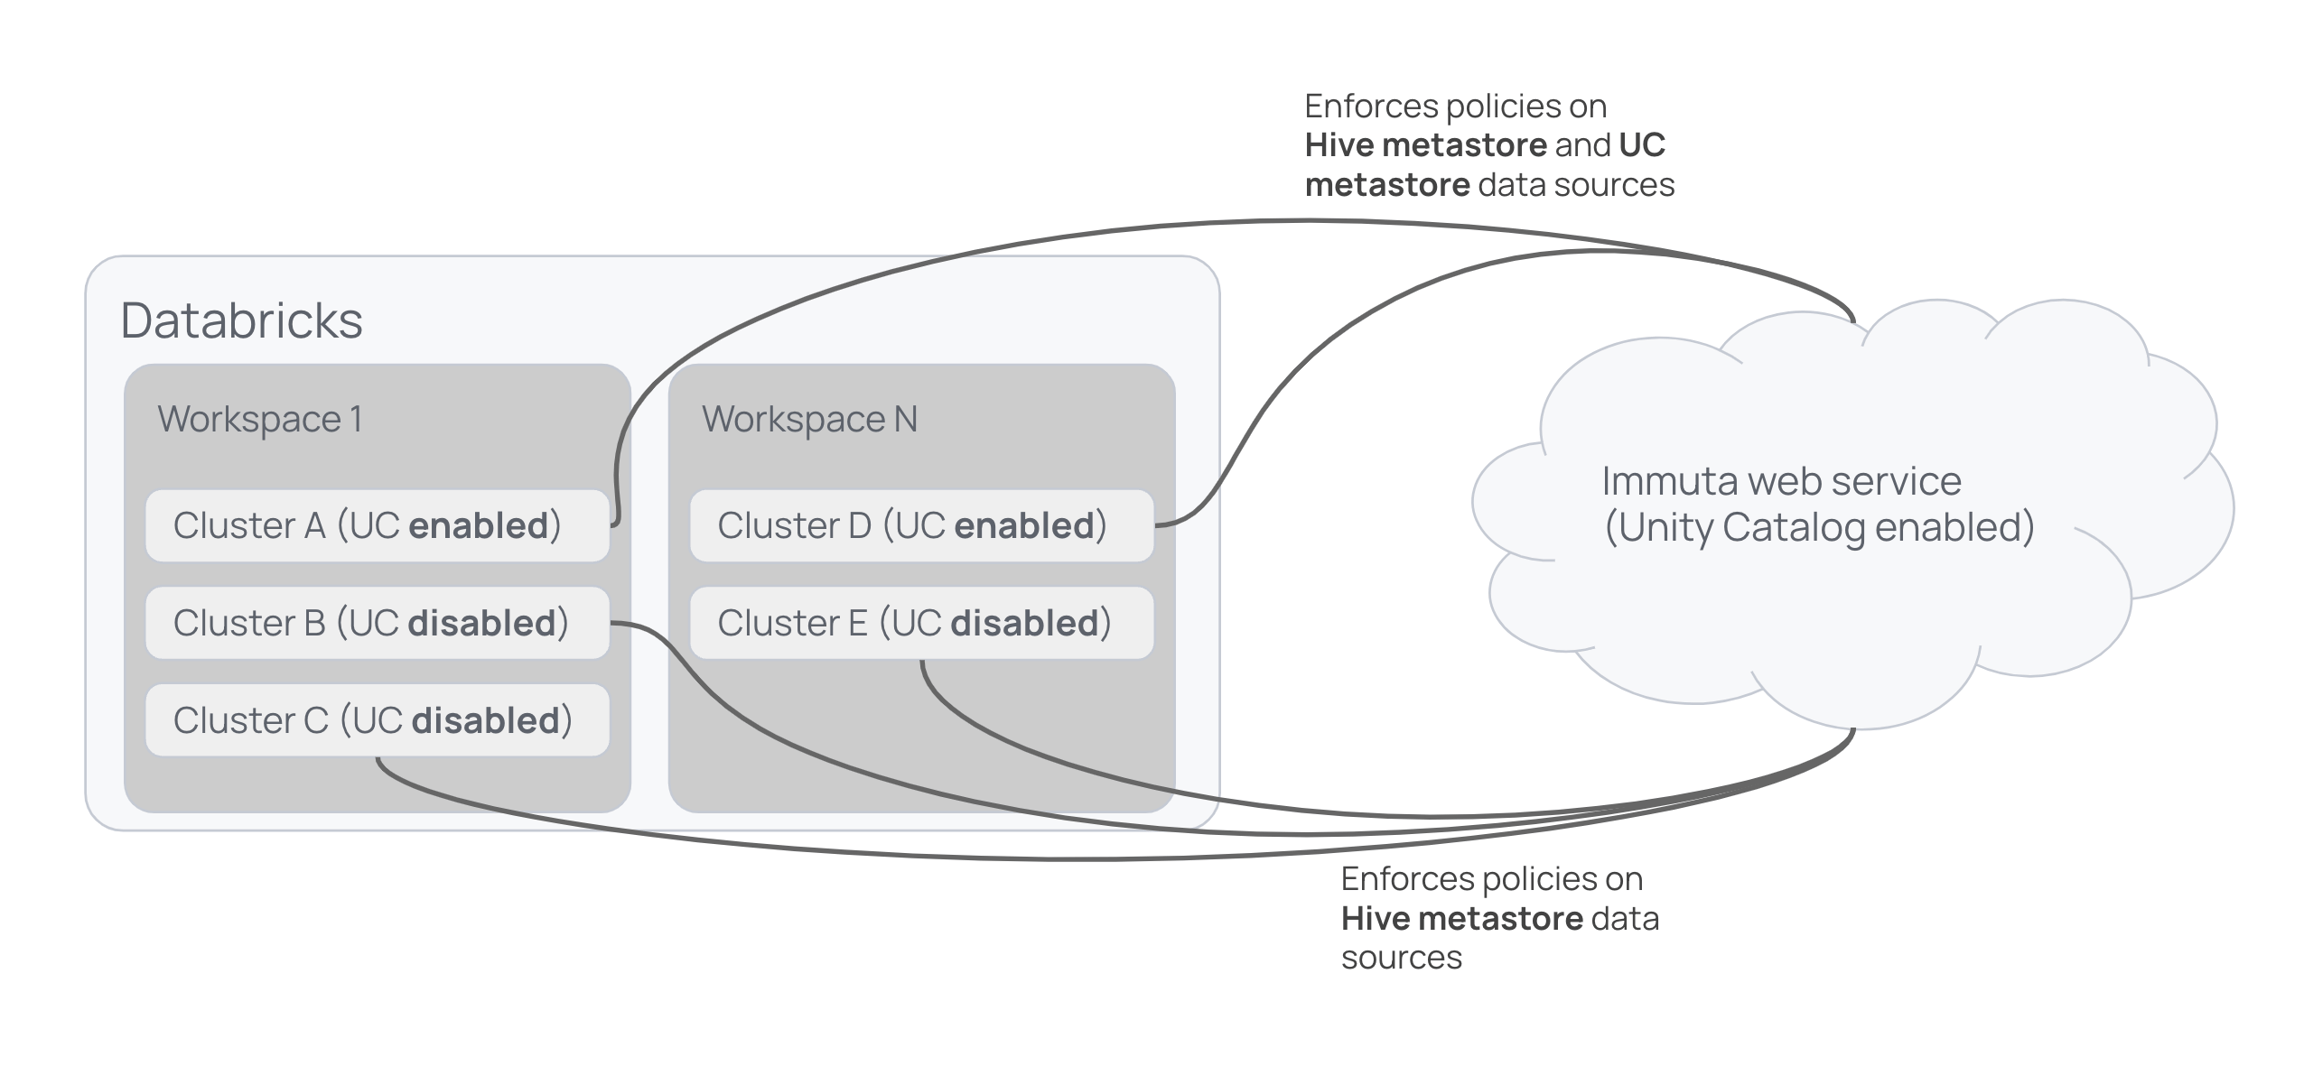
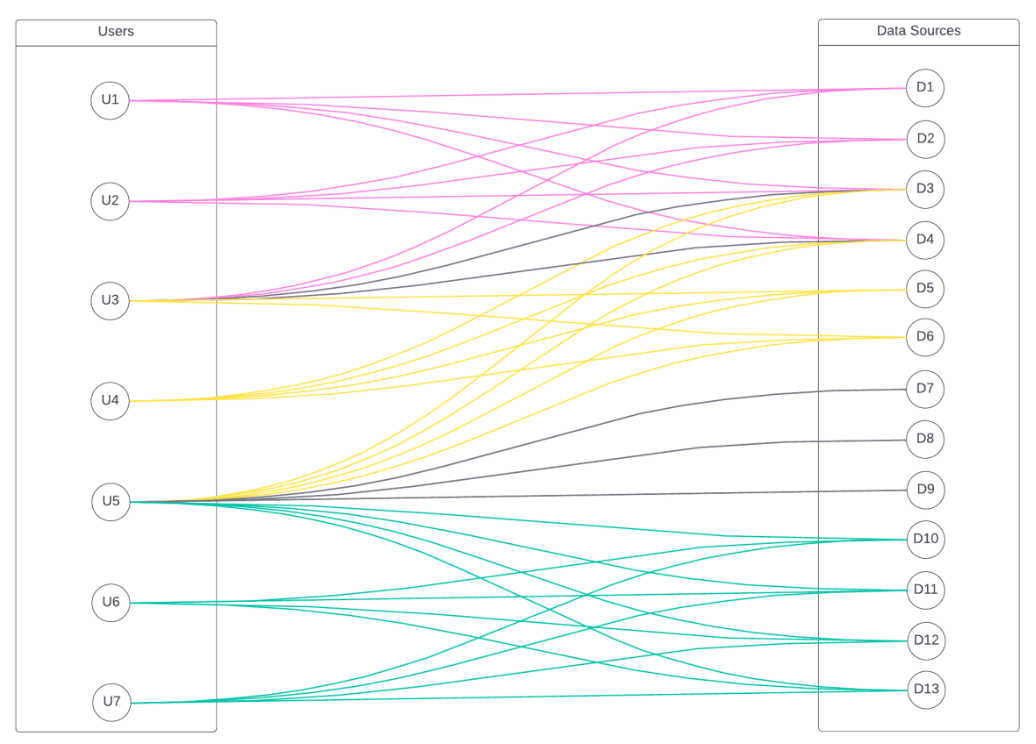
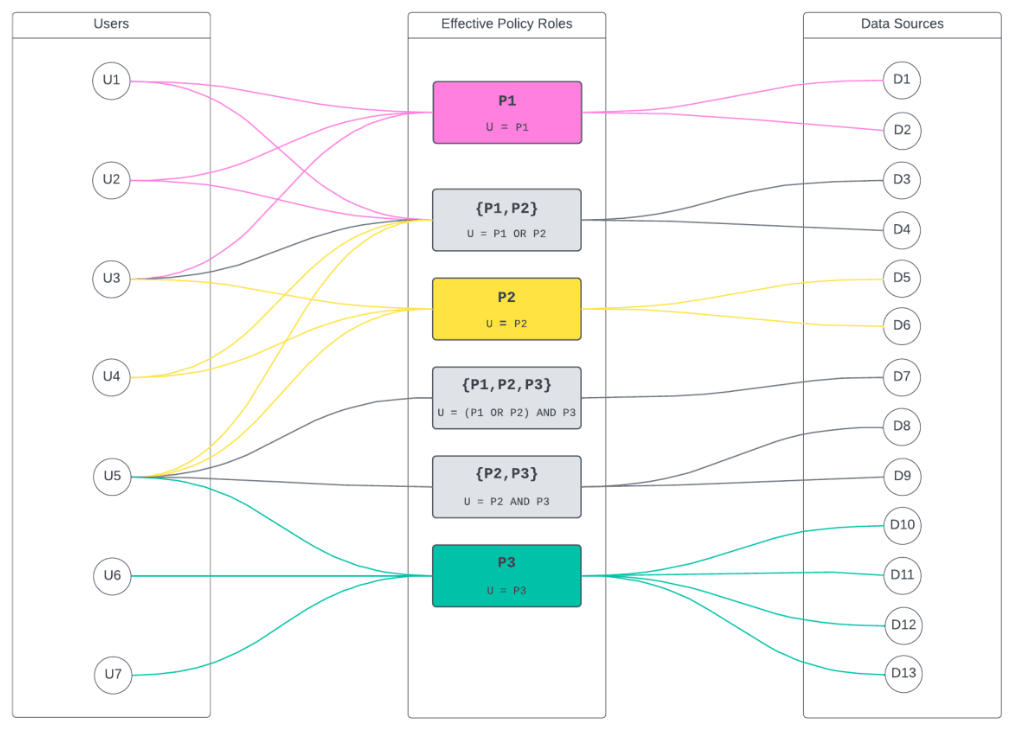
Loading a delta partition from a sub-directory is not recommended by Spark and is not supported in Immuta. Instead, use a where predicate:
Avoid these special characters in generated passwords
whitespace, $, &, :, \, /, ', "
Scala clusters
Immuta discourages use of this feature with Scala clusters, as the proper security mechanisms were not built to account for user isolation limitations in Scala clusters. Instead, this feature was developed for the BI tool use case in which service accounts connecting to the Databricks cluster need to impersonate Immuta users so that policies can be enforced.
Archive every image, by digest, in one pass. --all preserves every architecture; --preserve-digests makes skopeo fail rather than alter content. A failed copy stops the loop, so a partial bundle cannot be mistaken for a complete one.
The built-in Immuta IAM can be used as a complete solution for authentication and fine-grained user entitlement. However, you can connect your existing identity management provider to Immuta to use that system for authentication and fine-grained user entitlement instead.
Each of the supported identity providers includes a specific set of configuration options that enable Immuta to communicate with the IAM system and map the users, permissions, groups, and attributes into Immuta.
See the Identity managers guide for a list of supported providers and details.
See the Setting up users guide for details and instructions on mapping Databricks user accounts to Immuta.
See the Data processing, encryption, and masking practices guide for more information about transmission of policy decision data, encryption of data in transit and at rest, and encryption key management.
Non-administrator users on an Immuta-enabled Databricks cluster must not have access to view or modify Immuta configuration, as this poses a security loophole around Immuta policy enforcement. Databricks secrets allow you to securely apply environment variables to Immuta-enabled clusters.
Databricks secrets can be used in the environment variables configuration section for a cluster by referencing the secret path instead of the actual value of the environment variable.
See the Installation and compliance guide for details and instructions on using Databricks secrets.
There are limitations to isolation among users in Scala jobs on a Databricks cluster. When data is broadcast, cached (spilled to disk), or otherwise saved to SPARK_LOCAL_DIR, it's impossible to distinguish between which user’s data is composed in each file/block. To address this vulnerability, Immuta suggests that you
limit Scala clusters to Scala jobs only and
require equalized projects, which will force all users to act under the same set of attributes, groups, and purposes with respect to their data access. This requirement guarantees that data being dropped into SPARK_LOCAL_DIR will have policies enforced and that those policies will be homogeneous for all users on the cluster. Since each user will have access to the same data, if they attempt to manually access other users' cached/spilled data, they will only see what they have access to via equalized permissions on the cluster. If project equalization is not turned on, users could dig through that directory and find data from another user with heightened access, which would result in a data leak.
See the Installation and compliance guide for more details and configuration instructions.
Immuta provides auditing features and governance reports so that data owners and governors can monitor users' access to data and detect anomalies in behavior.
You can view the information in these audit logs on dashboards or configure your Immuta deployment with audit for long-term backup and processing with log data processors and tools. This capability fosters convenient integrations with log monitoring services and data pipelines.
See the Audit documentation for details about these capabilities and how they work with the Databricks Spark integration.
Immuta captures the code or query that triggers the Spark plan in Databricks, making audit records more useful in assessing what users are doing.
To audit what triggers the Spark plan, Immuta hooks into Databricks where notebook cells and JDBC queries execute and saves the cell or query text. Then, Immuta pulls this information into the audits of the resulting Spark jobs.
Immuta will audit queries that come from interactive notebooks, notebook jobs, and JDBC connections, but will not audit Scala or R submit jobs. Furthermore, Immuta only audits Spark jobs that are associated with Immuta tables. Consequently, Immuta will not audit a query in a notebook cell that does not trigger a Spark job, unless IMMUTA_SPARK_AUDI_ALL_QUERIES is set to true.
See the Databricks Spark query audit logs page for examples of saved queries and the resulting audit records. To exclude query text from audit events, see the App settings page.
Immuta supports auditing all queries run on a Databricks cluster, regardless of whether users touch Immuta-protected data or not.
See the Installation and compliance guide for details and instructions.
When a query is run by a user impersonating another user, the extra.impersonationUser field in the audit log payload is populated with the Databricks username of the user impersonating another user. The userId field will return the Immuta username of the user being impersonated:
See the Setting up users guide for details about user impersonation.
Immuta governance reports allow users with the GOVERNANCE Immuta permission to use a natural language builder to instantly create reports that delineate user activity across Immuta. These reports can be based on various entity types, including users, groups, projects, data sources, purposes, policy types, or connection types.
See the Governance report types page for a list of report types and guidance.
# Not recommended by Spark and not supported in Immuta
spark.read.format("delta").load("s3:/my_bucket/path/to/my_delta_table/partition_column=01")
# Recommended by Spark and supported in Immuta.
spark.read.format("delta").load("s3:/my_bucket/path/to/my_delta_table").where("partition_column=01")
kubectl get pod --selector "app.kubernetes.io/component=query-engine"kubectl exec pod/<query-engine-pod-name> -- \
psql -d immuta -c \
"ALTER USER postgres WITH ENCRYPTED PASSWORD '<new-patroni-superuser-password>'"kubectl exec pod/<query-engine-pod-name> -- \
psql -d immuta -c \
"ALTER USER replicator WITH ENCRYPTED PASSWORD '<new-patroni-replication-password>'"kubectl exec pod/<query-engine-pod-name> -- \
psql -d immuta -c \
"ALTER USER feature_service WITH ENCRYPTED PASSWORD '<new-immuta-feature-password>'"kubectl scale statefulset --all --replicas <query-engine-previous-replica-count> --selector "app.kubernetes.io/component=query-engine"helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0gateway:
ingress:
hostname: <immuta-fqdn>
annotations:
ingress.gcp.kubernetes.io/pre-shared-cert: <certificate-name>helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0gateway:
ingress:
hostname: <immuta-fqdn>
annotations:
alb.ingress.kubernetes.io/certificate-arn: <certificate-arn>helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0gateway:
ingress:
hostname: <immuta-fqdn>
annotations:
appgw.ingress.kubernetes.io/appgw-ssl-certificate: <certificate-name>helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0gateway:
ingress:
annotations:
traefik.ingress.kubernetes.io/router.tls: "true"
hostname: <immuta-fqdn>
tls: true
# If left unset the TLS secret name defaults to <hostname>-tls
secretName: <secret-name>kubectl create secret tls <secret-name> --cert=path/to/tls.cert --key=path/to/tls.keyhelm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0# query-engine
IMMUTA_FEATURE_PASSWORD=<immuta-feature-password>
PATRONI_SUPERUSER_PASSWORD=<patroni-superuser-password>
PATRONI_REPLICATION_PASSWORD=<patroni-replication-password>
PATRONI_RESTAPI_PASSWORD=<patroni-api-password>kubectl create secret generic immuta-legacy-secret --from-env-file=secret-data.envrm -i secret-data.envlegacy:
enabled: true
queryEngine:
statefulset:
extraEnvVars:
- name: IMMUTA_FEATURE_PASSWORD
valueFrom:
secretKeyRef:
name: immuta-legacy-secret
key: IMMUTA_FEATURE_PASSWORD
- name: PATRONI_SUPERUSER_PASSWORD
valueFrom:
secretKeyRef:
name: immuta-legacy-secret
key: PATRONI_SUPERUSER_PASSWORD
- name: PATRONI_REPLICATION_PASSWORD
valueFrom:
secretKeyRef:
name: immuta-legacy-secret
key: PATRONI_REPLICATION_PASSWORD
- name: PATRONI_RESTAPI_PASSWORD
valueFrom:
secretKeyRef:
name: immuta-legacy-secret
key: PATRONI_RESTAPI_PASSWORD
postgres:
# Query Engine feature user
# Instead use queryEngine.statefulset.extraEnvVars[].name[IMMUTA_FEATURE_PASSWORD]
# password: <immuta-feature-password>
# Query Engine superuser user
# Instead use queryEngine.statefulset.extraEnvVars[].name[PATRONI_SUPERUSER_PASSWORD]
# superuserPassword: <patroni-superuser-password>
# Query Engine replication user
# Instead use queryEngine.statefulset.extraEnvVars[].name[PATRONI_REPLICATION_PASSWORD]
# replicationPassword: <patroni-replication-password>
# Query Engine patroni api user
# Instead use queryEngine.statefulset.extraEnvVars[].name[PATRONI_RESTAPI_PASSWORD]
# patroniApiPassword: <patroni-api-password>
immutaSecurity:
# Each Kubernetes Service has a DNS record associated with it. See: https://kubernetes.io/docs/concepts/services-networking/dns-pod-service/
# The anatomy of a domain name is as followed:
# <service>.<namespace>.svc.<cluster-domain>
#
# Where the default cluster domain is: cluster.local
authEndpoint: "http://immuta-secure.immuta.svc.cluster.local:8823"
secure:
extraEnvVars:
- name: IMMUTA_DATABASES_IMMUTA_CONNECTIONS_FEATURESTOREDB_PASSWORD
valueFrom:
secretKeyRef:
name: immuta-legacy-secret
key: IMMUTA_FEATURE_PASSWORD
extraConfig:
queryEngineRehydration:
enabled: true
disableFeatureStore: false
databases:
immuta:
connections:
featureStoreDb:
# Each Kubernetes Service has a DNS record associated with it. See: https://kubernetes.io/docs/concepts/services-networking/dns-pod-service/
# The anatomy of a domain name is as followed:
# <service>.<namespace>.svc.<cluster-domain>
#
# Where the default cluster domain is: cluster.local
host: "immuta-legacy-query-engine-service.immuta.svc.cluster.local"
port: 5432
ssl: false
# Query Engine feature user
# Instead use secure.extraEnvVars[].name[IMMUTA_DATABASES_IMMUTA_CONNECTIONS_FEATURESTOREDB_PASSWORD]
# password: <immuta-feature-password>helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0{
"id": "query-a20e-493e-id-c1ada0a23a26",
"dateTime": "1639684812845",
"month": 1463,
"profileId": 4,
"userId": "smwilliams@example.com",
"dataSourceId": 1,
"dataSourceName": "Hr Data",
"count": 1,
"recordType": "spark",
"success": true,
"component": "dataSource",
"accessType": "query",
"query": "Relation[id#2644,first_name#2645,last_name#2646,email#2647,gender#2648,race#2649,ssn#2650,dept#2651,job#2652,skills#2653,salary#2654,type#2655] parquet\n",
"extra": {
"databricksWorkspaceID": "0",
"maskedColumns": {},
"metastoreTables": [
"demo.hr_data"
],
"clusterName": "your-cluster-name",
"pathUris": [
"dbfs:/user/hive/warehouse/demo.db/hr_data"
],
"queryText": "select * from demo.hr_data limit 10;",
"queryLanguage": "sql",
"clusterID": "your-171358-cluster-id",
"impersonationUser": "edixon@example.com"
},
"dataSourceTableName": "demo_hr_data",
"createdAt": "2021-12-16T20:00:12.850Z",
"updatedAt": "2021-12-16T20:00:12.850Z"
}while read -r image digest; do
skopeo copy --all --preserve-digests \
"docker://${image%:*}@${digest}" \
"oci-archive:./immuta-2026.2.0/$(basename "${image%:*}")-${image##*:}.tar:${image}" || exit 1
done < ./immuta-2026.2.0/images.txtmkdir ./immuta-2026.2.0
helm pull oci://ocir.immuta.com/stable/immuta-enterprise --destination ./immuta-2026.2.0 --version 2026.2.0tar --extract --gzip --strip-components=1 --directory=./immuta-2026.2.0 --file ./immuta-2026.2.0/immuta-enterprise-2026.2.0.tgz immuta-enterprise/DIGESTS.md
awk -F '|' '/sha256:/ { gsub(/ /, ""); print $2, $3 }' ./immuta-2026.2.0/DIGESTS.md > ./immuta-2026.2.0/images.txtwhile read -r image digest; do
path="${image#*/}"
skopeo copy --all --preserve-digests \
"oci-archive:./immuta-2026.2.0/$(basename "${image%:*}")-${image##*:}.tar" \
"docker://<private-registry-fqdn>/${path}" || exit 1
done < ./immuta-2026.2.0/images.txtwhile read -r image digest; do
path="${image#*/}"
actual=$(skopeo inspect --raw "docker://<private-registry-fqdn>/${path}" | skopeo manifest-digest /dev/stdin)
[ "$actual" = "$digest" ] && echo "OK ${path}" || { echo "FAIL ${path}: ${actual} != ${digest}"; exit 1; }
done < ./immuta-2026.2.0/images.txtglobal:
imageRegistry: <private-registry-fqdn>helm upgrade --install <release-name> ./immuta-2026.2.0/immuta-enterprise-2026.2.0.tgz --values immuta-values.yaml{
"id": "query-a20e-493e-id-c1ada0a23a26",
[...]
"userId": "<immuta_username>",
[...]
"extra": {
[...]
"impersonationUser": "<databricks_username>"
}
[...]
}Opt to check the Enable Impersonation box and customize the Impersonation Role name as needed. This will allow users to natively impersonate another user. Once you finish configuring the integration, you can grant the IMPERSONATE_USER permission to Immuta users. See the Managing users and permissions guide for instructions.
Opt to update the User Profile Delimiters. This will be necessary if any of the provided symbols are used in user profile information.
Entra ID OAuth Client Secret: The values below can be found on the overview page of the application you created in Microsoft Entra ID. Before you enter this information, ensure you have completed the prerequisites for OAuth authentication listed above.
Display Name: This must match the name of the OAuth application you registered.
Tenant Id
Client Id
Client Secret: Enter the Value of the secret, not the secret ID.
Click Save.
Click Save.
Master user on your OpenSearch domain
Create an AWS IAM role that Immuta will assume to send audit events to your OpenSearch domain.
Create an AWS IAM role with credentials using the AWS SDK's default credential provider chain. This method requires a configured IAM role for a service account (IRSA). Contact your Immuta representative to customize your deployment and set up an IAM role for a service account that can give Immuta the credentials to set up the integration.
Create the access policy for this role. It should include at least the permissions provided in the example below, but might need additional permissions depending on other local setup factors. You can find the full list of permissions in the AWS docs on the AWS actions, resources, and condition keys page. Note: If you use this example, replace the content in angle brackets with your region, AWS account ID, and domain.
Name the role and save.
Amazon OpenSearch Service domains are controlled by a resource-based access policy that determines which IAM users or roles can connect to the domain and perform operations.
Follow AWS documentation for updating a resource-based policy. Immuta supports two options for domain access:
Only use fine-grained access control: If you select this option, no additional actions are required this step.
Configure domain access policy:
Edit the access policy to allow the role OpenSearch access and management operations. Grant your AWS IAM es:* through a .
Note: If you use this example, replace the content in angle brackets with your region, AWS account ID, and domain.
Save your changes.
In the OpenSearch console, you must create or edit a role that grants Immuta’s IAM role access to the appropriate cluster and index permissions.
Follow AWS documentation for creating a new OpenSearch role for your audit IAM role.
Grant the following permissions to the new role.
Cluster-level permissions:
cluster:monitor/health
indices:data/write/bulk*
indices:data/write/bulk
indices:monitor/settings/get
indices:data/read/scroll
indices:data/read/scroll/clearIndex-level permissions for * index:
Once the IAM role is created and OpenSearch permissions are updated, allow the role to assume permissions inside OpenSearch.
Follow AWS documentation for updating a backend role in OpenSearch.
Select the OpenSearch role created for Immuta audit access.
Under Backend roles, add the ARN of your IAM role:
arn:aws:iam::<Your AWS Account ID>:role/ImmutaAuditRoleSave your changes.
If Immuta is deployed in an AWS account that is different than OpenSearch, then you must configure a trust relationship between the Immuta role and an OpenSearch role. Follow AWS documentation for creating IAM policies in the Amazon S3 console.
Once configured set SEARCH_AWS_ROLE_ARN with the role for Immuta to assume in the immuta-values.yaml.
After these steps are complete, your audit role should have the required permissions, and you can complete the Immuta install using the IAM role.
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": [
"es:ESHttpDelete",
"es:ESHttpGet",
"es:ESHttpHead",
"es:ESHttpPatch",
"es:ESHttpPost",
"es:ESHttpPut",
"es:DescribeDomains",
"es:ListDomainNames"
],
"Resource": "arn:aws:es:<region>:<Your AWS Account ID>:domain/<your-domain>/*"
}
]
}immuta.spark.acl.assume.not.privileged="true"spark.hadoop.immuta.databricks.config.update.service.enabled="false"Once the script is written, upload the script to a location in dbfs/S3/ABFS to give the Databricks cluster access to it.
Because of how some user properties are populated in Databricks, load the SparkR library in a separate cell before attempting to use any SparkR functions.
To create the R spark-submit job,
Go to the Databricks jobs page.
Create a new job, and select Configure spark-submit.
Set up the parameters:
[
"--conf","spark.driver.extraJavaOptions=-Djava.security.manager=com.immuta.security.ImmutaSecurityManager -Dimmuta.security.manager.classes.config=file:///databricks/immuta/allowedCallingClasses.json -Dimmuta.spark.encryption.fpe.class=com.immuta.spark.encryption.ff1.ImmutaFF1Service",
"--conf","spark.executor.extraJavaOptions=-Djava.security.manager=com.immuta.security.ImmutaSecurityManager -Dimmuta.security.manager.classes.config=file:///databricks/immuta/allowedCallingClasses.json -Dimmuta.spark.encryption.fpe.class=com.immuta.spark.encryption.ff1.ImmutaFF1Service",
"--conf","spark.databricks.repl.allowedLanguages=python,sql,scala,r",
"dbfs:/path/to/script.R",
"arg1", "arg2", "..."
]Note: The path dbfs:/path/to/script.R can be in S3 or ABFS (on Azure Databricks), assuming the cluster is configured with access to that path.
Edit the cluster configuration, and change the Databricks Runtime to be a .
Configure the section as you normally would for an Immuta cluster.
Before you can run spark-submit jobs on Databricks you must initialize the Spark session with the settings outlined below.
Configure the Spark session with immuta.spark.acl.assume.not.privileged="true" and spark.hadoop.immuta.databricks.config.update.service.enabled="false".
Note: Stop your Spark session (spark.stop()) at the end of your job or the cluster will not terminate.
The spark submit job needs to be launched using a different classloader which will point at the designated user JARs directory. The following Scala template can be used to handle launching your submit code using a separate classloader:
package com.example.job
import java.net.URLClassLoader
import java.io.File
import org.apache.spark.sql.SparkSession
object ImmutaSparkSubmitExample {
def main(args: Array[String]): Unit = {
val jarDir = new File("/databricks/immuta/jars/")
val urls = jarDir.listFiles.map(_.toURI.toURL)
// Configure a new ClassLoader which will load jars from the additional jars directory
val cl = new URLClassLoader(urls)
val jobClass = cl.loadClass(classOf[ImmutaSparkSubmitExample].getName)
val job = jobClass.newInstance
jobClass.getMethod("runJob").invoke(job)
}
}
class ImmutaSparkSubmitExample {
def getSparkSession(): SparkSession = {
SparkSession.builder()
.appName("Example Spark Submit")
.enableHiveSupport()
.config("immuta.spark.acl.assume.not.privileged", "true")
.config("spark.hadoop.immuta.databricks.config.update.service.enabled", "false")
.getOrCreate()
}
def runJob(): Unit = {
val spark = getSparkSession
try {
val df = spark.table("immuta.<YOUR DATASOURCE>")
// Run Immuta Spark queries...
} finally {
spark.stop()
}
}
}To create the Scala spark-submit job,
Build and upload your JAR to dbfs/S3/ABFS where the cluster has access to it.
Select Configure spark-submit, and configure the parameters:
[
"--conf","spark.driver.extraJavaOptions=-Djava.security.manager=com.immuta.security.ImmutaSecurityManager -Dimmuta.security.manager.classes.config=file:///databricks/immuta/allowedCallingClasses.json -Dimmuta.spark.encryption.fpe.class=com.immuta.spark.encryption.ff1.ImmutaFF1Service",
"--conf","spark.executor.extraJavaOptions=-Djava.security.manager=com.immuta.security.ImmutaSecurityManager -Dimmuta.security.manager.classes.config=file:///databricks/immuta/allowedCallingClasses.json -Dimmuta.spark.encryption.fpe.class=com.immuta.spark.encryption.ff1.ImmutaFF1Service",
"--conf","spark.databricks.repl.allowedLanguages=python,sql,scala,r",
"--class","org.youorg.package.MainClass",
"dbfs:/path/to/code.jar",
"arg1", "arg2", "..."
]Note: The fully-qualified class name of the class whose main function will be used as the entry point for your code in the --class parameter.
Note: The path dbfs:/path/to/code.jar can be in S3 or ABFS (on Azure Databricks) assuming the cluster is configured with access to that path.
Edit the cluster configuration, and change the Databricks Runtime to a .
Include IMMUTA_INIT_ADDITIONAL_JARS_URI=dbfs:/path/to/code.jar in the "Environment Variables" (where dbfs:/path/to/code.jar is the path to your jar) so that the jar is uploaded to all the cluster nodes.
The user mapping works differently from notebooks because spark-submit clusters are not configured with access to the Databricks SCIM API. The cluster tags are read to get the cluster creator and match that user to an Immuta user.
Privileged users (Databricks admins and allowlisted users) must be tied to an Immuta user and given access through Immuta to access data through spark-submit jobs because the setting immuta.spark.acl.assume.not.privileged="true" is used.
There is an option of using the immuta.api.key setting with an Immuta API key generated on the Immuta profile page.
Currently when an API key is generated it invalidates the previous key. This can cause issues if a user is using multiple clusters in parallel, since each cluster will generate a new API key for that Immuta user. To avoid these issues, manually generate the API key in Immuta and set the immuta.api.key on all the clusters or use a specified job user for the submit job.
A Redshift cluster with an AWS row-level security patch applied. Contact Immuta for guidance.
The enable_case_sensitive_identifier parameter must be set to false (default setting) for your Redshift cluster.
The Redshift role used to run the Immuta bootstrap script must have the following privileges when configuring the integration to
Use an existing database:
ALL PRIVILEGES ON DATABASE for the database you configure the integration with, as you must manage grants on that database.
CREATE USER
GRANT TEMP ON DATABASE
Create a new database:
CREATE DATABASE
CREATE USER
GRANT TEMP ON DATABASE
Click the App Settings icon in the navigation menu.
Click the Integrations tab.
Click the +Add Integration button and select Redshift from the dropdown menu.
Complete the Host and Port fields.
Enter the name of the database you created the external schema in as the Immuta Database. This database will store all secure schemas and Immuta-created views.
Opt to check the Enable Impersonation box and customize the Impersonation Role name as needed. This will allow users to natively impersonate another user. Once you finish configuring the integration, you can grant the IMPERSONATE_USER permission to Immuta users. See the for instructions.
Select Manual and download both of the bootstrap scripts from the Setup section. The specified role used to run the bootstrap needs to have the following privileges:
ALL PRIVILEGES ON DATABASE for the database you configure the integration with, as you must manage grants on that database.
CREATE USER
Run the bootstrap script (Immuta database) in the Redshift database that contains the external schema.
Choose your authentication method, and enter the credentials from the bootstrap script for the Immuta_System_Account.
Click Save.
Click the App Settings icon in the navigation menu.
Click the Integrations tab.
Click the +Add Integration button and select Redshift from the dropdown menu.
Complete the Host and Port fields.
Enter an Immuta Database. This is a new database where all secure schemas and Immuta created views will be stored.
Opt to check the Enable Impersonation box and customize the Impersonation Role name as needed. This will allow users to natively impersonate another user. Once you finish configuring the integration, you can grant the IMPERSONATE_USER permission to Immuta users. See the for instructions.
Select Manual and download both of the bootstrap scripts from the Setup section. The specified role used to run the bootstrap needs to have the following privileges:
ALL PRIVILEGES ON DATABASE for the database you configure the integration with, as you must manage grants on that database.
CREATE DATABASE
Run the bootstrap script (initial database) in the Redshift initial database.
Run the bootstrap script (Immuta database) in the new Immuta Database in Redshift.
Choose your authentication method, and enter the credentials from the bootstrap script for the Immuta_System_Account.
Click Save.
Then, add your external tables to the Immuta database.
ALL PRIVILEGES ON DATABASE IMMUTA_DBALL PRIVILEGES ON ALL SCHEMAS IN DATABASE IMMUTA_DB
USAGE ON FUTURE PROCEDURES IN SCHEMA IMMUTA_DB.IMMUTA_PROCEDURES
USAGE ON LANGUAGE PLPYTHONU
Additionally the PUBLIC role will be granted the following privileges:
USAGE ON DATABASE IMMUTA_DB
TEMP ON DATABASE IMMUTA_DB
USAGE ON SCHEMA IMMUTA_DB.IMMUTA_PROCEDURES
USAGE ON SCHEMA IMMUTA_DB.IMMUTA_FUNCTIONS
USAGE ON FUTURE FUNCTIONS IN SCHEMA IMMUTA_DB.IMMUTA_FUNCTIONS
USAGE ON SCHEMA IMMUTA_DB.IMMUTA_SYSTEM
SELECT ON TABLES TO public
Immuta supports the Redshift integration as both multi-database and single-database integrations. In either integration type, Immuta supports a single integration with secure views in a single database per cluster.
If using a multi-database integration, you must use a Redshift cluster with an RA3 node because Immuta requires cross-database views.
If using a single-database integration, all Redshift cluster types are supported. However, because cross-database queries are not supported in any types other than RA3, Immuta's views must exist in the same database as the raw tables. Consequently, the steps for configuring the integration for Redshift clusters with external tables differ slightly from those that don't have external tables. Allow Immuta to create secure views of your external tables through one of these methods:
configure the integration with an existing database that contains the external tables: Instead of creating an immuta database that manages all schemas and views created when Redshift data is registered in Immuta, the integration adds the Immuta-managed schemas and views to an existing database in Redshift.
configure the integration by creating a new immuta database and re-create all of your external tables in that database.
SQL statements are used to create all views, including a join to the secure view: immuta_system.user_profile. This secure view is a select from the immuta_system.profile table (which contains all Immuta users and their current groups, attributes, projects, and a list of valid tables they have access to) with a constraint immuta__userid = current_user() to ensure it only contains the profile row for the current user. The immuta_system.user_profile view is readable by all users, but will only display the data that corresponds to the user executing the query.
The Redshift integration uses webhooks to keep views up-to-date with Immuta data sources. When a data source or policy is created, updated, or disabled, a webhook will be called that will create, modify, or delete the dynamic view. The immuta_system.profile table is updated through webhooks when a user's groups or attributes change, they switch projects, they acknowledge a purpose, or when their data source access is approved or revoked. The profile table can only be read and updated by the Immuta system account.
The status of the integration is visible on the integrations tab of the Immuta application settings page. If errors occur in the integration, a banner will appear in the Immuta UI with guidance for remediating the error.
The definitions for each status and the state of configured data platform integrations is available in the response schema of the integrations API. However, the UI consolidates these error statuses and provides detail in the error messages.
An Immuta Application Administrator configures the Redshift integration and registers Redshift warehouse and databases with Immuta.
Immuta creates a database inside the configured Redshift ecosystem that contains Immuta policy definitions and user entitlements.
A Data Owner registers Redshift tables in Immuta as data sources.
A Data Owner, Data Governor, or Administrator creates or changes a policy or user in Immuta.
Data source metadata, tags, user metadata, and policy definitions are stored in Immuta's Metadata Database.
The Immuta Web Service calls a stored procedure that modifies the user entitlements or policies.
A Redshift user who is subscribed to the data source in Immuta directly in Redshift through the immuta database and sees policy-enforced data.
Redshift Spectrum (Redshift external tables) allows Redshift users to query external data directly from files on Amazon S3. Because cross-database queries are not supported in Redshift Spectrum, Immuta's views must exist in the same database as the raw tables. Consequently, the steps for configuring the integration for Redshift clusters with external tables differ slightly from those that don't have external tables. Allow Immuta to create secure views of your external tables through one of these methods:
configure the integration with an existing database that contains the external tables: Instead of creating an immuta database that manages all schemas and views created when Redshift data is registered in Immuta, the integration adds the Immuta-managed schemas and views to an existing database in Redshift
configure the integration by creating a new immuta database and re-create all of your external tables in that database.
Once the integration is configured, Data Owners must register Redshift Spectrum data sources using the Immuta CLI or V2 API.
<username> is your Immuta username.) If the current active primary role is used to query tables, USAGE on a Snowflake warehouse must be granted to the Immuta-managed Snowflake role for each user.Set your Snowflake to use secondary roles (USE SECONDARY ROLES ALL), which allows users to use the privileges from all roles that they have been granted, including <prefix>_USER_<username>, in addition to the current active primary role. Users may also set a value for DEFAULT_SECONDARY_ROLES as an object property on a Snowflake user. To learn more about primary roles and secondary roles in Snowflake, see Snowflake documentation.
Impersonation allows Immuta users or system accounts to query data sources they are subscribed to as another Immuta user.Consider the following users and their data source subscriptions.User 1 data source subscriptions
HR data source
Research data source
User 2 data source subscriptions
HR data source
Consumer report data source
The table below illustrates what data is returned when User 1, User 2, and User 2 impersonating User 1 query these data sources.
User 1
name column is masked
ssn column is masked with hashing
❌ Denied access
Users with the APPLICATION_ADMIN Immuta permission can enable impersonation when registering a Snowflake connection for the first time or edit an existing connection to enable impersonation.
Snowflake query audit will show the user running the queries as the user logged in to Snowflake, not as the user they are impersonating.

config.properties fileAn Immuta application administrator who can register the connection
For the recommended implementation described on this page, you should also have:
An enterprise identity provider
Identified owners or stewards for your major data domains
An understanding of the metadata maintained in your external catalog, if you use one
An application administrator will register the Starburst (Trino) connection to allow Immuta to discover databases, schemas, and tables in Starburst (Trino). As object sync runs, Immuta creates corresponding data sources that can be governed through policies.
A Starburst (Trino) admin will install the Immuta plugin and update the Starburst (Trino) config.properties file to allow Immuta to apply policies to Starburst (Trino) securables.
After registering the connection, organize your data into domains. Domains assign ownership of data to the appropriate teams and determine who can manage policies, identification, and audit for those data sources.
Once your are registered in Immuta and organized into domains, you can apply policy to them.
and configure SSO so that users can authenticate with their existing credentials and be automatically registered in Immuta.
If your identity provider supports SCIM, . These attributes can then be used when authoring policies so access automatically changes as the user information in the IAM is synced with Immuta.
After your identity provider is configured,
Metadata allows you to author policies that automatically apply across your Starburst (Trino) environment instead of managing individual tables and columns.
If your organization already maintains metadata in an external catalog, so Immuta continuously synchronizes tags, classifications, and descriptions.
You can also . Identification is recommended for all deployments and is especially useful if you do not maintain an external catalog.
Once your data sources are tagged in Immuta, you can author global policies based on those tags. These policies can apply automatically as additional data sources are registered through object sync and tagged.
Once users and metadata are available, begin authoring global policies that automatically protect your data.
to automatically grant access to users who meet the required conditions. You can also use subscription policies to enforce organization-wide requirements, such as limiting access to users with specific attributes or training before access can be granted.
to mask sensitive columns or filter rows based on metadata such as catalog or identification tags.
Author global policies using metadata and user attributes instead of individual Starburst (Trino) objects or users. This allows the same policies to automatically apply as new data is registered and users are synchronized into Immuta.
After your data, users, and policies are configured, .
Audit records provide visibility into user queries, policy evaluations, access requests, policy changes, and metadata updates, allowing your organization to monitor how data is accessed and governed across your Starburst (Trino) environment.
After completing this workflow, your Starburst (Trino) environment is ready for automated governance. From here you can continue configuring advanced features, refining policies, and onboarding additional Starburst (Trino) data sources. See the Starburst (Trino) integration reference guide for architecture details, platform behavior, and additional configuration options.
This guide highlights best practices when deploying Immuta in a production environment.
Provisioning an appropriately resourced PostgreSQL database for Immuta is critical to application performance. The recommendations below are based on the number of data sources registered multiplied (*) by the number of users on the deployment:
Small (data sources * users <100k)
This recommendation assumes approximately 1 million events per day with a 90-day data retention policy:
2 nodes
2 CPUs/node
4GB RAM/node
Storage 100GB SSD/node
Back up or source control your immuta-values.yaml Helm values file.
Assign to pods.
Edit immuta-values.yaml to include the following recommended resource requests and limits for most Immuta deployments.
Use in the immuta-values.yaml file instead of passwords and tokens. The following section demonstrates how to create a secret and reference it in the Helm values file. For guidance on updating these credentials based on your specific security policies, .
Create a file named secret-data.env with the following content.
Create secret named immuta-secret from file secret-data.env.
Delete file secret-data.env, as it's no longer needed.
Edit immuta-values.yaml to include the following Helm values.
Remove any sensitive key-value pairs from the immuta-values.yaml Helm values that were made redundant after the secret was created.
Perform a to apply the changes made to immuta-values.yaml.
This page describes the Redshift integration, configuration options, and features. For a tutorial to enable this integration, see the installation guide.
❌
For automated installations, the credentials provided must be a Superuser or have the ability to create databases and users and modify grants.
Redshift datashares
Redshift Serverless
For configuration and data source registration instructions, see the .
The Redshift integration supports the following authentication methods to configure the integration and create data sources:
Username and Password: Users can authenticate with their Redshift username and password.
AWS Access Key: Users can authenticate with an .
Immuta cannot ingest tags from Redshift, but you can connect any of these to work with your integration.
Impersonation allows users to query data as another Immuta user in Redshift. To enable user impersonation, see the .
Users can enable multiple with a single Immuta tenant.
The host of the data source must match the host of the connection for the view to be created.
When using multiple Redshift integrations, a user has to have the same user account across all hosts.
Case sensitivity of database, table, and column identifiers is not supported. The must be set to false (default setting) for your Redshift cluster to configure the integration and register data sources.
For most policy types in Redshift, Immuta uses SQL clauses to implement enforcement logic; however Immuta uses Python UDFs in the Redshift integration to implement the following masking policies:
Masking using a regular expression
Reversible masking
Format-preserving masking
Randomized response
The number of Python UDFs that can run concurrently per Redshift cluster is limited to one-fourth of the total concurrency level for the cluster. For example, if the Redshift cluster is configured with a concurrency of 15, a maximum of three Python UDFs can run concurrently. After the limit is reached, Python UDFs are queued for execution within workload management queues.
The SVL_QUERY_QUEUE_INFO view in Redshift, which is visible to a Redshift superuser, summarizes details for queries that spent time in a workload management (WLM) query queue. Queries must be completed in order to appear as results in the SVL_QUERY_QUEUE_INFO view.
If you find that queries on Immuta-built views are spending time in the workload management (WLM) query queue, you should either edit your Redshift cluster configuration to increase concurrency, or use fewer of the masking policies which leverage Python UDFs. For more information on increasing concurrency, see the Redshift docs on implementing .
Learn how Immuta enforces policies on data in your Snowflake environment
In the Snowflake integration, Immuta administers Snowflake privileges on data registered in Immuta. Then, Immuta users who have been granted access to the data sources can query them.
The sequence diagram below outlines the events that occur when an Immuta user who is subscribed to a data source queries it in Snowflake.
The Snowflake integration is configured and data is registered through connections, an Immuta feature that allows administrators to register data objects in a technology through a single connection to make data registration more scalable for your organization.
Once the Snowflake connection is registered, you can author subscription and data policies in Immuta to enforce access controls.
See the Snowflake integration reference guide for more details about registering a connection.
When a subscription policy is applied to a data source, users who meet the conditions of the policy will be automatically subscribed to the data source. Immuta creates roles for those users (if an Immuta-generated role for them does not already exist) and grants Snowflake privileges to that role.Consider the following example that illustrates how Immuta enforces a subscription policy that only allows users in the analysts group to access the yellow-table. When this policy is authored and applied to the data source, Immuta issues a SQL statement in Snowflake that grants the SELECT privilege on yellow-table to Immuta-created roles of users registered in Immuta that are part of the analysts group.
In the image above, the user in the analysts group accesses yellow-table, while the user who is a part of the research group is denied access.
After Snowflake objects are registered in Immuta, you can author data policies in Immuta to enforce fine-grained access controls.
When a data policy is applied to a Snowflake data source, Immuta enforces that policy natively in Snowflake. Depending on the policy type, Immuta manages Snowflake and on the registered object so that queries return policy-enforced results.
As data policies are created, updated, or removed in Immuta, Immuta updates the corresponding Snowflake policy objects and attachments to keep enforcement in sync. Users continue querying the Snowflake object directly and see policy-enforced data in Snowflake.
See the for guidance on authoring data policies in Immuta and the for the Snowflake integration.
When a user applies a masking policy to a Snowflake data source, Immuta truncates masked values to align with Snowflake column length ( types) and precision ( types) requirements.
Consider these columns in a data source that have the following masking policies applied.
Column A (VARCHAR(6)): Mask using hashing for everyone
Column B (VARCHAR(5)): Mask using a constant REDACTED for everyone
Column C (VARCHAR(6)): Mask by making null for everyone
Column D (NUMBER(3, 0)): Mask by rounding to the nearest 10 for everyone
Querying this data source in Snowflake would return the following values:
For more details about Snowflake column length and precision requirements, see the documentation.
When a policy is applied to a column, Immuta uses to cache the result of the called function. Then, when a user queries a column that has that policy applied to it, Immuta uses that cached result to dramatically improve query performance.
Customize how read and write access policies will be enforced when authored
Starburst (Trino) version 438 or newer
Write policies for Starburst (Trino) enabled. Contact your Immuta representative to get this feature enabled on your account.
In its default setting, the Starburst (Trino) integration's write access value controls the authorization of SQL operations that perform data modification (such as INSERT, UPDATE, DELETE, MERGE, and TRUNCATE). However, administrators can allow table modification operations (such as ALTER and DROP tables) to be authorized as write operations. Two locations allow administrators to specify how are applied to data in Starburst (Trino). Select one or both of the options below to customize these settings. If the access-control.properties file is used, it may override the policies configured in the Immuta web service.
: Configure write policies in the Immuta web service to allow all Starburst (Trino) clusters targeting that Immuta tenant to receive the same write policy configuration for data sources. This configuration will only affect tables or views registered as Immuta data sources.
: Configure write policies using the in Starburst or Trino to broadly customize access for Immuta users on a specific cluster. This configuration file takes precedence over write policies passed from the Immuta web service. Use this option if all Immuta users should have the same level of access to tables regardless of the write policy setting in the Immuta web service.
Contact your Immuta representative to configure read and write access in the Immuta web service if all Starburst (Trino) data source operations should be affected identically across Starburst (Trino) clusters connected to your Immuta tenant. A configuration example is provided below.
The following example maps WRITE to READ, WRITE and OWN permissions and READ to just READ. Both READ and WRITE permissions should always include READ:
Given the above configuration, when a user gets write access to a Starburst (Trino) data source, they will have both data and table modification permissions on that data source. See the for details about these operations.
Configure the integration to allow read and write policies to apply to any data source (registered or unregistered in Immuta) on a Starburst cluster.
Create the Immuta access control configuration file in the Starburst configuration directory (/etc/starburst/immuta-access-control.properties for Docker installations or <starburst_install_directory>/etc/immuta-access-control.properties for standalone installations).
Modify one or both properties below to customize the behavior of read or write access policies for all users:
Create the Immuta access control configuration file in the Trino configuration directory (/etc/trino/config.properties for Docker installations or <trino_install_directory>/etc/config.properties for standalone installations).
Modify one or both properties below to customize the behavior of read or write access policies for all users:
Learn about how you can register data from Snowflake and govern access to that data
This page describes the recommended workflow for setting up Immuta with Snowflake. Following these steps connects your Snowflake environment, registers users, ingests metadata, and enables automated governance through global policies and access requests.
To complete this workflow, ensure you have:
Access to a Snowflake account and the permissions required to configure the connection
An Immuta application administrator who can register the connection
For the recommended implementation described on this page, you should also have:
An enterprise identity provider
Identified owners or stewards for your major data domains
An understanding of the metadata maintained in your external catalog, if you use one
An application administrator will to allow Immuta to discover databases, schemas, and tables in Snowflake. As object sync runs, Immuta creates corresponding data sources that can be governed through policies.
After registering the connection, . Domains assign ownership of data to the appropriate teams and determine who can manage policies, identification, and audit for those data sources.
Once your are registered in Immuta and organized into domains, you can apply policy to them.
After completing this workflow, your Snowflake environment is ready for automated governance. From here you can continue configuring advanced features, refining policies, and onboarding additional Snowflake data sources. See the for architecture details, platform behavior, and additional configuration options.
Immuta comprises three core services: Secure, Discover, and Detect. These services rely on PostgreSQL and Elasticsearch to store their states, a caching layer, and Temporal for job execution. The illustration below shows the relationships among these services.
The Immuta Enterprise Helm chart (IEHC) does not include the deployment of PostgreSQL or Elasticsearch, so you must deploy them separately.
Although Immuta recommends using Elasticsearch because it supports all audit, you can deploy Immuta without Elasticsearch. The table below outlines the Immuta features supported with and without Elasticsearch and the dependencies you must deploy and manage yourself.
List the upgrade jobs and find the one that failed.
Read the job's log.
Use the to determine remediation steps.
Learn how Immuta enforces policies on data in your Databricks Spark environment
In the Databricks Spark integration, Immuta installs an Immuta-maintained Spark plugin on your Databricks cluster. When a user queries data that has been registered in Immuta as a data source, the plugin injects policy logic into the plan Spark builds so that the results returned to the user only include data that specific user should see.
The sequence diagram below breaks down this process of events when an Immuta user queries data in Databricks.
When data owners register Databricks securables in Immuta, the securable metadata is registered and Immuta creates a corresponding data source for those securables. The data source metadata is stored in the Immuta Metadata Database so that it can be referenced in policy definitions.
The image below illustrates what happens when a data owner registers the Accounts, Claims, and
This page illustrates how to configure the on the Immuta app settings page. To configure this integration via the Immuta API, see the .
For instructions on configuring Redshift Spectrum, see the guide.
A Redshift cluster with an RA3 node is required for the multi-database integration. You must use a Redshift RA3 instance type because Immuta requires cross-database views, which are only supported in Redshift RA3 instance types. For other instance types, you may configure a single-database integration using one of the .
For automated installations, the credentials provided must be a Superuser or have the ability to create databases and users and modify grants.
User 2
All data visible
❌ Denied access
address column is masked
User 2 impersonating User 1
name column is masked
❌ Denied access
address column is masked
REVOKE ALL PRIVILEGES ON DATABASE
GRANT TEMP ON DATABASE
CREATE USER
GRANT TEMP ON DATABASE
❌
✅
❌
✅
Connect your organization's identity provider and configure SSO so that users can authenticate with their existing credentials and be automatically registered in Immuta.
If your identity provider supports SCIM, enable provisioning to synchronize users, groups, and attributes. These attributes can then be used when authoring policies so access automatically changes as the user information in the IAM is synced with Immuta.
After your identity provider is configured, map Snowflake user identities to Immuta users. This ensures that policies written in Immuta are enforced for the correct users when they query data in Snowflake.
Once your users are registered and mapped to their Snowflake identities, any policies that apply to data sources will be enforced for those users.
Metadata allows you to author policies that automatically apply across your Snowflake environment instead of managing individual tables and columns.
If your organization already maintains metadata in an external catalog, connect your external catalog so Immuta continuously synchronizes tags, classifications, and descriptions.
You can also enable identification to automatically discover and tag sensitive data. Identification is recommended for all deployments and is especially useful if you do not maintain an external catalog.
Once your data sources are tagged in Immuta, you can author global policies based on those tags. These policies can apply automatically as additional data sources are registered through object sync and tagged.
Once users and metadata are available, begin authoring global policies that automatically protect your data.
Create subscription policies to automatically grant access to users who meet the required conditions. You can also use subscription policies to enforce organization-wide requirements, such as limiting access to users with specific attributes or training before access can be granted.
Create data policies to mask sensitive columns or filter rows based on metadata such as catalog or identification tags.
Author global policies using metadata and user attributes instead of individual Snowflake objects or users. This allows the same policies to automatically apply as new data is registered and users are synchronized into Immuta.
After your data, users, and policies are configured, configure audit to export governance activity.
Audit records provide visibility into user queries, policy evaluations, access requests, policy changes, and metadata updates, allowing your organization to monitor how data is accessed and governed across your Snowflake environment.
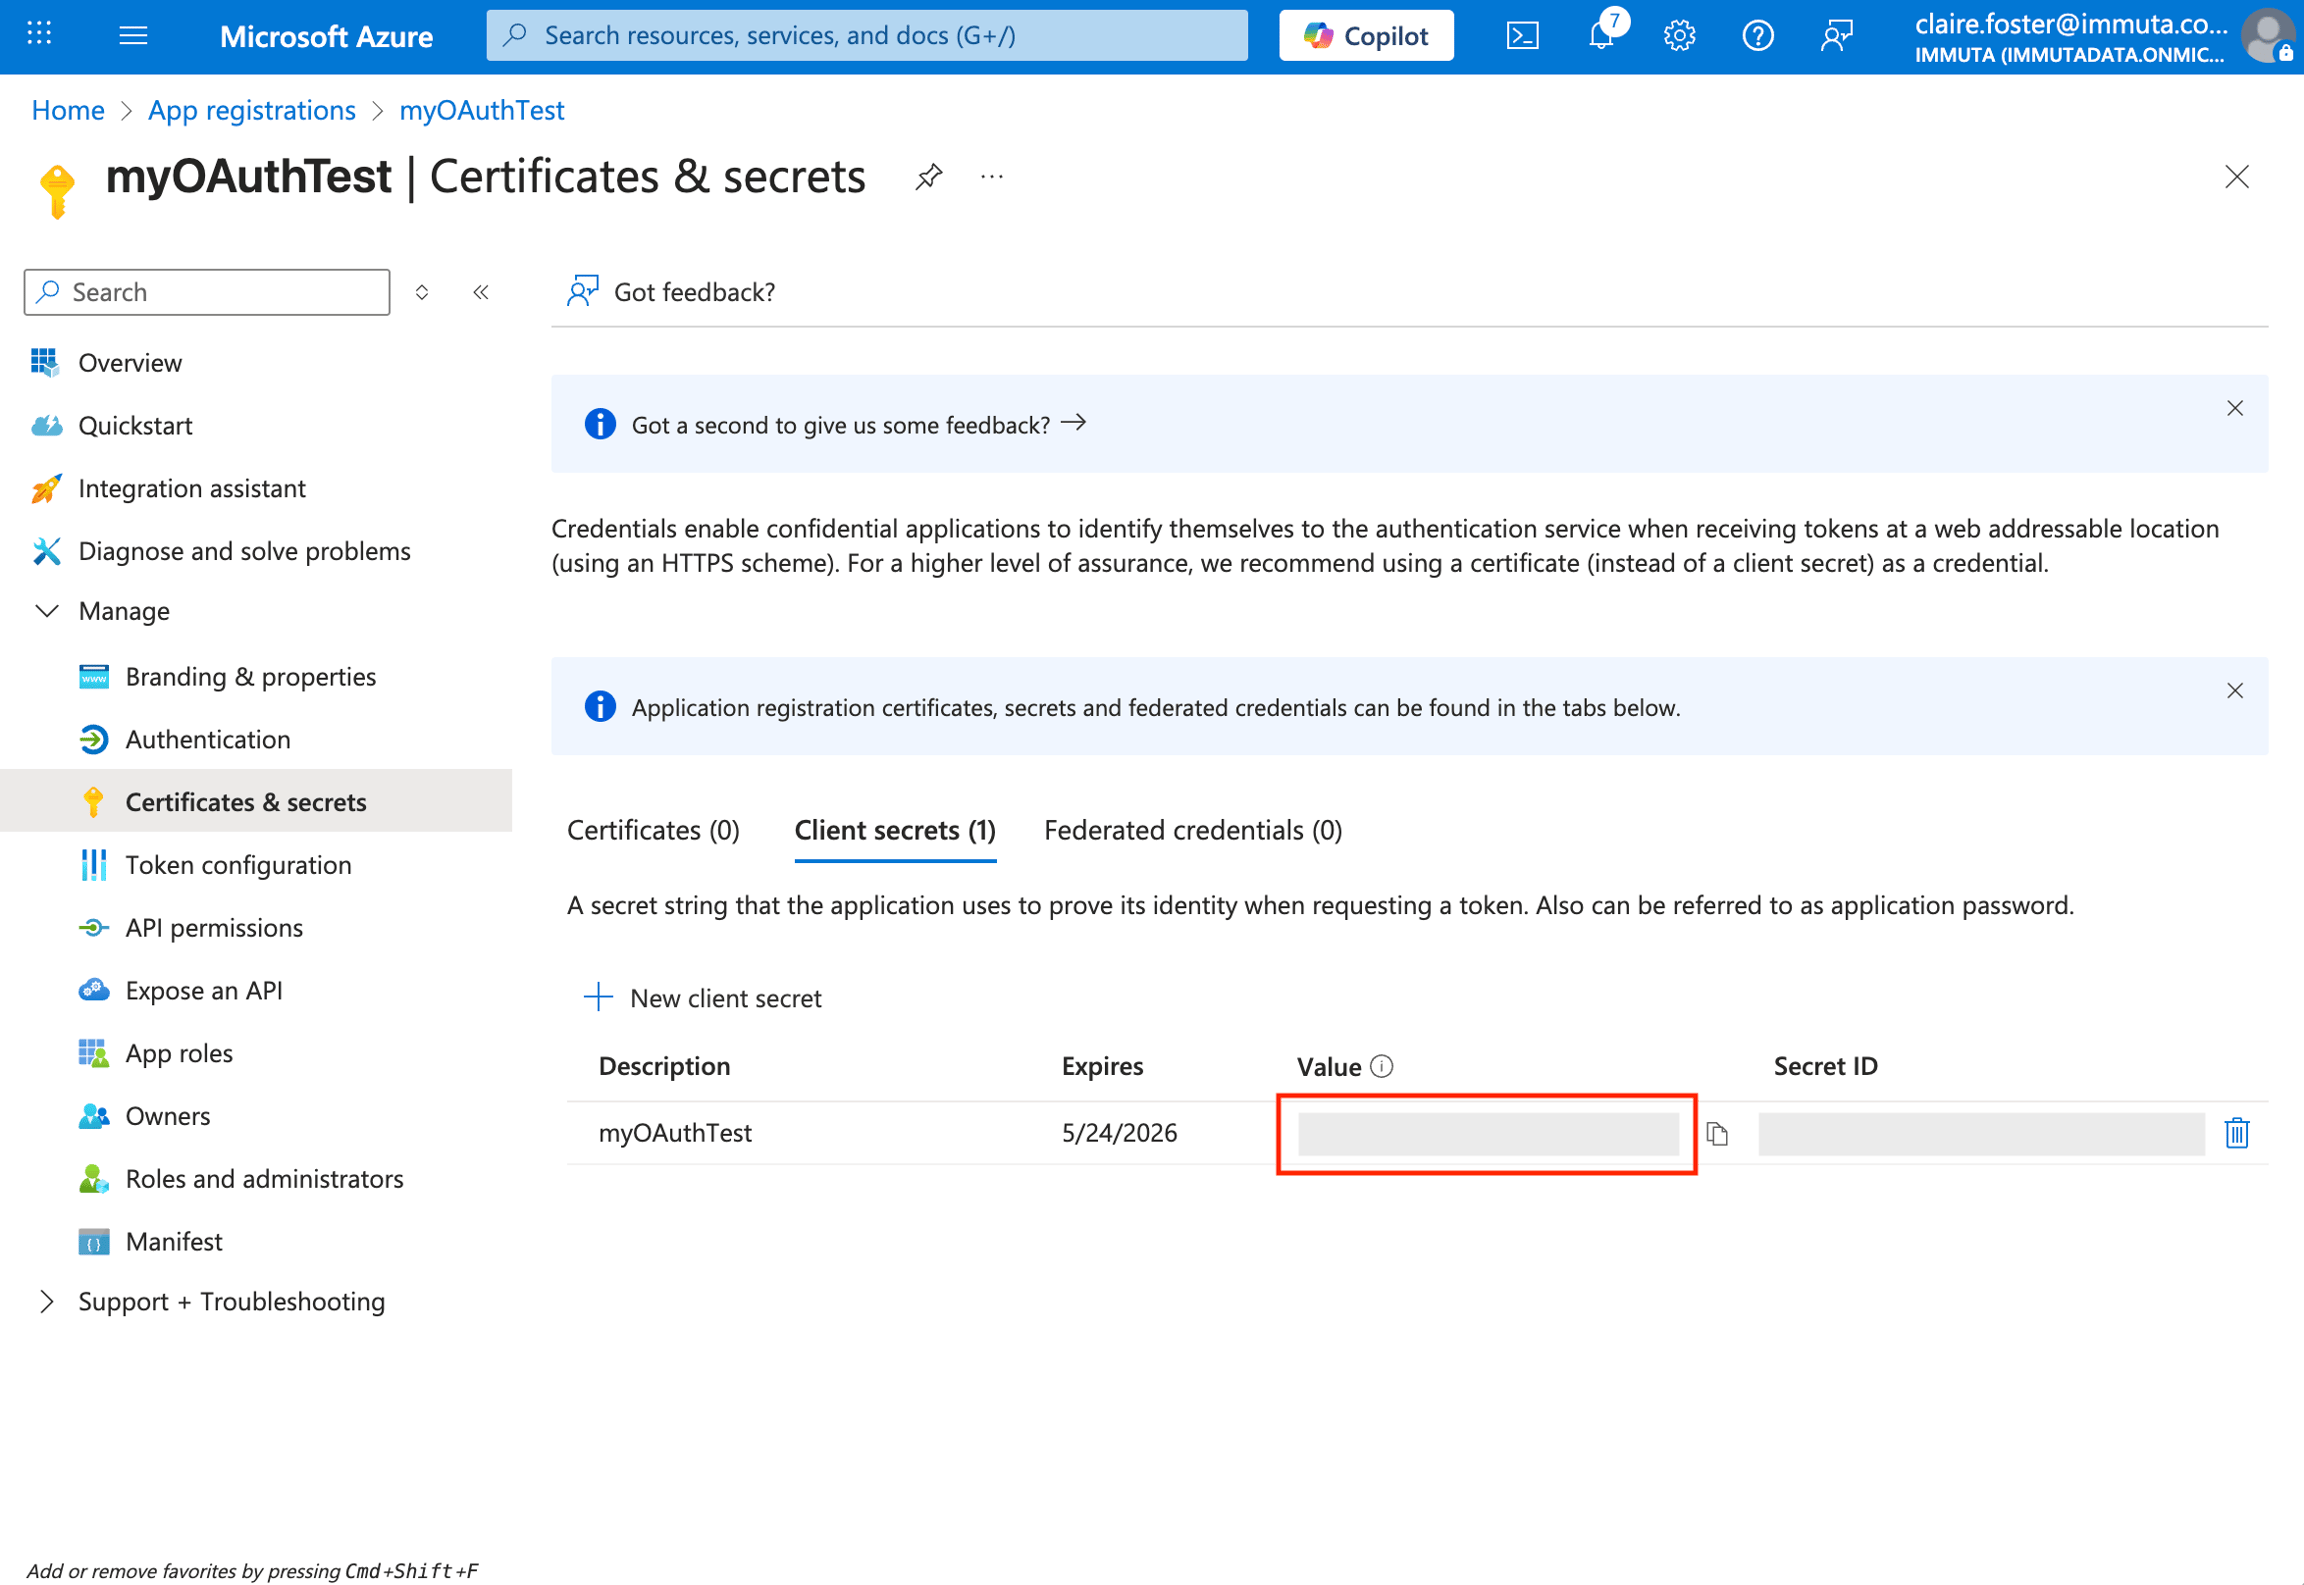
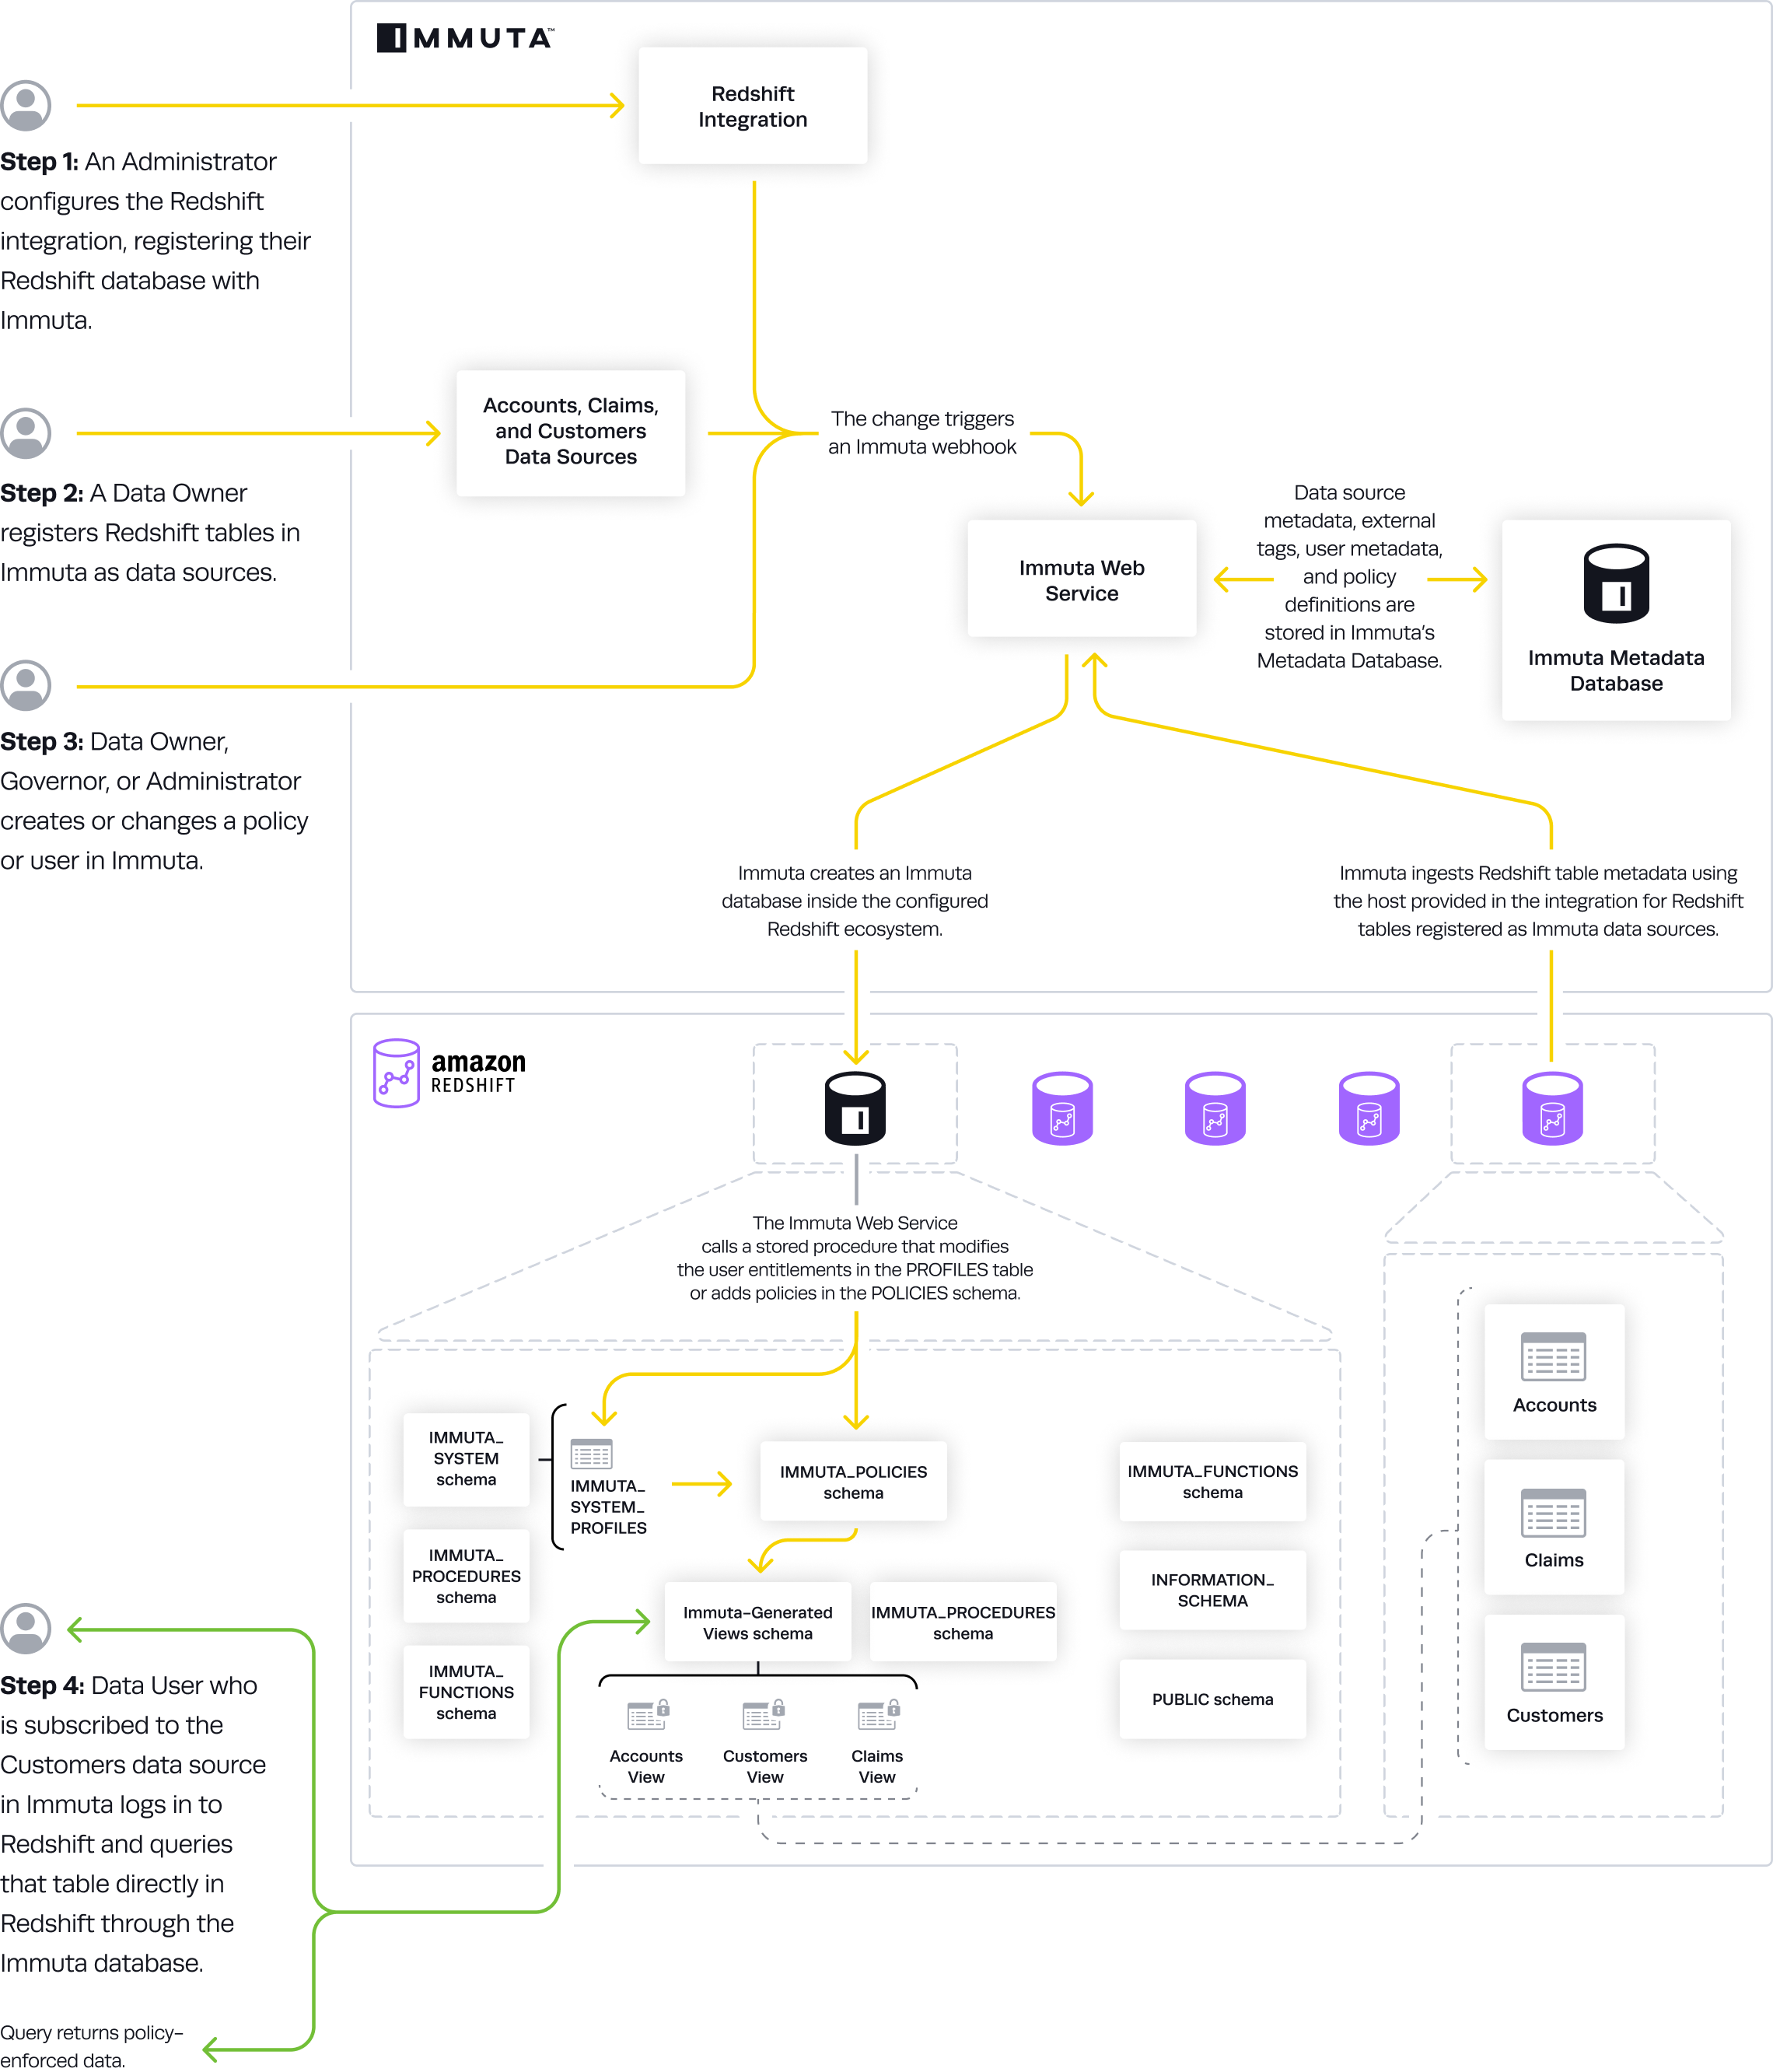
null
750
9s7934
REDAC
null
380
5w4502
REDAC
null
990
6e3611

REDAC
Once your users are registered and mapped to their Starburst (Trino) identities, any policies that apply to data sources will be enforced for those users.
2
8GB
100 GB SSD
Normal
4
16GB
100 GB SSD
Large (data sources * users >1M)
8
32GB
100 GB SSD
immuta.user.adminREAD: Grants SELECT on tables or views; grants SHOW on tables, views, or columns
WRITE: Grants INSERT, UPDATE, DELETE, MERGE, or TRUNCATE on tables; grants REFRESH on materialized views.
OWN: Grants ALTER and DROP on tables; grants SET on comments and properties
immuta.allowed.non.immuta.datasource.operations: This property governs objects (catalogs, schemas, tables, etc.) that are not registered as data sources in Immuta. Use all or a combination of the following access values:
READ: Grants SELECT on tables or views; grants SHOW on tables, views, or columns
WRITE: Grants INSERT, UPDATE, DELETE, MERGE, or TRUNCATE on tables; grants REFRESH on materialized views.
OWN: Grants ALTER and DROP on tables; grants SET on comments and properties
CREATE: Grants CREATE on catalogs, schema, tables, and views. This is the only property that can allow CREATE permissions, since CREATE is enforced on new objects that do not exist in Starburst or Immuta yet (such as a new table being created with CREATE TABLE).
For example, the following configuration allows READ, WRITE, and OWN operations to be authorized on data sources registered in Immuta and all operations are permitted on data that is not registered in Immuta:
Enable the Immuta access control plugin in the Starburst cluster's configuration file (/etc/starburst/config.properties for Docker installations or <starburst_install_directory>/etc/config.properties for standalone installations). For example,
immuta.user.adminREAD: Grants SELECT on tables or views; grants SHOW on tables, views, or columns
WRITE: Grants INSERT, UPDATE, DELETE, MERGE, or TRUNCATE on tables; grants REFRESH on materialized views.
OWN: Grants ALTER and DROP on tables; grants SET on comments and properties
immuta.allowed.non.immuta.datasource.operations: This property governs objects (catalogs, schemas, tables, etc.) that are not registered as data sources in Immuta. Use all or a combination of the following access values:
READ: Grants SELECT on tables or views; grants SHOW on tables, views, or columns
WRITE: Grants INSERT, UPDATE, DELETE, MERGE, or TRUNCATE on tables; grants REFRESH on materialized views.
OWN: Grants ALTER and DROP on tables; grants SET on comments and properties
CREATE: Grants CREATE on catalogs, schema, tables, and views. This is the only property that can allow CREATE permissions, since CREATE is enforced on new objects that do not exist in Starburst or Immuta yet (such as a new table being created with CREATE TABLE).
For example, the following configuration allows READ, WRITE, and OWN operations to be authorized on data sources registered in Immuta and all operations are permitted on data that is not registered in Immuta:
Enable the Immuta access control plugin in Trino's configuration file (/etc/trino/config.properties for Docker installations or <trino_install_directory>/etc/config.properties for standalone installations). For example,
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"AWS": "arn:aws:iam::<Your AWS Account ID>:role/ImmutaAuditRole"
},
"Action": "es:*",
"Resource": "arn:aws:es:<region>:<Your AWS Account ID>:domain/<your-domain>/*"
}
]
}indices:admin/aliases
indices:admin/aliases*
indices:data/read/search
indices:admin/exists
indices:admin/create
indices:admin/delete
indices:admin/settings/update
indices:admin/get
indices:data/write/delete/byquery
indices:data/write/index
indices:admin/mapping/put
indices:data/write/bulk
indices:data/write/bulk*
indices:data/write/update/byquery
indices:monitor/settings/get
indices:data/write/delete
indices:data/read/scroll
indices:data/read/scroll/clear
indices:admin/refresh
indices:admin/refresh*audit:
worker:
replicaCount: 1
resources:
requests:
cpu: 1000m
memory: 1024Mi
limits:
cpu: 1000m
memory: 2048Mi
deployment:
replicaCount: 1
resources:
requests:
cpu: 1000m
memory: 4096Mi
limits:
cpu: 3000m
memory: 8192Mi
secure:
backgroundWorker:
replicaCount: 2
resources:
requests:
cpu: 1000m
memory: 4096Mi
limits:
cpu: 4000m
memory: 4096Mi
web:
replicaCount: 2
resources:
requests:
cpu: 1000m
memory: 4096Mi
limits:
cpu: 4000m
memory: 4096Mi
discover:
deployment:
replicaCount: 1
resources:
requests:
cpu: 500m
memory: 4096Mi
limits:
cpu: 3000m
memory: 4096Mi
cache:
deployment:
replicaCount: 1
resources:
requests:
cpu: 500m
memory: 512Mi
limits:
cpu: 1000m
memory: 512Mi# audit
ELASTICSEARCH_USERNAME=<elasticsearch-username>
ELASTICSEARCH_PASSWORD=<elasticsearch-password>
# PostgreSQL connection string used by audit for the metadata database
# postgresql://<user>:<password>@<postgres-fqdn>:5432/<database>?schema=audit
#
# More info
# https://www.postgresql.org/docs/current/libpq-connect.html#LIBPQ-CONNSTRING
DATABASE_CONNECTION_STRING=postgresql://immuta:<postgres-password>@<postgres-fqdn>:5432/immuta?schema=audit
# secure
IMMUTA_DATABASES_IMMUTA_CONNECTIONS_IMMUTADB_PASSWORD=<postgres-password>kubectl create secret generic immuta-secret --from-env-file=secret-data.envrm -i secret-data.envaudit:
deployment:
existingSecret: immuta-secret
export:
cronJob:
existingSecret: immuta-secret
secure:
existingSecret:
name: immuta-secret
# Optional. Map expected keys with keys in existing secret
# keyMapping: {}helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0access-control.config-files=/etc/starburst/immuta-access-control.propertiesaccess-control.config-files=/etc/trino/immuta-access-control.propertiesaccessGrantMapping:
WRITE: ['READ', 'WRITE', 'OWN']
READ: ['READ']immuta.allowed.immuta.datasource.operations=READ,WRITE,OWN
immuta.allowed.non.immuta.datasource.operations=READ,WRITE,CREATE,OWNimmuta.allowed.immuta.datasource.operations=READ,WRITE,OWN
immuta.allowed.non.immuta.datasource.operations=READ,WRITE,CREATE,OWNDependencies
Immuta Detect
✅
❌
Audit of Immuta and data platform events
✅
❌
For information about legacy databases and services no longer enabled in the recommended deployment of Immuta, see the Legacy databases section.
Kubernetes 1.29 - 1.35
PostgreSQL 15.0 or newer
The pgcrypto and btree_gin extensions must be enabled
Elasticsearch v7 API or newer
AWS OpenSearch Service compatible with Elasticsearch v7 API or newer
AWS OpenSearch Serverless is not supported
The user provided during the install must have the following permissions:
Cluster permissions:
cluster:monitor/health
indices:data/write/bulk
indices:data/write/bulk*
indices:data/read/scroll
indices:data/read/scroll/clear
indices:monitor/settings/get
Index permissions:
indices:admin/aliases
indices:admin/aliases*
indices:admin/exists
Follow OpenSearch documentation to create the user and add permissions, or see the OpenSearch authentication guides.
Redis 7.0 or newer
Memcached 1.6 or newer
Temporal 1.24.2 or newer
Amazon Elastic Kubernetes Service (EKS)
AWS Load Balancer Controller
Some legacy databases are no longer available when deploying Immuta using the recommended configuration of the IEHC. See the Enable the legacy query engine guide to enable support for these databases.
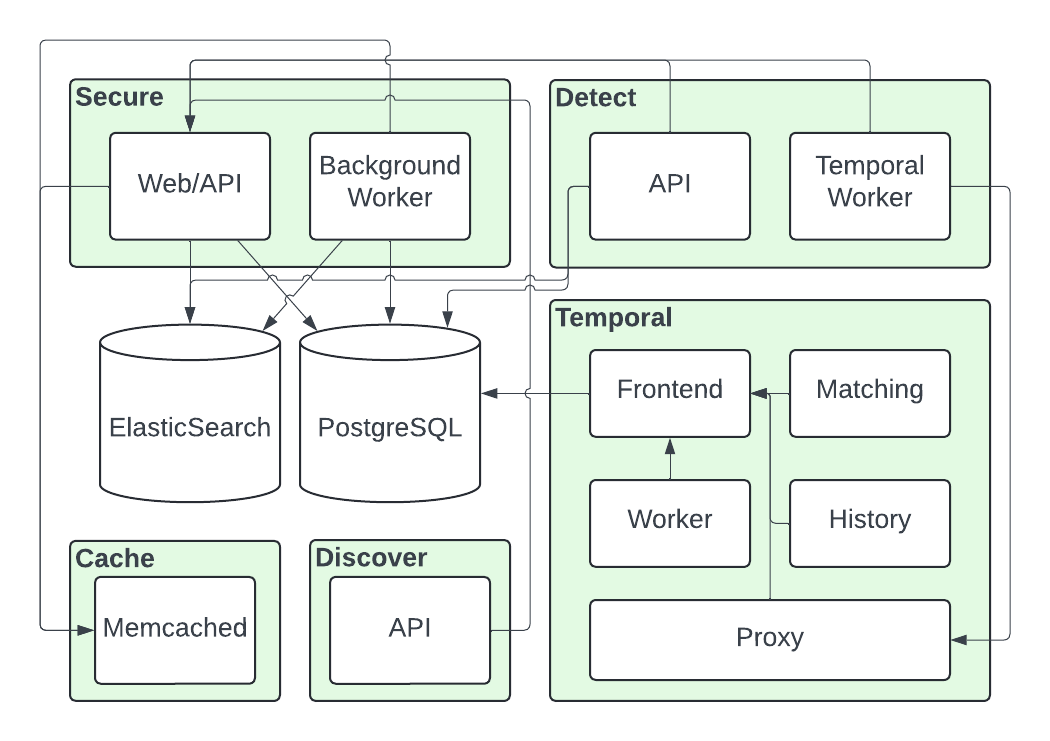
PostgreSQL incompatibilities
Immuta is not compatible with PostgreSQL abstraction layers, such as Amazon Aurora.
secure.ingress was removed in 2026.2
The chart refuses to upgrade while your values file contains a secure.ingress block because applying it would delete your existing and its cloud load balancer. No changes were applied to your deployment.
Follow the ingress migration steps in the , and then run the upgrade again.
onboarding.postgres.database is required
2026.2 introduces the , which requires onboarding.postgresql.database to be set in your values file to the same database name Secure uses. No changes were applied to your deployment.
Follow the to add the Onboarding service, and then run the upgrade again.
global.tenantId must be a valid UUID
The is not set to a UUID. No changes were applied to your deployment.
Set the tenant ID to a UUID and run the .
Create a pod named debug-postgres and spawn an interactive shell.
kubectl run debug-postgres --stdin --tty --rm --image docker.io/bitnami/postgresql:latest -- shValidate that the database is listening.
pg_isready --host <postgres-fqdn> --port 5432Create a pod named debug-redis and spawn an interactive shell.
kubectl run debug-redis --stdin --tty --rm --image docker.io/rockylinux/rockylinux:9 -- shSend a raw TCP message to the database using Netcat.
nc -zv <redis-fqdn> 6379Create a pod named debug-redis and spawn an interactive shell.
kubectl run debug-redis --stdin --tty --rm --image docker.io/bitnami/redis:latest -- shEstablish a connection to the database using the Redis client. If a connection can be established with Netcat and the redis-cli command does not return, then Redis could be expecting a TLS connection. Pass option --tls.
redis-cli -h <redis-fqdn> -p 6379Create a pod named debug-elasticsearch and spawn an interactive shell.
kubectl run debug-elasticsearch --stdin --tty --rm --image docker.io/rockylinux/rockylinux:9 -- shInstall package curl.
dnf install curlCheck the cluster health.
curl --fail --request GET "http://<elasticsearch-fqdn>:9200/_cluster/health?pretty"The Immuta Enterprise Helm chart (IEHC) is distributed as an OCI artifact, and your current Helm version might not support it. Refer to the Helm documentation for further assistance.
Determine your Helm version.
helm versionIf older than 3.8.0 you'll need to upgrade. Before this version OCI support wasn't enabled by default.
Identify the pods that are not ready.
kubectl get podsInspect the events for a failing pod. Look for image pull errors (check your registry secret) and failed probes.
kubectl describe pod <pod-name>Read the pod's logs. Failed connections to PostgreSQL or Elasticsearch are the most common cause; verify that each FQDN is resolvable and accepting connections from within the cluster.
kubectl logs <pod-name> --previousCreate a pod named debug-dns and spawn an interactive shell.
kubectl run debug-dns --stdin --tty --rm --image docker.io/rockylinux/rockylinux:9 -- shInstall package bind-utils.
dnf install bind-utilsPerform DNS lookups on a given FQDN.
dig <fqdn>kubectl get jobskubectl logs job/<job-name>helm list --all-namespaces --output json | jq '.[]|select(.chart | startswith("immuta"))'helm get values <release-name> > immuta-values.yamlkubectl config set-context --current --namespace=<name>scheme "oci" not supported. What's going on?--namespace every time I run a Helm command. How do I set a default?CustomersUsers who are subscribed to the data source in Immuta can then query the corresponding securable directly in their Databricks notebook or workspace.
See the Installation and compliance page for details about the authentication methods supported for registering data.
When schema monitoring is enabled, Immuta monitors your servers to detect when new tables or columns are created or deleted, and automatically registers (or disables) those tables in Immuta. These newly updated data sources will then have any global policies and tags that are set in Immuta applied to them. The Immuta data source columns will be updated with any column changes, and the Immuta environment will be in sync with your data environment.
For Databricks Spark, the automatic schema monitoring job is disabled because of the ephemeral nature of Databricks clusters. In this case, Immuta requires you to download a schema detection job template (a Python script) and import that into your Databricks workspace.
See the Register a Databricks data source guide for instructions on enabling schema monitoring.
In Immuta, a Databricks data source is considered ephemeral, meaning that the compute resources associated with that data source will not always be available.
Ephemeral data sources allow the use of ephemeral overrides, user-specific connection parameter overrides that are applied to Immuta metadata operations.
When a user runs a Spark job in Databricks, the Immuta plugin automatically submits ephemeral overrides for that user to Immuta. Consequently, subsequent metadata operations for that user will use the current cluster as compute.
See the Ephemeral overrides page for more details about ephemeral overrides and how to configure or disable them.
The Spark plugin has the capability to send ephemeral override requests to Immuta. These requests are distinct from ephemeral overrides themselves. Ephemeral overrides cannot be turned off, but the Spark plugin can be configured to not send ephemeral override requests.
Tags can be used in Immuta in a variety of ways:
Use tags for global subscription or data policies that will apply to all data sources in the organization. In doing this, company-wide data security restrictions can be controlled by the administrators and governors, while the users and data owners need only to worry about tagging the data correctly.
Generate Immuta reports from tags for insider threat surveillance or data access monitoring.
Filter search results with tags in the Immuta UI.
The Databricks Spark integration cannot ingest tags from Databricks, but you can connect any of these supported external catalogs to work with your integration.
You can also manage tags in Immuta by manually adding tags to your data sources and columns. Alternatively, you can use identification to automatically tag your sensitive data.
Immuta allows you to author subscription and data policies to automate access controls on your Databricks data.
Subscription policies: After registering data sources in Immuta, you can control who has access to specific securables in Databricks through Immuta subscription policies or by manually adding users to the data source. Data users will only see the immuta database with no tables until they are granted access to those tables as Immuta data sources. See the Subscription policy access types page for a list of policy types supported.
Data policies: You can create data policies to apply fine-grained access controls (such as restricting rows or masking columns) to manage what users can see in each table after they are subscribed to a data source. See the Data policy types page for details about specific types of data policies supported.
The image below illustrates how Immuta enforces a subscription policy that only allows users in the Analysts group to access the yellow-table.
See the Automate data access control decisions page for details about the benefits of using Immuta subscription and data policies.
Once a Databricks user who is subscribed to the data source in Immuta queries the corresponding securable directly in their workspace, Spark Analysis initiates and the following events take place:
Spark calls down to the Metastore to get table metadata.
Immuta intercepts the call to retrieve table metadata from the Metastore.
Immuta modifies the Logical Plan to enforce policies that apply to that user.
Immuta wraps the Physical Plan with specific Java classes to signal to the Security Manager that it is a trusted node and is allowed to scan raw data.
The Physical Plan is applied and filters out and transforms raw data coming back to the user.
The user sees policy-enforced data.
The image below illustrates what happens when an Immuta user who is subscribed to the Customers data source queries the securable in Databricks.
Regardless of the policies on the data source, the users will be able to read raw data on the cluster if they meet one of the criteria listed below:
Databricks administrator is tied to an Immuta account
A Databricks user is listed as an ignored user (Users can be specified in the IMMUTA_SPARK_ACL_ALLOWLIST Spark environment variable to become ignored users.)
Generally, Immuta prevents users from seeing data unless they are explicitly given access, which blocks access to raw sources in the underlying databases.
Databricks non-admin users will only see sources to which they are subscribed in Immuta, and this can present problems if organizations have a data lake full of non-sensitive data and Immuta removes access to all of it. To address this challenge, Immuta allows administrators to change this default setting when configuring the integration so that Immuta users can access securables that are not registered as a data source. Although this is similar to how privileged users in Databricks operate, non-privileged users cannot bypass Immuta controls.
See the Customizing the integration guide for details about this setting.
Immuta projects combine users and data sources under a common purpose. Sometimes this purpose is for a single user to organize their data sources or to control an entire schema of data sources through a single projects screen; however, most often this is an Immuta purpose for which the data has been approved to be used and will restrict access to data and streamline team collaboration. Consequently, data owners can restrict access to data for a specified purpose through projects.
When a user is working within the context of a project, they will only see the data in that project. This helps to prevent data leaks when users collaborate. Users can switch project contexts to access various data sources while acting under the appropriate purpose.
When users change project contexts (either through the Immuta UI or with project UDFs), queries reflect users as acting under the purposes of that project, which may allow additional access to data if there are purpose restrictions on the data source(s). This process also allows organizations to track not just whether a specific data source is being used, but why.
See the Customizing the integration page for details about how to prevent users from switching project contexts in a session.
Users can have additional write access in their integration using project workspaces. Users can integrate a single or multiple workspaces with a single Immuta tenant.
See the Project workspaces page for more details.
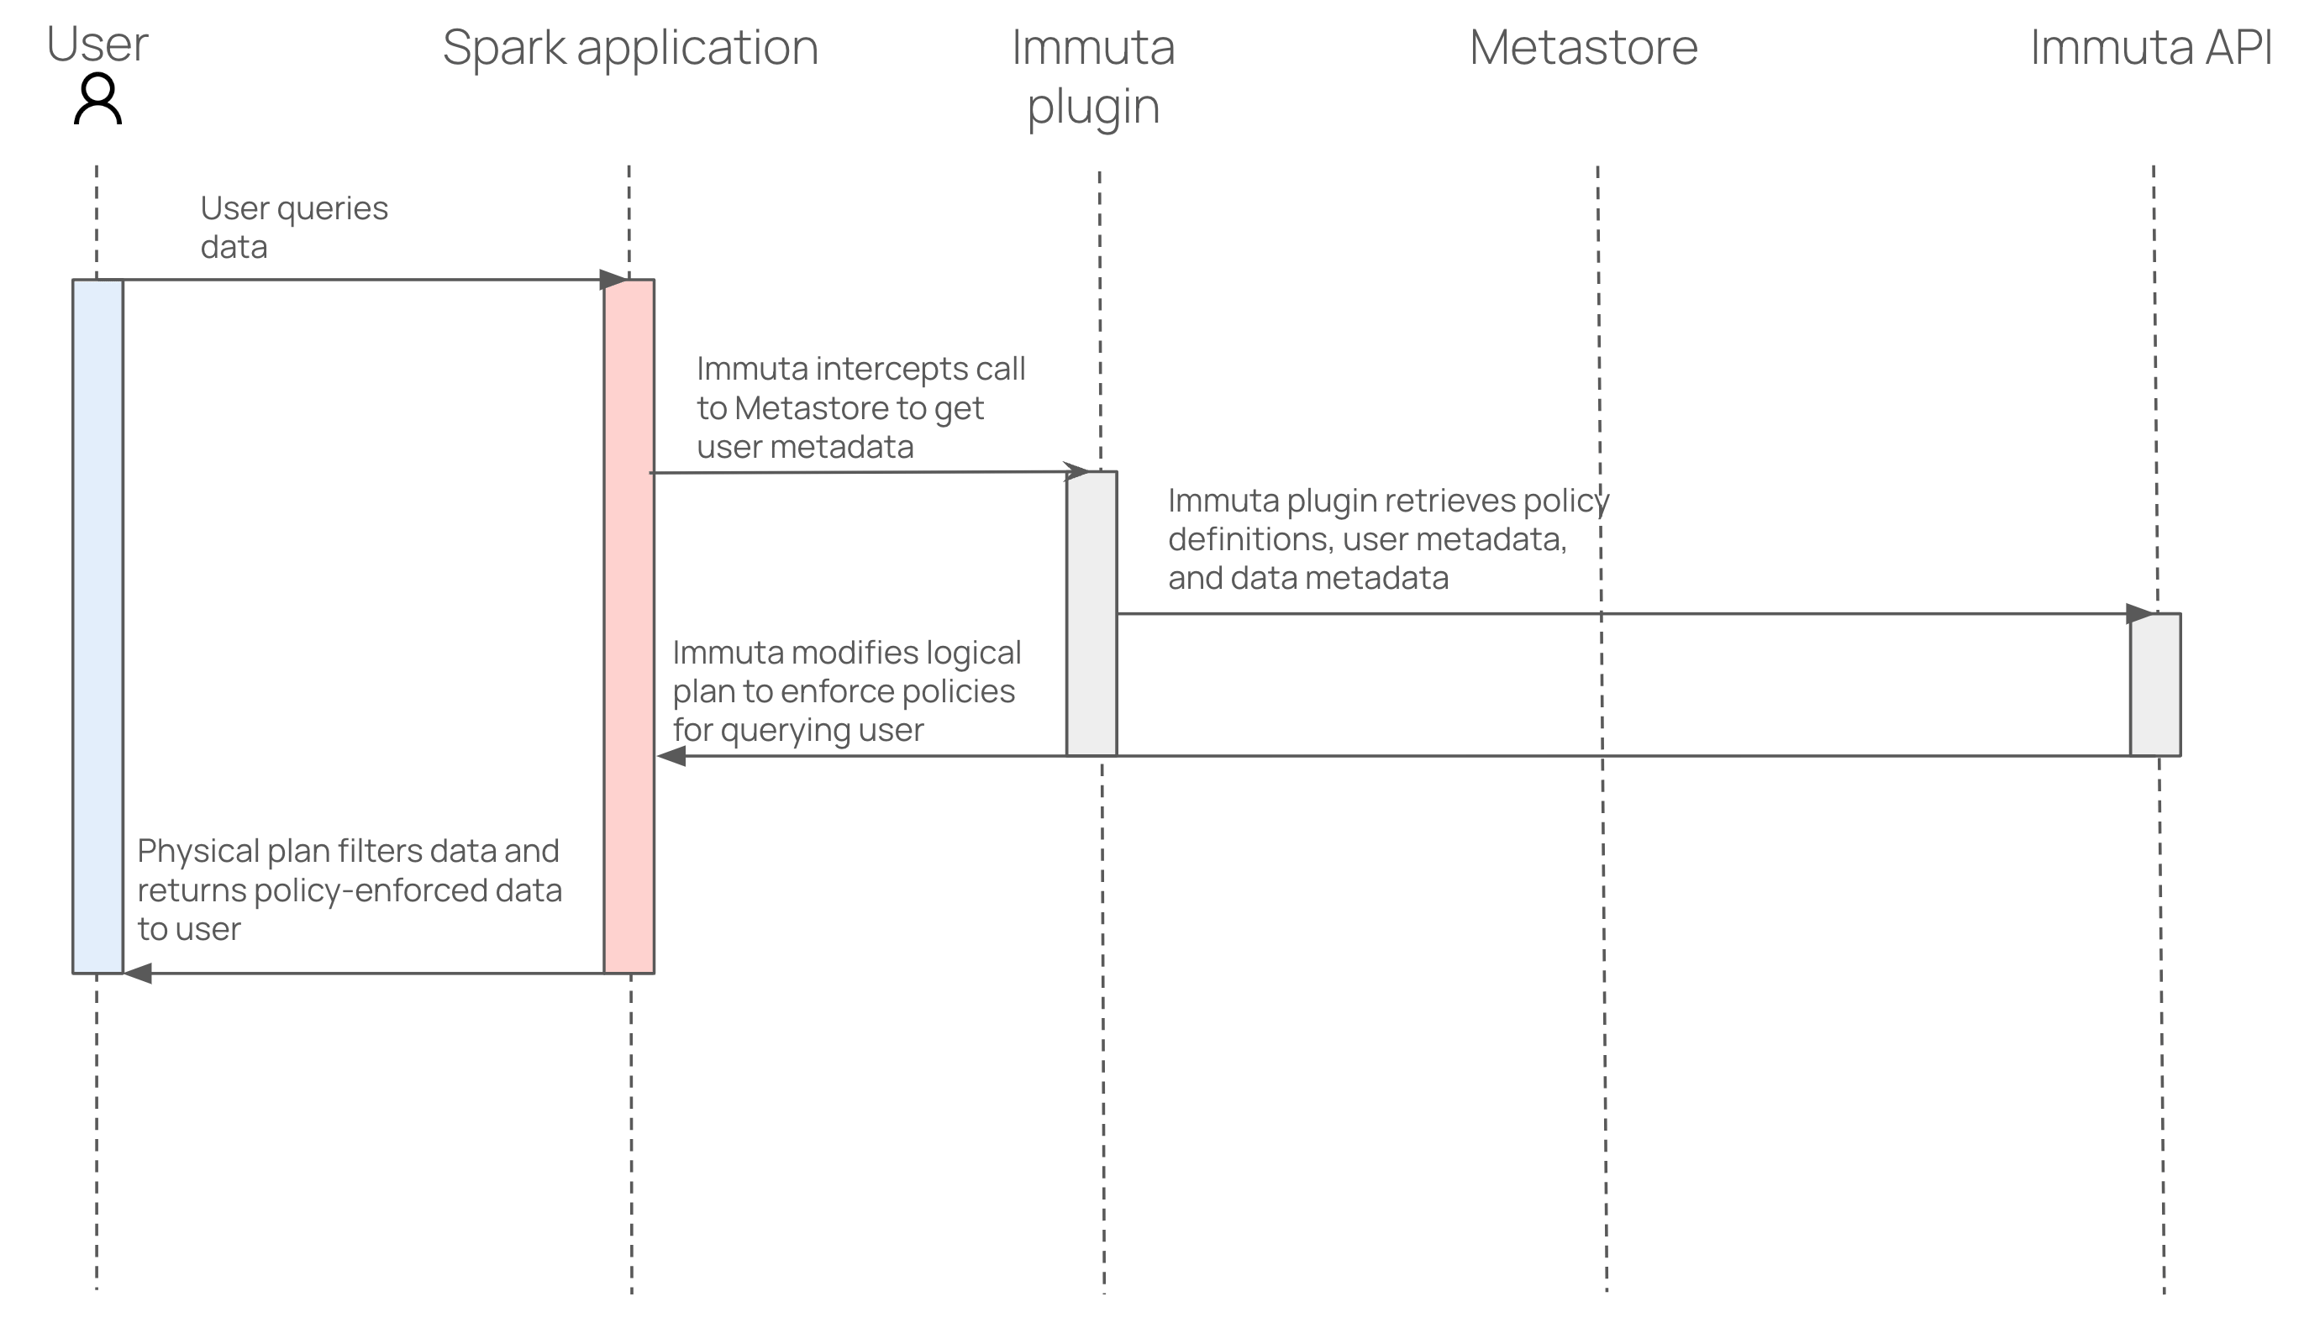
The enable_case_sensitive_identifier parameter must be set to false (default setting) for your Redshift cluster.
Click the App Settings icon in the navigation menu.
Click the Integrations tab.
Click the +Add Integration button and select Redshift from the dropdown menu.
Complete the Host and Port fields.
Enter an Immuta Database. This is a new database where all secure schemas and Immuta created views will be stored.
Opt to check the Enable Impersonation box and customize the Impersonation Role name as needed. This will allow users to natively impersonate another user. Once you finish configuring the integration, you can grant the IMPERSONATE_USER permission to Immuta users. See the for instructions.
You have two options for configuring your Redshift environment:
Automatic setup: Grant Immuta one-time use of credentials to automatically configure your Redshift environment and the integration.
Manual setup: Run the Immuta script in your Redshift environment yourself to configure your environment and the integration.
Select Automatic.
Enter an Initial Database from your Redshift integration for Immuta to use to connect.
Use the dropdown menu to select your Authentication Method.
Username and Password: Enter the Username and Password of the privileged user.
AWS Access Key: Enter the Database User, Access Key ID, and Secret Key. Opt to enter in the Session Token.
Select Manual and download both of the bootstrap scripts from the Setup section.
Run the bootstrap script (initial database) in the Redshift initial database.
Run the bootstrap script (Immuta database) in the new Immuta Database in Redshift.
Choose your authentication method, and enter the information of the newly created account.
Click Save.
Click the App Settings icon in the navigation menu.
Navigate to the Integrations tab and click the down arrow next to the Redshift Integration.
Edit the field you want to change. Note any field shadowed is not editable, and the integration must be disabled and re-installed to change it.
Enter Username and Password.
Click Save.
Click the App Settings icon in the navigation menu.
Navigate to the Integrations tab and click the down arrow next to the Redshift Integration.
Click the checkbox to disable the integration.
Enter the username and password that were used to initially configure the integration.
Click Save.
Disabling Redshift Spectrum
Disabling the Redshift integration is not supported when you set the fields nativeWorkspaceName, nativeViewName, and nativeSchemaName to Disabling the integration when these fields are used in metadata ingestion causes undefined behavior.
Register your Snowflake data
APPLICATION_ADMIN Immuta permission
The Snowflake user registering the connection and running the script must have the following privileges:
CREATE DATABASE ON ACCOUNT WITH GRANT OPTION
CREATE ROLE ON ACCOUNT WITH GRANT OPTION
MANAGE GRANTS ON ACCOUNT WITH GRANT OPTION
Complete the following actions in Snowflake:
. Immuta will use this system account continuously to orchestrate Snowflake policies and maintain state between Immuta and Snowflake.
with a minimum of the following privileges:
USAGE on all databases and schemas with registered data sources.
To register a Snowflake connection, follow the instructions below.
Click Data and select the the Connections tab in the navigation menu.
Click the + Add Connection button.
Select the Snowflake data platform tile.
Enter the connection information:
Click Next.
Configure the Policy settings:
Opt to enable Impersonation. If you enable it, enter the Impersonation Role that will be used to impersonate other users in Snowflake.
Learn about the available Spark environment variables so that you can customize your Databricks Spark integration
This page outlines configuration details for Immuta-enabled Databricks clusters. Databricks administrators should place the desired configuration in the Spark environment variables.
If you add additional Hadoop configuration during the integration setup, this variable sets the path to that file.
The additional Hadoop configuration is where sensitive configuration goes for remote filesystems (if you are using a secret key pair to access S3, for example).
Default value: true
Set this to false if ephemeral overrides should not be enabled for Spark. When true, this will automatically override ephemeral data source httpPaths with the httpPath of the Databricks cluster running the user's Spark application.
This configuration item can be used if automatic detection of the Databricks httpPath should be disabled in favor of a static path to use for ephemeral overrides.
Default value: true
When querying Immuta data sources in Spark, the metadata from the Metastore is compared to the metadata for the target source in Immuta to validate that the source being queried exists and is queryable on the current cluster. This check typically validates that the target (database, table) pair exists in the Metastore and that the table’s underlying location matches what is in Immuta. This configuration can be used to disable location checking if that location is dynamic or changes over time. Note: This may lead to undefined behavior if the same table names exist in multiple workspaces but do not correspond to the same underlying data.
A URI that points to a valid calling class file, which is an Immuta artifact you download during the process.
This is a comma-separated list of Databricks users who can access any table or view in the cluster metastore without restriction.
Default value: 3600
The number of seconds to cache privileged user status for the Immuta ACL. A privileged Databricks user is an admin or is allowlisted in IMMUTA_SPARK_ACL_ALLOWLIST.
Default value: false
Enables auditing all queries run on a Databricks cluster, regardless of whether users touch Immuta-protected data or not.
Default value: false
Allows non-privileged users to SELECT from tables that are not protected by Immuta. See the for details about this feature.
Default value: false
Allows non-privileged users to run DDL commands and data-modifying commands against tables or spaces that are not protected by Immuta. See the for details about this feature.
This is a comma-separated list of Databricks users who are allowed to impersonate Immuta users:
Default value: false
Exposes the DBFS FUSE mount located at /dbfs. Granular permissions are not possible, so all users will have read/write access to all objects therein. Note: Raw, unfiltered source data should never be stored in DBFS.
Block one or more Immuta from being used on an Immuta cluster. This should be a Java regular expression that matches the set of UDFs to block by name (excluding the immuta database). For example to block all project UDFs, you may configure this to be ^.*_projects?$. For a list of functions, see the .
Default value: file:///databricks/jars/immuta-spark-hive.jar
The location of immuta-spark-hive.jar on the filesystem for Databricks. This should not need to change unless a custom initialization script that places immuta-spark-hive in a non-standard location is necessary.
Default value: true
Creates a world-readable or writable scratch directory on local disk to facilitate the use of dbutils and 3rd party libraries that may write to local disk. Its location is non-configurable and is stored in the environment variable IMMUTA_LOCAL_SCRATCH_DIR. Note: Sensitive data should not be stored at this location.
Default value: INFO
The SLF4J log level to apply to Immuta's Spark plugins.
Default value: false
If true, writes logging output to stdout/the console as well as the log4j-active.txt file (default in Databricks).
This configuration is a comma-separated list of additional databases that will appear as scratch databases when running a SHOW DATABASE query. This configuration increases performance by circumventing the Metastore to get the metadata for all the databases to determine what to display for a SHOW DATABASE query; it won't affect access to the scratch databases. Instead, use to control read and write access to the underlying database paths.
Additionally, this configuration will only display the scratch databases that are configured and will not validate that the configured databases exist in the Metastore. Therefore, it is up to the Databricks administrator to properly set this value and keep it current.
Comma-separated list of remote paths that Databricks users are allowed to directly read/write. These paths amount to unprotected "scratch spaces." You can create a scratch database by configuring its specified location (or configure dbfs:/user/hive/warehouse/<db_name>.db for the default location).
To create a scratch path to a location or a database stored at that location, configure
To create a scratch path to a database created using the default location,
Default value: false
Enables non-privileged users to create or drop scratch databases.
Default value: false
When true, this configuration prevents users from changing their impersonation user once it has been set for a given Spark session. This configuration should be set when the BI tool or other service allows users to submit arbitrary SQL or issue SET commands.
Default value: true
Denotes whether the Spark job will be run that "tags" a Databricks cluster as being associated with Immuta.
A comma-separated list of URIs.
Default value: 3600
The number of seconds Immuta caches whether a table has been exposed as a data source in Immuta. This setting only applies when IMMUTA_SPARK_DATABRICKS_ALLOW_NON_IMMUTA_WRITES or IMMUTA_SPARK_DATABRICKS_ALLOW_NON_IMMUTA_READS is enabled.
Default value: false
Requires that users act through a single, equalized project. A cluster should be equalized if users need to run Scala jobs on it, and it should be limited to Scala jobs only via spark.databricks.repl.allowedLanguages.
Default value: true
Enables use of the underlying database and table name in queries against a table-backed Immuta data source. Administrators or allowlisted users can set IMMUTA_SPARK_RESOLVE_RAW_TABLES_ENABLED to false to bypass resolving raw databases or tables as Immuta data sources. This is useful if an admin wants to read raw data but is also an Immuta user. By default, data policies will be applied to a table even for an administrative user if that admin is also an Immuta user.
Default value: true
Same as the variable, but this is a session property that allows users to toggle this functionality. If users run set immuta.spark.session.resolve.raw.tables.enabled=false, they will see raw data only (not Immuta data policy-enforced data). Note: This property is not set in immuta_conf.xml.
Default value: true
This shows the immuta database in the configured Databricks cluster. When set to false Immuta will no longer show this database when a SHOW DATABASES query is performed. However, queries can still be performed against tables in the immuta database using the Immuta-qualified table name (e.g., immuta.my_schema_my_table) regardless of whether or not this feature is enabled.
Default value: true
Immuta checks the versions of its artifacts to verify that they are compatible with each other. When set to true, if versions are incompatible, that information will be logged to the Databricks driver logs and the cluster will not be usable. If a configuration file or the jar artifacts have been patched with a new version (and the artifacts are known to be compatible), this check can be set to false so that the versions don't get logged as incompatible and make the cluster unusable.
Default value: bim
Denotes which IAM in Immuta should be used when mapping the current Spark user's username to a userid in Immuta. This defaults to Immuta's internal IAM (bim) but should be updated to reflect an actual production IAM.
This guide demonstrates how to configure . Ingress can be configured in numerous ways. Configurations for the most popular controllers are outlined below.
The Immuta web service listens on the following ports:
APPLICATION_ADMIN Immuta permission
CAN MANAGE Databricks privilege on the cluster
A Databricks workspace with the Premium tier, which includes cluster policies (required to configure the Spark integration)
Register your Trino data
For Trino connections
Trino cluster
For Starburst connections
A valid .
The user registering the connection must have the permissions below.
indices:admin/delete
indices:admin/settings/update
indices:admin/get
indices:admin/refresh
indices:admin/refresh*
indices:admin/mapping/put
indices:data/read/search
indices:data/read/scroll
indices:data/read/scroll/clear
indices:data/write/delete
indices:data/write/delete/byquery
indices:data/write/index
indices:data/write/bulk
indices:data/write/bulk*
indices:data/write/update/byquery
indices:monitor/settings/get
Legacy audit
❌
❌
Immuta Monitors
✅
❌
Identification
✅
✅
Azure Kubernetes Service (AKS)
Azure Application Gateway Ingress Controller
Google Kubernetes Engine (GKE)
GKE Ingress Controller
Red Hat OpenShift
OpenShift Ingress Operator
Cloud-managed PostgreSQL
Cloud-managed Elasticsearch
TENANT_ID must be a valid UUID and must not be the all-zeros UUID (in the audit-init job)
There is no global.tenantId set in the immuta-values.yaml file.
Set the tenant ID to a UUID and run the upgrade again.
Missing required environment variables for self-managed use: SEARCH_INDEX_NAME, SEARCH_INDEX_ALIAS_NAME (in the audit-init job)
Index names were not set.
Set these environment variables and run the upgrade again.
UPGRADE FAILED: ... timed out while the secure-database-migrate job is still running
The Helm timeout was too short.
Wait for the job to complete (kubectl get jobs), and then run the upgrade again with a longer --timeout.
ImagePullBackOff on a job pod
Registry credentials have expired.
Recreate the registry secret from the installation guide and delete the stuck pod; the job will retry.
CREATE USERREVOKE ALL PRIVILEGES ON DATABASE
GRANT TEMP ON DATABASE
MANAGE GRANTS ON ACCOUNT
These privileges will be used to create and configure a new IMMUTA database within the specified Redshift instance. The credentials are not stored or saved by Immuta, and Immuta doesn’t retain access to them after initial setup is complete.
You can create a new account for Immuta to use that has these privileges, or you can grant temporary use of a pre-existing account. By default, the pre-existing account with appropriate privileges is a Superuser. If you create a new account, it can be deleted after initial setup is complete.
Alternatively, you can create the IMMUTA database within the specified Redshift instance without giving Immuta user credentials for a Superuser using the manual setup option.
REVOKE ALL PRIVILEGES ON DATABASE
GRANT TEMP ON DATABASE
MANAGE GRANTS ON ACCOUNT
Modify grants
Alternatively, you can download the Edit Script from your Redshift configuration on the Immuta app settings page and run it in Redshift.
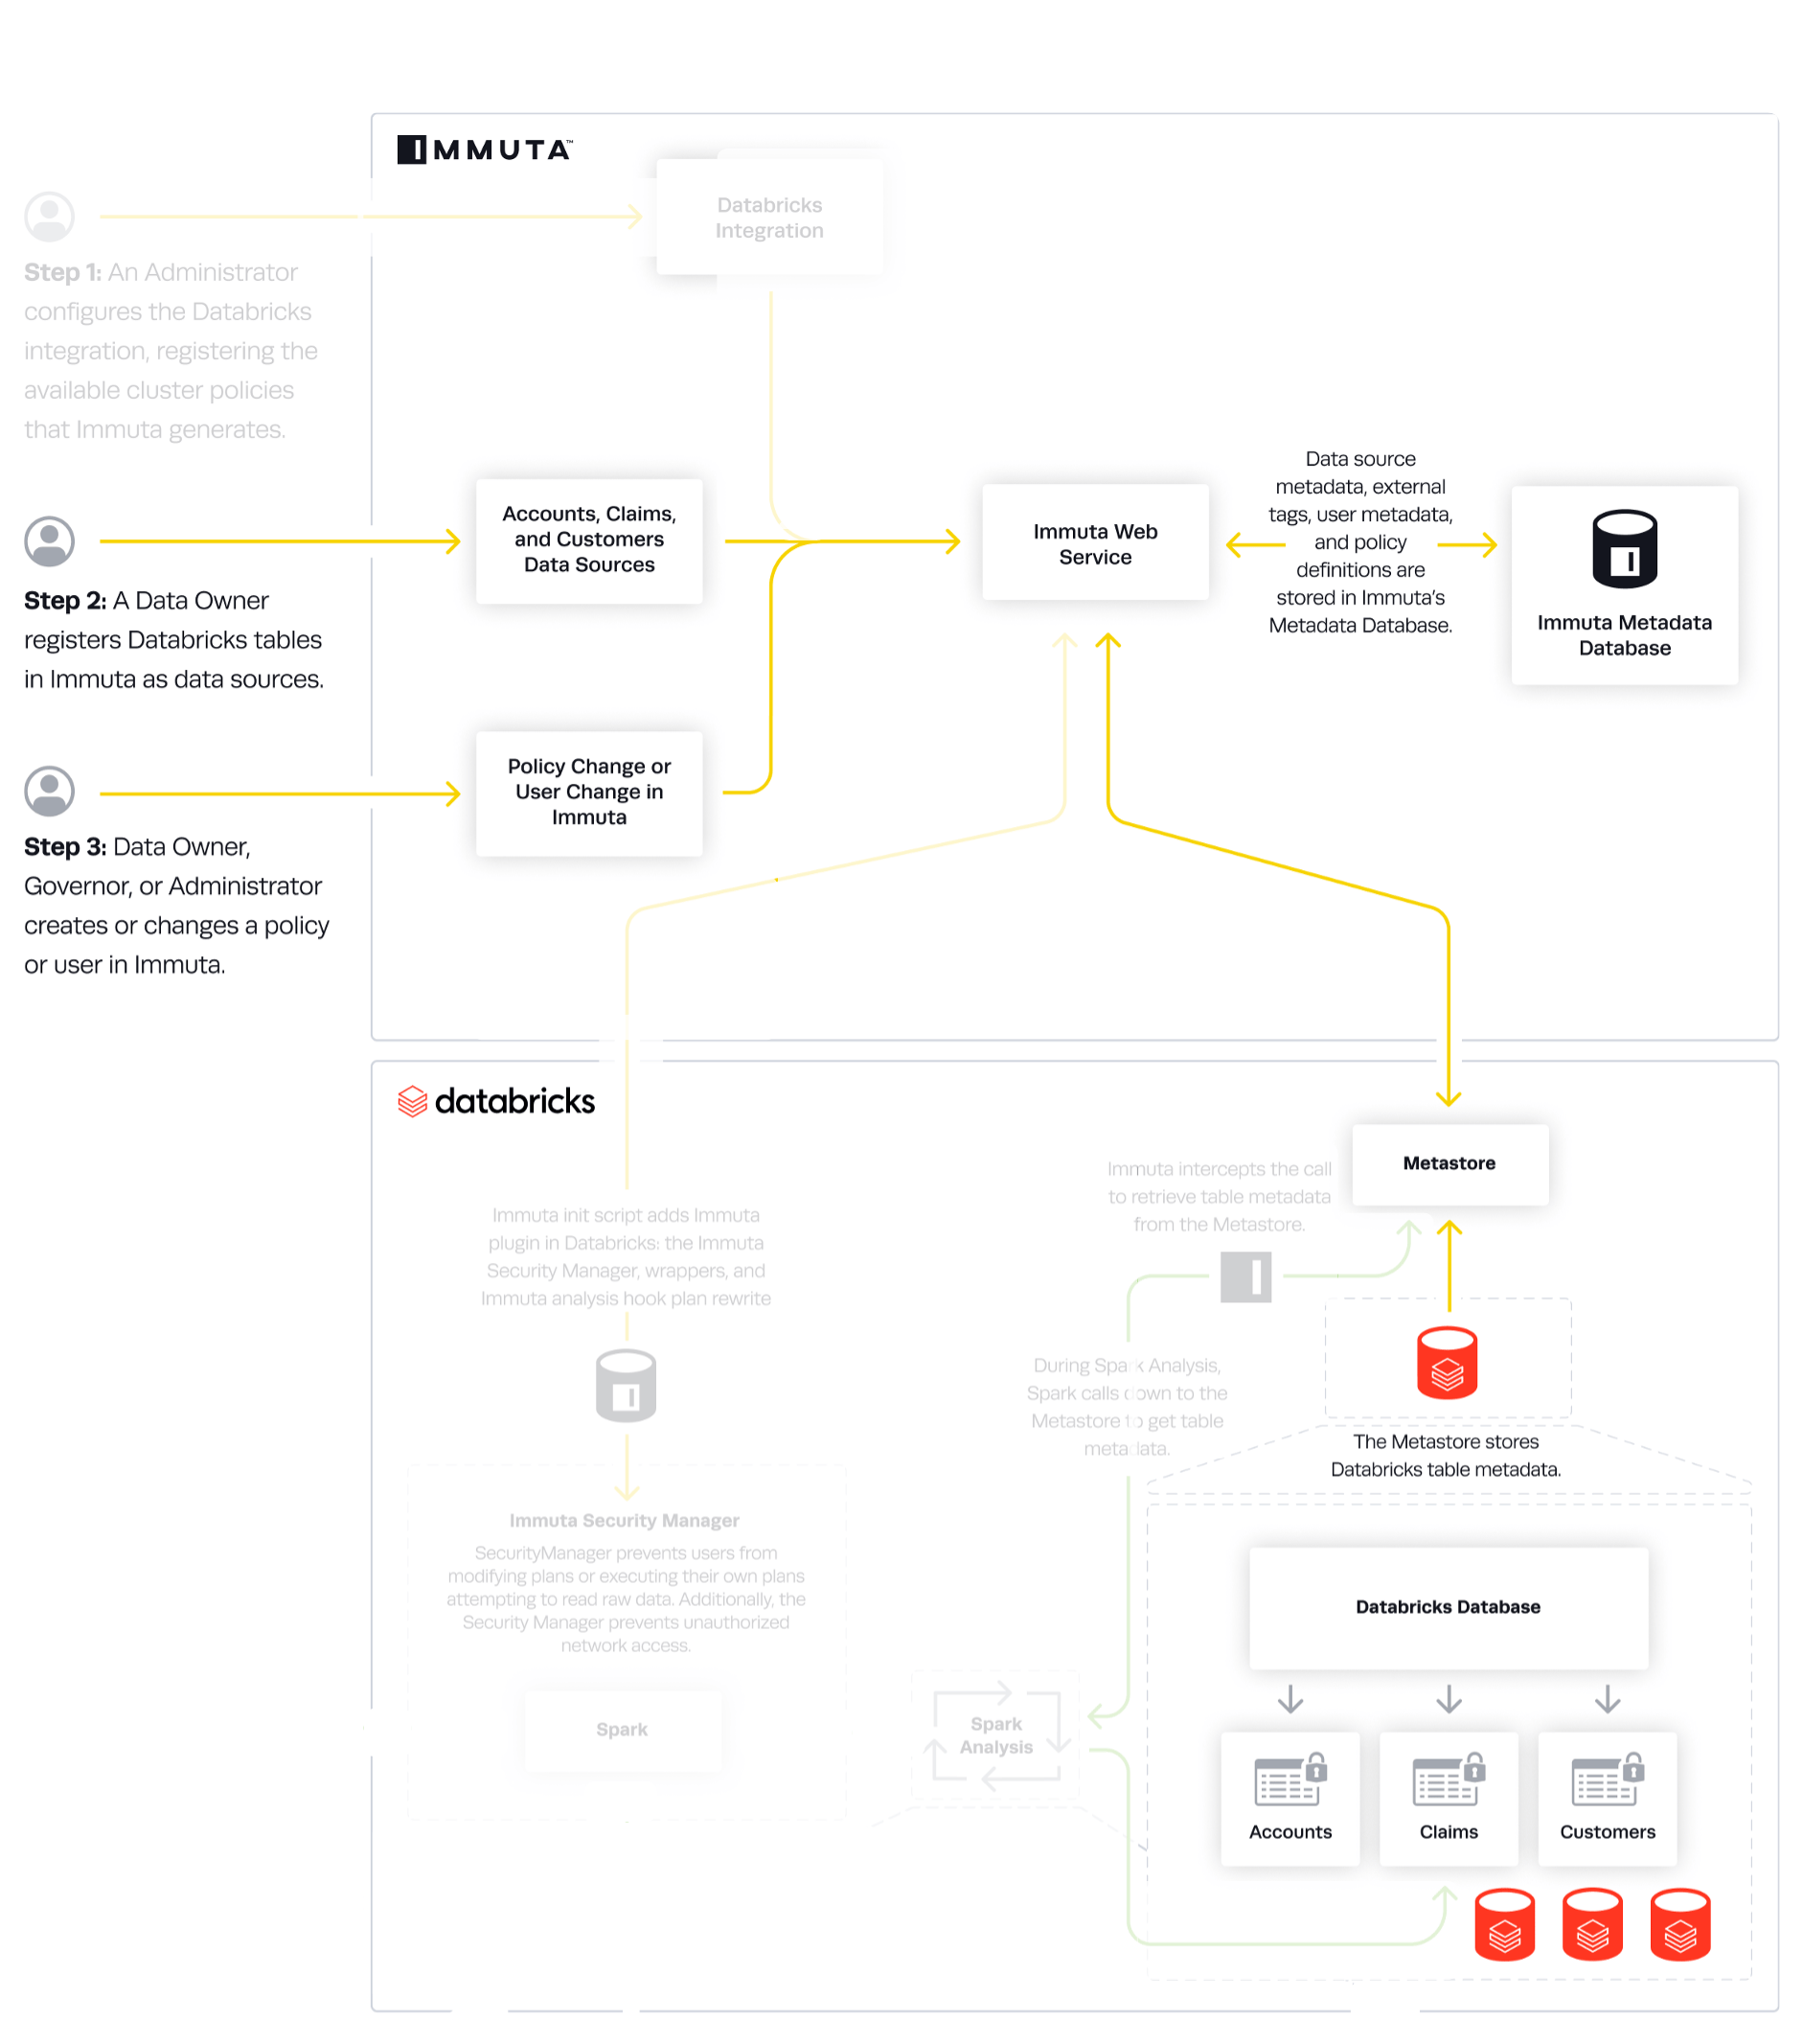
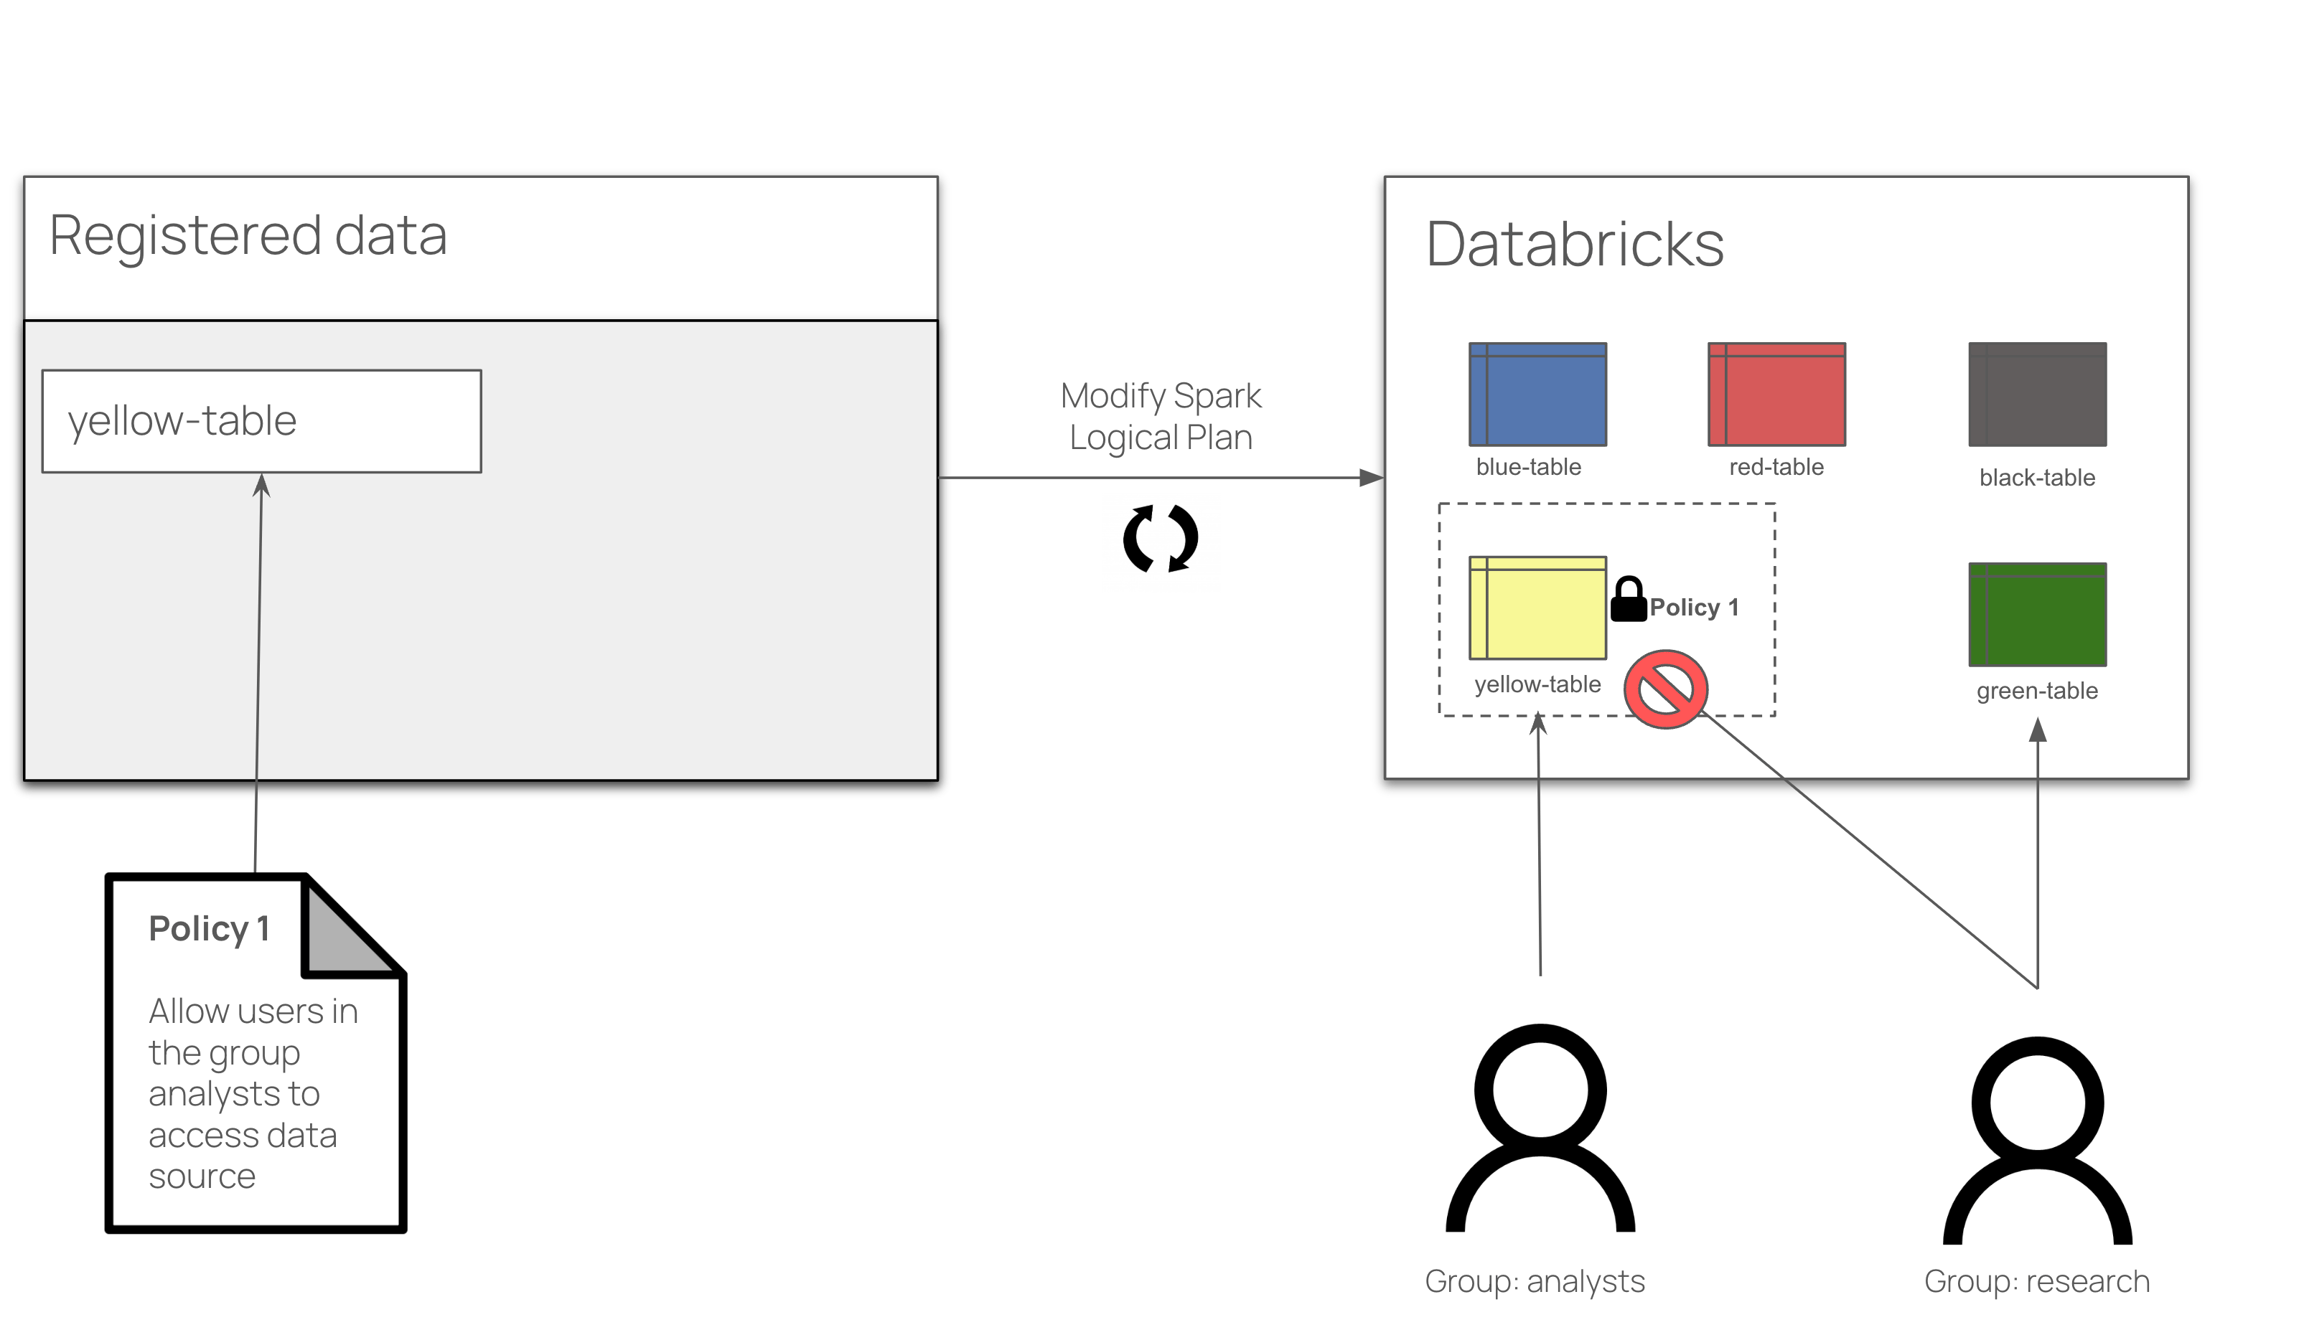
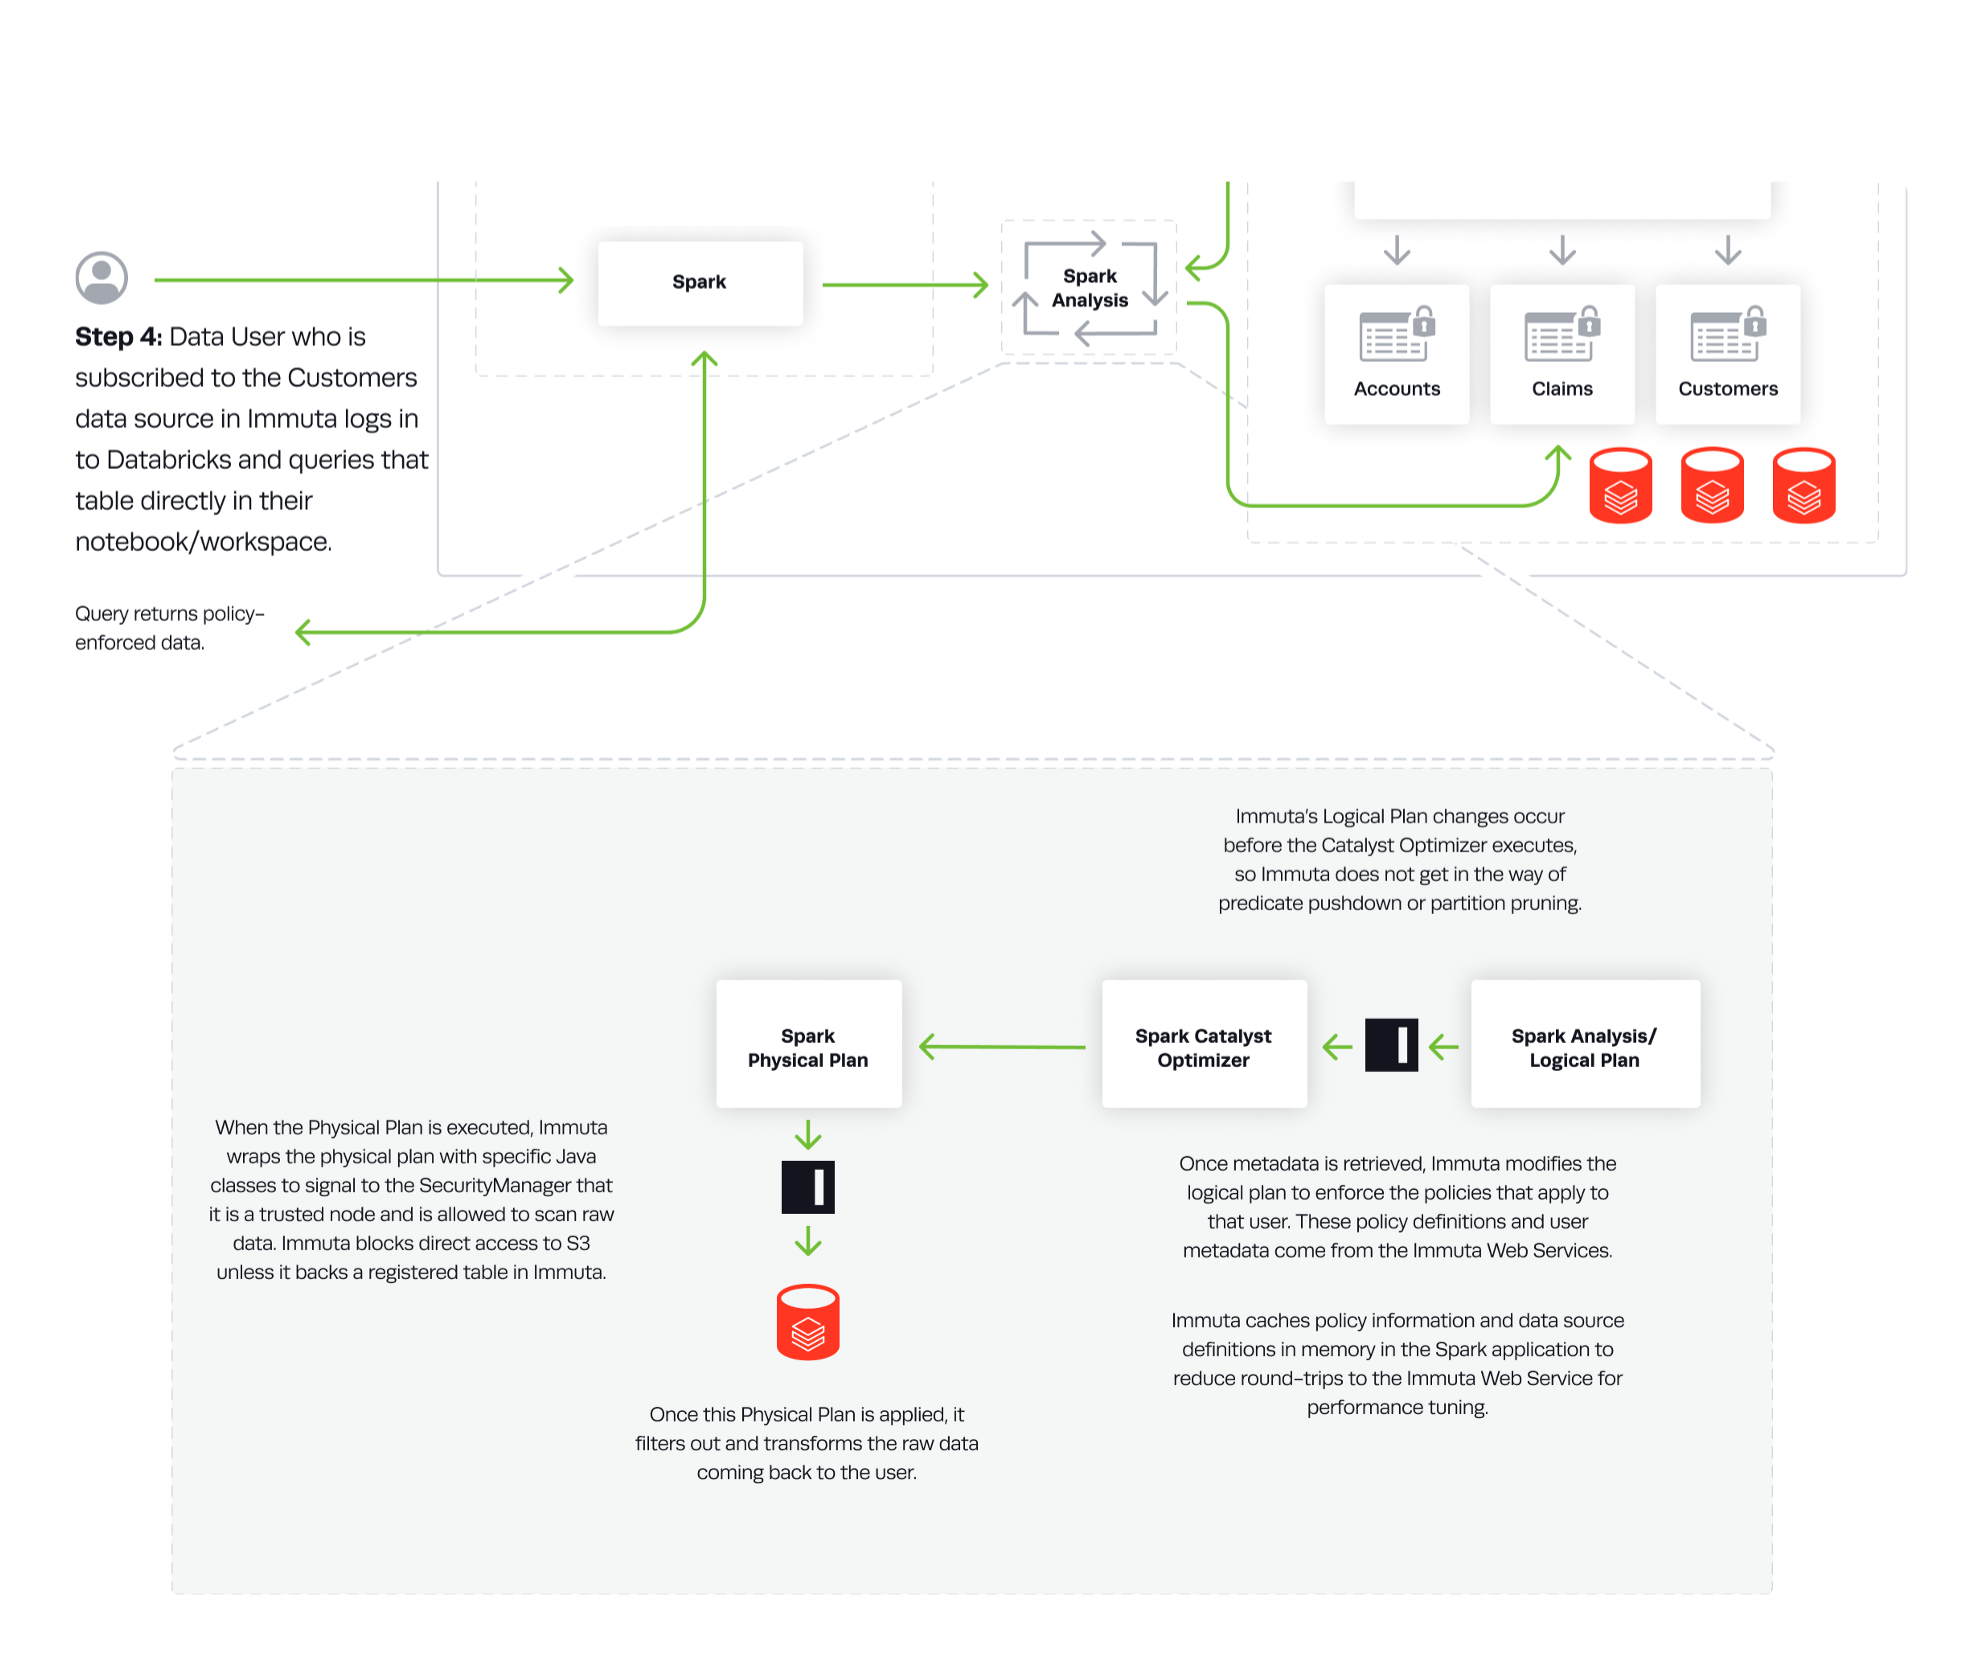
USAGE on the external volume.REFERENCES on all tables and views registered in Immuta.
SELECT on all tables and views registered in Immuta.
Grant the new Snowflake role to the system account you just created.
Display Name: The display name represents the unique name of your connection and will be used as prefix in the name for all data objects associated with this connection. It will also appear as the display name in the UI and will be used in all API calls made to update or delete the connection. Avoid the use of periods (.) or restricted words in your connection name.
Host: The URL of your Snowflake account.
Port: Your Snowflake port.
Warehouse: The warehouse the Immuta system account user will use to run queries and perform Snowflake operations.
Role: Enter the role with the listed privileges.
Immuta Database: The new, empty database for Immuta to manage. The script in the last step of registering the connection will create this database. This is where system views, user entitlements, row access policies, column-level policies, procedures, and functions managed by Immuta will be created and stored.
Opt to configure an HTTP proxy for this connection by selecting Enable and entering the required details:
Proxy Host: Enter the full proxy URL.
Proxy Port: Enter the proxy port.
Select if the proxy requires authentication:
Disabled
Enabled:
Proxy Username: Enter the username for the proxy connection.
Proxy Password: Enter the password for the proxy connection.
Select an authentication method from the dropdown menu and enter the authentication information for the Immuta system account you created.
Click Next.
Opt to Enable Audit.
Click Next.
Opt to Enable Object Sync, which will keep your connection objects up to date with your Snowflake environment.
Select the Start Time for when the first object sync job will run each day.
Select the Run Frequency to determine how frequently object sync will run each day.
Opt to Run Object Sync on Create to create all the data objects for your connection. If you do not select this option, you must run object sync manually or wait for the scheduled object sync for your connection's data objects.
Click Save connection.
Copy the provided script and run it in Snowflake as a user with the privileges listed in the requirements section. Running this script grants the following privileges to the Immuta system account and creates the new Immuta database in Snowflake:
CREATE ROLE ON ACCOUNT WITH GRANT OPTION
MANAGE GRANTS ON ACCOUNT WITH GRANT OPTION
APPLY MASKING POLICY ON ACCOUNT WITH GRANT OPTION
APPLY ROW ACCESS POLICY ON ACCOUNT WITH GRANT OPTION
Click Validate Connection.
If the connection is successful, click Finish. If there are any errors, check the connection details and credentials to ensure they are correct and try again.
"spark_env_vars.IMMUTA_SPARK_DATABRICKS_ALLOWED_IMPERSONATION_USERS": {
"type": "fixed",
"value": "edixon@example.com,dakota@example.com"
}IMMUTA_SPARK_DATABRICKS_SCRATCH_PATHS=s3://path/to/the/dirIMMUTA_SPARK_DATABRICKS_SCRATCH_PATHS=s3://path/to/the/dir,dbfs:/user/hive/warehouse/any_db_name.db</value>HTTPS
False
80
TCP
HTTP (redirects to HTTPS)
True
Edit the immuta-values.yaml file to include the following Helm values.
gateway:
ingress:
enabled: true
hostname: <immuta-fqdn>
ingressClassName: nginx
annotations:
nginx.ingress.kubernetes.io/proxy-body-size: '64m'Perform a Helm upgrade to apply the changes made to immuta-values.yaml.
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0Refer to the Ingress-Nginx Controller documentation for further assistance.
Edit immuta-values.yaml to include the following Helm values.
gateway:
ingress:
enabled: true
hostname: <immuta-fqdn>
annotations:
# Determines which type of load balancer is provisioned
# gce-internal
# gce
kubernetes.io/ingress.class: gce
# Listen on both 80 and 443
kubernetes.io/ingress.allow-http: 'true'
# Redirect traffic from 80 to 443
cloud.google.com/frontend-config: immutaCreate a file named frontendconfig.yaml with the following content.
apiVersion: networking.gke.io/v1beta1
kind: FrontendConfig
metadata:
name: immuta
spec:
redirectToHttps:
enabled: true
responseCodeName: RESPONSE_CODEApply the FrontendConfig CRD.
kubectl apply -f frontendconfig.yamlPerform a to apply the changes made to immuta-values.yaml.
Refer to the Google Cloud documentation for further assistance.
Edit immuta-values.yaml to include the following Helm values.
gateway:
ingress:
enabled: true
hostname: <immuta-fqdn>
ingressClassName: alb
annotations:
# Determines which type of load balancer is provisioned
# internal
# internet-facing
alb.ingress.kubernetes.io/scheme: internet-facing
alb.ingress.kubernetes.io/target-type: ip
# Listen on both 80 and 443
alb.ingress.kubernetes.io/listen-ports: '[{"HTTP": 80}, {"HTTPS":443}]'
# Redirect traffic from 80 to 443
alb.ingress.kubernetes.io/ssl-redirect: '443'Perform a Helm upgrade to apply the changes made to immuta-values.yaml.
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0Refer to the AWS Load Balancer Controller documentation for further assistance.
Edit immuta-values.yaml to include the following Helm values.
gateway:
ingress:
enabled: true
hostname: <immuta-fqdn>
ingressClassName: webapprouting.kubernetes.azure.com
# https://azure.github.io/application-gateway-kubernetes-ingress/annotations/
annotations:
appgw.ingress.kubernetes.io/ssl-redirect: 'true'Perform a Helm upgrade to apply the changes made to immuta-values.yaml.
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0Refer to the Application Gateway Ingress Controller documentation for further assistance.
Edit immuta-values.yaml to include the following Helm values.
gateway:
ingress:
enabled: true
hostname: <immuta-fqdn>
ingressClassName: traefik
annotations:
# Listen on ports 80 and 443
traefik.ingress.kubernetes.io/router.entrypoints: web,websecure
# Redirect HTTP to HTTPS
# When referencing middleware you must prefix the name with its namespace
# <namespace>-<middleware-name>@kubernetescrd
traefik.ingress.kubernetes.io/router.middlewares: immuta-https-redirectscheme@kubernetescrdCreate a file named middleware.yaml with the following content.
apiVersion: traefik.containo.us/v1alpha1
kind: Middleware
metadata:
name: https-redirectscheme
spec:
redirectScheme:
scheme: https
permanent: trueApply the Middleware CRD.
kubectl apply -f middleware.yamlPerform a to apply the changes made to immuta-values.yaml.
Refer to the Traefik documentation for further assistance.
Edit immuta-values.yaml to include the following Helm values. Because the Ingress resource will be managed by the OpenShift route you create and not the Immuta Enterprise Helm chart, ingress is set to false below.
gateway:
ingress:
enabled: falseGet the service name for gateway.
oc get service --selector "app.kubernetes.io/component=gateway" --output template='{{ .metadata.name }}'Create a file named route.yaml with the following content. Update all with your own values.
Apply the Route CRD.
Perform a to apply the changes made to immuta-values.yaml.
Refer to the Red Hat OpenShift documentation for further assistance.
443
TCP
Deprecation notice
Kubernetes is ending support for Ingress NGINX. See the official for details.
A cluster that uses one of these supported Databricks Runtimes:
11.3 LTS
14.3
Supported languages
Python
R (not supported for Databricks Runtime 14.3)
Scala (not supported for Databricks Runtime 14.3)
SQL
A Databricks cluster that is one of these supported compute types:
Custom access mode
A Databricks workspace and cluster with the ability to directly make HTTP calls to the Immuta web service. The Immuta web service also must be able to connect to and perform queries on the Databricks cluster, and to call Databricks workspace APIs.
Enable OAuth M2M authentication (recommended) or personal access tokens.
Disable Photon by setting runtime_engine to STANDARD using the Clusters API. Immuta does not support clusters with Photon enabled. Photon is enabled by default on compute running Databricks Runtime 9.1 LTS or newer and must be manually disabled before setting up the integration with Immuta.
Restrict the set of Databricks principals who have CAN MANAGE where the Spark plugin is installed. This is to prevent editing , editing cluster policies, or removing the Spark plugin from the cluster, all of which would cause the Spark plugin to stop working.
If Databricks Unity Catalog is enabled in a Databricks workspace, you must use an Immuta cluster policy when you set up the Databricks Spark integration to create an Immuta-enabled cluster. See the section below for guidance.
If Databricks Unity Catalog is not enabled in your Databricks workspace, you must disable Unity Catalog in your Immuta tenant before proceeding with your configuration of Databricks Spark:
Navigate to the App Settings page and click Integration Settings.
Uncheck the Enable Unity Catalog checkbox.
Click the App Settings icon in Immuta.
Navigate to HDFS > System API Key and click Generate Key.
Click Save and then Confirm. If you do not save and confirm, the system API key will not be saved.
Scroll to the Integration Settings section.
Click + Add Native Integration and select Databricks Spark Integration from the dropdown menu.
Complete the Hostname field.
Enter a Unique ID for the integration. The unique ID is used to name cluster policies clearly, which is important when managing several Databricks Spark integrations. As cluster policies are workspace-scoped, but multiple integrations might be made in one workspace, this ID lets you distinguish between different sets of cluster policies.
Select the identity manager that should be used when mapping the current Spark user to their corresponding identity in Immuta from the Immuta IAM dropdown menu. This should be set to reflect the identity manager you use in Immuta (such as Entra ID or Okta).
Choose an Access Model. The Protected until made available by policy option , whereas the Available until protected by policy option allows it.
Select the Storage Access Type from the dropdown menu.
Opt to add any Additional Hadoop Configuration Files.
Click Add Native Integration, and then click Save and Confirm. This will restart the application and save your Databricks Spark integration. (It is normal for this restart to take some time.)
The Databricks Spark integration will not do anything until your cluster policies are configured, so even though your integration is saved, continue to the next section to configure your cluster policies so the Spark plugin can manage authorization on the Databricks cluster.
Click Configure Cluster Policies.
Select one or more cluster policies in the matrix. Clusters running Immuta with Databricks Runtime 14.3 can only use Python and SQL. You can make changes to the policy by clicking Additional Policy Changes and editing the environment variables in the text field or by downloading it. See the Spark environment variables reference guide for information about each variable and its default value. Some common settings are linked below:
(you can also )
Select your Databricks Runtime.
Use one of the two installation types described below to apply the policies to your cluster:
Automatically push cluster policies: This option allows you to automatically push the cluster policies to the configured Databricks workspace. This will overwrite any cluster policy templates previously applied to this workspace.
Select the Automatically Push Cluster Policies radio button.
Click Close, and then click Save and Confirm.
Apply the cluster policy generated by Immuta to the cluster with the Spark plugin installed by following the .
Give users the Can Attach To permission on the cluster.
Behavior change in Immuta v2025.1 and newer
If a table is registered in Immuta and does not have a subscription policy applied to it, that data will be visible to users in Databricks, even if the Protected until made available by policy setting is enabled.
If you have enabled this setting, author an "Allow individually selected users" that applies to all data sources.
APPLICATION_ADMIN Immuta permission
The Trino user must have the ability to
Create a new file in the Trino etc directory
Create a new Trino user and grant that new user permissions
In Trino, create a new system account user with the privileges listed below. Immuta uses this system account continuously to crawl the connection, maintain state between Immuta and Trino, and run identification.
SELECT on all securables you want registered in Immuta as data sources
In Immuta, click Data and select Connections in the navigation menu.
Click the + Add Connection button.
Select the Trino tile.
Enter the cluster connection information:
Display Name: This is the name of your new connection. This name will be used in the API (connectionKey), in data source names from the host, and on the connections page. Avoid the use of periods (.) or restricted words in your connection name.
Hostname: URL of your Trino cluster.
Port: Port configured for Trino.
Opt to configure an HTTP proxy for this connection by selecting Enable and entering the required details:
Proxy Host: Enter the full proxy URL.
Proxy Port: Enter the proxy port.
Proxy Username: Enter the username for the proxy connection.
Select an authentication method from the dropdown menu and enter the authentication information for the .
Click Next.
Opt to Enable Object Sync, which will keep your connection objects up to date with your Starburst (Trino) environment.
Select the Start Time for when the first object sync job will run each day.
Select the Run Frequency to determine how frequently object sync will run each day.
Opt to Run Object Sync on Create to create all the data objects for your connection. If you do not select this option, you must run object sync manually or wait for the scheduled object sync for your connection's data objects.
Click Save connection.
If you are using Starburst, move on to the next step.
If you are using open-source Trino, you must download the Immuta Trino plugin and add it to your Trino cluster.
The Immuta Trino plugin version matches the version of the corresponding Trino releases. Navigate to the
On the Next Steps page, copy the provided immuta-access-control.properties file. It is pre-populated with the required fields:
access-control.name: Leave this as immuta.
immuta.endpoint: This is your tenant URL. Use the value provided in the file.
Customize any other properties in the file. See the for detailed descriptions of all the properties.
Once your file is customized, add it to your Trino cluster's etc folder.
Enable the Immuta access control plugin in your Trino cluster's config.properties file:
Ensure you have completed all the connection steps, and click Finish.
access-control.config-files=/etc/trino/immuta-access-control.propertiesWhen upgrading to 2026.2, all Snowflake, Databricks Unity Catalog, and Starburst (Trino) integrations will be immediately available to upgrade to connections. This will have some instant API changes and other changes that happen after the upgrade to connections is complete. Please see the tables below for all impacted endpoints.
The following endpoints have been deprecated with connections. Use the recommended endpoint instead.
Learn about the available Trino plugin properties so that you can customize your Trino integration
When you register a connection, there is a provided immuta-access-control.properties file pre-populated with the required properties. You can also add these additional properties to further customize your connection.
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0apiVersion: route.openshift.io/v1
kind: Route
metadata:
name: immuta
spec:
host: <immuta-fqdn>
to:
kind: Service
name: gateway
port:
targetPort: http
tls:
termination: edge
insecureEdgeTerminationPolicy: Redirectoc apply -f route.yamlhelm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0Click Apply Policies.
Manually push cluster policies: Enabling this option allows you to manually push the cluster policies and the init script to the configured Databricks workspace.
Select the Manually Push Cluster Policies radio button.
Click Download Init Script and set the Immuta plugin init script as a cluster-scoped init script in Databricks by following the Databricks documentation.
Click Download Policies, and then workspace.
Ensure that the init_scripts.0.workspace.destination in the policy matches the file path to the init script you configured above.
The Immuta cluster policy references Databricks Secrets for several of the sensitive fields. These secrets must be manually created if the cluster policy is not automatically pushed. Use Databricks API or CLI to push the proper secrets.
SSL Mode: Use the dropdown to select the SSL mode to connect to the host.
Enabled: Use this mode if you have http-server.https.enabled=true set in your Trino cluster's config.properties file.
Disabled: Use this mode for plain, unencrypted connections (e.g., your URL starts with http://).
Certificate Validation: Use the dropdown to select whether to require certificate validation to connect to the host.
Enabled: Use this to ensure Immuta verifies that the server's certificate was issued by a trusted Certificate Authority (CA).
Disabled: Use this setting if you are using a self-signed certificate to skip certificate validation for the connection.
Proxy Password: Enter the password for the proxy connection.
Download the assets for the release that corresponds to your Trino version.
Enable Immuta on your cluster:
Docker installations
Follow Trino's documentation to install the plugin archive on all nodes in your cluster.
Create the Immuta access control configuration file in the Trino configuration directory: /etc/trino/immuta-access-control.properties.
Standalone installations
Follow to install the plugin archive on all nodes in your cluster.
Create the Immuta access control configuration file in the Trino configuration directory: <trino_install_directory>/etc/immuta-access-control.properties.
immuta.apikey: This is how Immuta applies policy to your users' queries. Use the value provided in the file.
immuta.user.admin: This is your Trino system account user. To ensure tables can be properly ingested into Immuta, no Immuta policies will ever apply to this user. Use the value pre-populated in the file to match the username you initially used to create the connection.
Enter the Scope (string). The scope limits the operations allowed in Trino by the access token. See the OAuth 2.0 documentation for details about scopes.
Enter the Client Secret. Immuta uses this secret to authenticate with the authorization server when it requests a token.
Enter the Scope (string). The scope limits the operations allowed in Trino by the access token. See the OAuth 2.0 documentation for details about scopes.
Enter the Certificate Thumbprint. This identifies the corresponding key to the token and is often abbreviated as x5t or is called sub (Subject).
Opt to fill out the Resource field with a URI of the resource where the requested token will be used.
Upload the Private Key, which is used to sign the authorization request.
POST /{technology}/handler
POST /api/v2/data
Step 1: Ensure your system user has been granted access to the relevant object in the data platform.
Step 2: Wait until the next object sync or manually trigger a metadata crawl using with type DATA_OBJECT_SYNC in the payload.
Step 3: If the parent schema has activateNewChildren: false, use
with settings: syncPolicy: true.
Bulk create data sources
POST /{technology}/handler
POST /api/v2/data
Step 1: Ensure your system user has been granted access to the relevant object in the data platform.
Step 2: Wait until the next object sync or manually trigger a metadata crawl using with type DATA_OBJECT_SYNC in the payload.
Step 3: If the parent schema has activateNewChildren: false, use
with settings: syncPolicy: true.
Edit a data source connection
POST /api/v2/data
No substitute. Data sources no longer have their own separate connection details but are tied to the parent connection.
Bulk edit data source's connections
PUT /{technology}/bulk
No substitute. Data sources no longer have their own separate connection details but are tied to the parent connection.
Run schema detection (object sync)
PUT /dataSource/detectRemoteChanges
with type DATA_OBJECT_SYNC in the payload
Delete a data source
DELETE /dataSource/{dataSourceId}
Bulk delete data sources
PUT /dataSource/bulk/{delete}
Enable a single data source
PUT /dataSource/{dataSourceId}
with settings: syncPolicy: true
Bulk enable data sources
PUT /dataSource/bulk/{restore}
with settings: syncPolicy: true
Disable a single data source
PUT /dataSource/{dataSourceId}
with settings: syncPolicy: false
Bulk disable data sources
PUT /dataSource/bulk/{disable}
with settings: syncPolicy: false
Edit a data source name
PUT /dataSource/{dataSourceId}
No substitute. Data source names are automatically generated based on information from your data platform.
Edit a display name
POST /api/v2/data/{connectionKey}
No substitute. Data sources no longer have their own separate connection details but are tied to the parent connection.
Override a host name
PUT /dataSource/{dataSourceId}/overrideHost
No substitute. Data sources no longer have their own separate connection details but are tied to the parent connection.
Create an integration/connection
POST /integrations
Update an integration/connection
PUT /integrations/{integrationId}
Delete an integration/connection
DELETE /integrations/{integrationId}
Delete and update data source columns
DELETE /dictionary/{dataSourceId}
No substitute. Data source columns are automatically generated based on information from your data platform.
Update a data source owner
PUT /dataSource/{dataSourceId}/access/{id}
with settings: owners
Response to a data source owner request
POST /subscription/deny
with settings: owners
If you have any automated actions using the following APIs, ensure you do the required change after the upgrade to ensure they continue working as expected.
Search for a data source
Data source names will change with the upgrade. Update {dataSourceName} in the request with the new data source name.
Data source names will change with the upgrade. Update the searchText in the payload with the new data source name.
Search schema names
Create a single data source
392 and newer
Required
This property enables the integration.
access-control.config-files
392 and newer
Optional
Trino allows you to enable multiple system access control providers at the same time. To do so, add providers to this property as comma-separated values. This approach allows Immuta to work with existing Trino installations that have already configured an access control provider. Immuta does not manage all permissions in Trino and will default to allowing access to anything Immuta does not manage so that the Starburst (Trino) integration complements existing controls. For example, if the Starburst (Trino) integration is configured to allow users write access to tables that are not protected by Immuta, you can still lock down write access for specific non-Immuta tables using an additional access control provider.
immuta.allowed.immuta.datasource.operations
413 and newer
Optional
This property defines a comma-separated list of allowed operations for Starburst (Trino) users on tables registered as Immuta data sources: READ,WRITE, and OWN. (See the for details about the OWN operation.) When set to WRITE, all querying users are allowed read and write operations to data source schemas and tables. By default, this property is set to READ, which blocks write operations on data source tables and schemas. If are enabled for your Immuta tenant, this property is set to READ,WRITE by default, so users are allowed read and write operations to data source schemas and tables.
immuta.allowed.non.immuta.datasource.operations
392 and newer
Optional
This property defines a comma-separated list of allowed operations users will have on tables not registered as Immuta data sources: READ, WRITE, CREATE, and OWN. (See the for details about CREATE and OWN operations.) When set to READ, users are allowed read operations on tables not registered as Immuta data sources. When set to WRITE, users are allowed read and write operations on tables not registered as Immuta data sources. If this property is left empty, users will not get access to any tables outside Immuta. By default, this property is set to READ,WRITE. If are enabled for your Immuta tenant, this property is set to
immuta.apikey
392 and newer
Required
This should be set to the Immuta API key displayed when . To rotate this API key, to generate a new API key, and then replace the existing immuta.apikey value with the new one.
immuta.audit.legacy.enabled
435 and newer
Optional
This property allows you to turn off Starburst (Trino) audit. Must set both immuta.audit.legacy.enabled and immuta.audit.uam.enabled to false to fully disable query audit.
immuta.audit.uam.enabled
435 and newer
Optional
This property allows you to turn off Starburst (Trino) audit. Must set both immuta.audit.legacy.enabled and immuta.audit.uam.enabled to false to fully disable query audit.
immuta.ca-file
392 and newer
Optional
This property allows you to specify a path to your CA file.
immuta.cache.views.seconds
392 and newer
Optional
Amount of time in seconds for which a user's specific representation of an Immuta data source will be cached for. Changing this will impact how quickly policy changes are reflected for users actively querying Trino. By default, cache expires after 30 seconds.
immuta.cache.datasources.seconds
392 and newer
Optional
Amount of time in seconds for which a user's available Immuta data sources will be cached for. Changing this will impact how quickly data sources will be available due to changing projects or subscriptions. By default, cache expires after 30 seconds.
immuta.endpoint
392 and newer
Required
The protocol and fully qualified domain name (FQDN) for the Immuta tenant used by Trino (for example, https://my.immuta.tenant.io). This should be set to the endpoint displayed when .
immuta.filter.unallowed.table.metadata
392 and newer
Optional
When set to false, Immuta won't filter unallowed table metadata, which helps ensure Immuta remains noninvasive and performant. If this property is set to true, running show catalogs, for example, will reflect what that user has access to instead of returning all catalogs. By default, this property is set to false.
immuta.http.timeout.milliseconds
464 and newer
Optional
The timeout for all HTTP calls made to Immuta in milliseconds. Defaults to 30000 (30 seconds).
immuta.user.admin
392 and newer
Required
This property identifies the Trino user who is an Immuta administrator (for example, immuta.user.admin=immuta_system_account). This user will not have Immuta policies applied to them because this account will run the subqueries. This should be the Starburst user provided when registering the connection. Note that you must escape regex special characters (for example, john\\.doe+svcacct@immuta\\.com).
The example configuration snippet below uses the default configuration settings for immuta.allowed.immuta.datasource.operations and immuta.allowed.non.immuta.datasource.operations, which allow read access for data registered as Immuta data sources and read and write access on data that is not registered in Immuta. See the Granting Starburst (Trino) privileges section for details about customizing and enforcing read and write access controls in Starburst.
Starburst does not support using Starburst built-in access control (BIAC) concurrently with any other access control providers such as Immuta. If Starburst BIAC is in use, it must be disabled to allow Immuta to enforce policies on cluster.
access-control.name
# Enable the Immuta System Access Control implementation.
access-control.name=immuta
# The Immuta endpoint that was displayed when registering the Trino connection in Immuta.
immuta.endpoint=http://service.immuta.com:3000
# The Immuta API key that was displayed when registering the Trino in Immuta.
immuta.apikey=45jdljfkoe82b13eccfb9c
# The administrator user regex. Trino usernames matching this regex will not be subject to
# Immuta policies. This regex should match the user name provided at Immuta data source
# registration.
immuta.user.admin=immuta_system_account
# Optional argument (default is shown).
# A CSV list of operations allowed on schemas/tables registered as Immuta data sources.
immuta.allowed.immuta.datasource.operations=READ
# Optional argument (default is shown).
# A CSV list of operations allowed on schemas/tables not registered as Immuta data sources.
# Set to empty to allow no operations on non-Immuta data sources.
immuta.allowed.non.immuta.datasource.operations=READ,WRITE
# Optional argument (default is shown).
# Controls table metadata filtering for inaccessible tables.
# - When this property is enabled and non-Immuta reads are also enabled, a user performing
# 'show catalogs/schemas/tables' will not see metadata for a table that is registered as
# an Immuta data source but the user does not have access to through Immuta.
# - When this property is enabled and non-Immuta reads and writes are disabled, a user
# performing 'show catalogs/schemas/tables' will only see metadata for tables that the
# user has access to through Immuta.
# - When this property is disabled, a user performing 'show catalogs/schemas/tables' can see
# all metadata.
immuta.filter.unallowed.table.metadata=falseRegister your Databricks Unity Catalog data
Immuta user with the APPLICATION_ADMIN Immuta permission
Databricks service principal with the following privileges. For instructions on setting up this user, see the Creating the Databricks service principal section:
USE CATALOG and MANAGE on all catalogs containing securables you want registered as Immuta data sources.
USE SCHEMA on all schemas containing securables you want registered as Immuta data sources.
MODIFY and SELECT on all securables you want registered as Immuta data sources.
Workspace admin on the workspace configured as the host for the integration.
Additional privileges are required for query audit:
USE CATALOG on the system catalog
USE SCHEMA on the system.access and system.query
Databricks user to run the script to register the connection with the following privileges:
Metastore admin and account admin
CREATE CATALOG privilege on the Unity Catalog metastore to create an Immuta-owned catalog and tables
See the for more details about Unity Catalog privileges and securable objects.
Unity Catalog and attached to a Databricks workspace.
Unity Catalog enabled on your Databricks cluster or SQL warehouse. All SQL warehouses have Unity Catalog enabled if your workspace is attached to a Unity Catalog metastore. Immuta recommends linking a SQL warehouse to your Immuta tenant rather than a cluster for both performance and availability reasons.
Click Data and select the Connections tab in the navigation menu.
Click the + Add Connection button.
Select the Databricks data platform tile.
Enter the connection information:
Click Next.
Configure the Policy setting:
Opt to by adding them to the Exclude Group Pattern. This field cannot be changed after the connection is created.
Click Next
Requirements:
A configured Databricks Unity Catalog connection
Fewer than 10,000 Databricks Unity Catalog data sources registered in Immuta
The following permissions must be added to your Immuta service principal:
USE CATALOG
To allow Immuta to automatically import table and column tags from Databricks Unity Catalog, enable Databricks Unity Catalog tag ingestion in the external catalog section of the Immuta app settings page.
Navigate to the App Settings page.
Scroll to 2 External Catalogs, and click Add Catalog.
Enter a Display Name and select Databricks Unity Catalog from the dropdown menu.
Click
If you need instruction for setting up your Databricks service principal before registering your connection, see the steps below.
In Databricks, with the privileges listed below. Immuta uses this service principal continuously to orchestrate Unity Catalog policies and maintain state between Immuta and Databricks.
USE CATALOG and MANAGE on all catalogs containing securables you want registered as Immuta data sources.
USE SCHEMA on all schemas containing securables you want registered as Immuta data sources.
MODIFY and SELECT
See the for more details about Unity Catalog privileges and securable objects.
. For Databricks Unity Catalog audit to work, Immuta must have, at minimum, the following access.
USE CATALOG on the system catalog
USE SCHEMA on the system.access and system.query schemas
Learn how Immuta enforces policies on data in your Databricks Unity Catalog environment
In the Databricks Unity Catalog integration, Immuta administers Databricks Unity Catalog privileges on data registered in Immuta. Then, Immuta users who have been granted access to the data sources can query them.
The sequence diagram below outlines the events that occur when an Immuta user who is subscribed to a data source queries it in Databricks Unity Catalog.
The Databricks Unity Catalog integration is configured and data is registered through connections, an Immuta feature that allows administrators to register data objects in a technology through a single connection to make data registration more scalable for your organization.
Once the Databricks Unity Catalog connection is registered, you can author subscription and data policies in Immuta to enforce access controls.
See the Databricks Unity Catalog integration reference guide for more details about registering a connection.
When a subscription policy is applied to a data source, users who meet the conditions of the policy will be automatically subscribed to the data source. Immuta creates and manages Databricks Unity Catalog groups for those users (if an appropriate group does not already exist), grants the required Unity Catalog privileges to the group, and adds the entitled users to that group.
Consider the following example that illustrates how Immuta enforces a subscription policy that only allows users in the analysts group to access the yellow-table. When this policy is authored and applied to the data source, Immuta creates an Immuta-managed Databricks group (if needed), grants the SELECT privilege on yellow-table to that group, and adds users who are members of the analysts group to it.
In the image above, the user in the analysts group accesses yellow-table, while the user who is a part of the research group is denied access.
On securable objects
If you enable a Databricks Unity Catalog object in Immuta, Immuta will only manage users' access to that data object after a subscription policy grants them access to the data source. Immuta preserves all preexisting grants in Databricks and only revokes user access when explicitly dictated by an Immuta policy.
Expand the collapsible blocks below to see how Immuta-managed grants and Databricks-managed grants are affected in various scenarios.
If a user is not registered in Immuta, Immuta will have no effect on that user's access to data in Unity Catalog.
On schemas and catalogs
By default, Immuta will revoke Immuta users' USE CATALOG and USE SCHEMA privileges in Unity Catalog for users that do not have access to any of the underlying securables within that catalog/schema. If users have any Immuta-managed or Databricks-managed grants to a securable, Immuta will not revoke that catalog/schema access.
If you disable this setting, Immuta will only revoke the permissions granted on the securable objects themselves, and users' USE CATALOG and USE SCHEMA permissions will remain even if the user does not have access to any resource in that catalog/schema.
See the on changing this setting.
After Databricks Unity Catalog objects are registered in Immuta, you can author data policies in Immuta to enforce fine-grained access controls.
When a data policy is applied to a Databricks Unity Catalog data source, Immuta enforces that policy natively in Databricks. Depending on the policy type, Immuta applies SQL user-defined functions (UDFs) to enforce row-level security and column masking on registered tables so that queries return policy-enforced results.
As data policies are created, updated, or removed in Immuta, Immuta updates the corresponding SQL UDFs in Databricks to keep enforcement in sync. Users continue querying the Databricks Unity Catalog object directly and see policy-enforced data in Databricks.
See the for guidance on authoring data policies in Immuta and the for the Databricks Unity Catalog integration.
This is a guide on how to deploy Immuta on Kubernetes in the following managed public cloud providers:
Amazon Web Services (AWS)
Microsoft Azure
Google Cloud Platform (GCP)
The following managed services must be provisioned and running before proceeding. For further assistance consult the for your respective cloud provider.
POST /api/v2/dataPUT /{technology}/handler/{handlerId}
DELETE /api/v2/data/{connectionKey}DELETE /{technology}/handler/{handlerId}
DELETE /dataSource/{dataSourceId}
POST /dictionary/{dataSourceId}PUT /dictionary/{dataSourceId}
DELETE /dataSource/{dataSourceId}/unsubscribePOST /subscription/deny/bulkThis endpoint will not search the schemas of connection data sources. Instead use the GET /api/connections/{connectionKey}/dataObjects/{id} and search for the schema data object.
READ,WRITE,OWN,CREATESELECT on the following system tables:
system.access.table_lineage
system.access.column_lineage
system.access.audit
system.query.history
Add the Databricks service principal to the databricks_pii_access group
Display Name: The display name represents the unique name of your connection and will be used as prefix in the name for all data objects associated with this connection. It will also appear as the display name in the UI and will be used in all API calls made to update or delete the connection. Avoid the use of periods (.) or restricted words in your connection name.
Host: The hostname of your Databricks workspace.
Port: Your Databricks port.
HTTP Path: The HTTP path of your Databricks cluster or SQL warehouse.
Immuta Catalog: The name of the catalog Immuta will create to store internal entitlements and other user data specific to Immuta. This catalog will only be readable for the Immuta service principal and should not be granted to other users. The catalog name may only contain letters, numbers, and underscores and cannot start with a number.
Opt to configure an HTTP proxy for this connection by selecting Enable and entering the required details:
Proxy Host: Enter the full proxy URL.
Proxy Port: Enter the proxy port.
Select if the proxy requires authentication:
Select your authentication method from the dropdown menu and enter the authentication information for the Immuta service principal that you created.
Configure the Audit settings:
Opt to Enable Audit.
If audit is enabled, opt to enter Workspace IDs to filter the audit ingest to just specific workspaces.
Click Next.
Opt to Enable Object Sync, which will keep your connection objects up to date with your Databricks Unity Catalog environment.
Select the Start Time for when the first object sync job will run each day.
Select the Run Frequency to determine how frequently object sync will run each day.
Opt to Run Object Sync on Create to create all the data objects for your connection. If you do not select this option, you must run object sync manually or wait for the scheduled object sync for your connection's data objects.
Click Save connection.
Copy the provided script and run it in Databricks Unity Catalog as a user with the privileges listed in the requirements section.
Click Validate Connection.
If the connection is successful, click Finish. If there are any errors, check the connection details and credentials to ensure they are correct and try again.
systemUSE SCHEMA on the system.access schema
SELECT on the following system table:
system.access.audit
If ingesting and applying tags to foreign catalogs (created via Lakehouse Federation), the following additional permissions are required:
USE SCHEMA on the system.information_schema schema
SELECT on the following system tables:
system.information_schema.column_tags
system.information_schema.table_tags
system.information_schema.tables
MODIFYMODIFYWorkspace admin permissions (If your service principal is a regular user in Databricks and not an actual service principal in Databricks, follow the guidance for managing users in Databricks documentation to grant this user the workspace admin permission.)
SELECTsystem.access.table_lineage
system.access.column_lineage
system.access.audit
system.query.history
Access to system tables is governed by Unity Catalog. No user has access to these system schemas by default. To grant access, a user that is both a metastore admin and an account admin must grant USE_SCHEMA and SELECT privileges on the system schemas to the service principal. See Manage privileges in Unity Catalog.
Create a separate Immuta catalog for each Immuta tenant
If multiple Immuta tenants are connected to your Databricks environment, create a separate Immuta catalog for each of those tenants. Having multiple Immuta tenants use the same Immuta catalog causes failures in policy enforcement.
(Optional) Amazon OpenSearch
This checklist outlines the necessary prerequisites for successfully deploying Immuta.
Create a Kubernetes namespace named immuta.
kubectl create namespace immutaSwitch to namespace immuta. All subsequent kubectl commands will default to this namespace.
kubectl config set-context --current --namespace=immutaCreate a container registry pull secret. Your credentials to authenticate with ocir.immuta.com are provided by Immuta; there is currently no self-service lookup — contact your Immuta representative or Immuta Support if you do not have them.
Connect to the database as an admin (e.g., postgres) by creating an ephemeral container inside the Kubernetes cluster. A shell prompt will not be displayed after executing the kubectl run command outlined below. Wait 5 seconds, and then proceed by entering a password.
Create the immuta role.
CREATE ROLE immuta with LOGIN ENCRYPTED PASSWORD '<postgres-password>';
ALTER ROLE immuta SET search_path TO bometadata,public;Grant administrator privileges to the immuta role, where <admin-role> is rds_superuser (Amazon RDS), azure_pg_admin (Azure Database), or cloudsqlsuperuser (Google Cloud SQL). Upon successfully completing this installation guide, you can optionally revoke this role grant.
GRANT <admin-role> TO immuta;Grant the immuta role to the current user. Upon successfully completing this installation guide, you can optionally revoke this role grant.
Create databases.
CREATE DATABASE immuta OWNER immuta;
CREATE DATABASE temporal OWNER immuta;
CREATE DATABASE temporal_visibility OWNER immuta;Grant role immuta additional privileges. Refer to the PostgreSQL documentation for further details on database roles and privileges.
GRANT ALL ON DATABASE immuta TO immuta;
GRANT ALL ON DATABASE temporal TO immuta;
GRANT ALL ON DATABASE temporal_visibility TO immuta;Configure the immuta database.
\c immuta
CREATE EXTENSION pgcrypto;Configure the temporal database.
Configure the temporal_visibility database.
Exit the interactive prompt. Type \q, and then press Enter.
This section demonstrates how to deploy Immuta using the Immuta Enterprise Helm chart once the prerequisite cloud-managed services are configured.
global:
imageRegistry: ocir.immuta.com
imagePullSecrets:
- name: immuta-oci-registry
postgresql:
host: <postgres-fqdn>
port: 5432
username: immuta
password: <postgres-password>
audit:
config:
elasticsearchEndpoint: <elasticsearch-endpoint>
searchAuthenticationType: <'UsernamePassword' or 'AWS'>
# If you use OpenSearch and authenticate with username and password, uncomment the lines below by deleting the hash symbols
#elasticsearchUsername: <elasticsearch-username>
#elasticsearchPassword: <elasticsearch-password>
# If you use OpenSearch and authenticate with AWS role, uncomment the lines below by deleting the hash symbols. When using AWS role authentication, elasticsearchUsername (above) must be set to ''.
#searchAwsRegion: '<deployment-OS-region>'
# If Immuta is deployed in an AWS account that is different than OpenSearch, then you must configure a trust relationship between the Immuta role and an OpenSearch role
#searchAwsRoleArn: '<assumed-role-arn>'
postgresql:
database: immuta
#init:
#extraEnvVars:
# Audit retention defaults to 7 days. To change the retention period, uncomment the lines below by deleting the hash symbols and update the value
#- name: AUDIT_RETENTION_POLICY_IN_DAYS
#value: 90
onboarding:
postgresql:
database: immuta
secure:
postgresql:
database: immuta
ssl: true
temporal:
enabled: true
schema:
createDatabase:
enabled: false
server:
config:
persistence:
default:
sql:
database: temporal
tls:
enabled: true
visibility:
sql:
database: temporal_visibility
tls:
enabled: trueglobal:
imageRegistry: ocir.immuta.com
imagePullSecrets:
- name: immuta-oci-registry
postgresql:
host: <postgres-fqdn>
port: 5432
username: immuta
password: <postgres-password>
audit:
enabled: false
onboarding:
postgresql:
database: immuta
secure:
postgresql:
database: immuta
ssl: true
extraEnvVars:
- name: FeatureFlag_AuditService
value: false
temporal:
enabled: true
schema:
createDatabase:
enabled: false
server:
config:
persistence:
default:
sql:
database: temporal
tls:
enabled: true
visibility:
sql:
database: temporal_visibility
tls:
enabled: trueCreate a file named immuta-values.yaml with the above content, making sure to update all placeholder values.
Deploy Immuta.
helm install immuta oci://ocir.immuta.com/stable/immuta-enterprise \
--values immuta-values.yaml \
--version 2026.2.0Wait for all pods to become ready.
kubectl wait --for=condition=Ready pods --allDetermine the name of the gateway service.
kubectl get service --selector "app.kubernetes.io/component=gateway" --output nameListen on local port 8080, forwarding TCP traffic to the gateway service's port named http.
kubectl port-forward <service-name> 8080:httpIn a web browser, navigate to localhost:8080, to ensure the Immuta application loads.
Press Control+C to stop port forwarding.
(required).
.
.
(required).
.
.
Feature availability
If deployed without ElasticSearch/OpenSearch, several core services and features will be unavailable. See the deployment requirements for details.
echo <token> | helm registry login --password-stdin --username <username> ocir.immuta.comkubectl create secret docker-registry immuta-oci-registry \
--docker-server=https://ocir.immuta.com \
--docker-username="<username>" \
--docker-password="<token>" \
--docker-email=support@immuta.comkubectl run pgclient \
--stdin \
--tty \
--rm \
--image docker.io/bitnami/postgresql -- \
psql --host <postgres-fqdn> --username <postgres-admin> --dbname postgres --port 5432 --passwordFeature availability
If deployed without Elasticsearch/OpenSearch, several core services and features will be unavailable. See the for details.
Avoid these special characters in generated passwords
whitespace, $, &, :, \, /, ', "

Azure Database: azure_pg_admin
Google Cloud SQL: cloudsqlsuperuser
GRANT immuta TO CURRENT_USER;\c temporal
GRANT CREATE ON SCHEMA public TO immuta;\c temporal_visibility
GRANT CREATE ON SCHEMA public TO immuta;
CREATE EXTENSION btree_gin;Disabled
Enabled:
Proxy Username: Enter the username for the proxy connection.
Proxy Password: Enter the password for the proxy connection.
system.information_schema.columnsWithin Immuta, fill out the Authority URL with the full URL of the identity provider. This is where the generated token is sent. The default value is https://<your workspace name>.azuredatabricks.net/oidc/v1/token.
Enter the Scope (string). The scope limits the operations and roles allowed in Databricks by the access token. See the for details about scopes.
Enter the Client Secret you created above. Immuta uses this secret to authenticate with the authorization server when it requests a token.
SELECT grant coexists with their Databricks-managed SELECT grant.User D is revoked access to the table by the change to the Immuta policy. The Immuta-managed SELECT grant (from the previous policy) and the pre-existing Databricks-managed SELECT grant have been revoked because the Immuta policy explicitly dictated that their access should be removed.
User D is granted access to the table by Databricks. The Immuta-managed grant is revoked and the Databricks grant remains when the data source is disabled because the state of the grants on this data object reverts to what it was before the data object was registered in Immuta.
User A
- HR group
SELECT
None
✅
User B
- Engineering group
None
SELECT
✅
User C
None
User A
- HR group
Revoked
None
❌
User A
- HR group
None
None
❌
User B
- Engineering group
None
SELECT
✅
User C
None
User A
- HR group
None
None
❌
User B
- Engineering group
None
SELECT
✅
User C
None
None
❌
User D
- HR group
SELECT
SELECT
✅
User B
- Engineering group
SELECT
SELECT
✅
User C
None
None
❌
User D
- HR group
Revoked
Revoked
❌
None
❌
User D
- HR group
None
None
❌
None
❌
User D
- HR group
None
SELECT
✅
Learn how to adjust settings for the Databricks Spark integration
You can customize the Databricks Spark integration settings using these components Immuta provides:
Immuta provides cluster policies that set the Spark environment variables and configuration on your Databricks cluster once you apply that policy to your cluster. These policies generated by Immuta must be applied to your cluster manually. The includes instructions for generating and applying these cluster policies. Each cluster policy is described below.
The lists the various possible settings controlled by these variables that you can set in your cluster policy before attaching it to your cluster.
In some cases it is necessary to add sensitive configuration to SparkSession.sparkContext.hadoopConfiguration to allow Spark to read data.
For example, when accessing external tables stored in Azure Data Lake Gen2, Spark must have credentials to access the target containers or filesystems in Azure Data Lake Gen2, but users must not have access to those credentials. In this case, an additional configuration file may be provided with a storage account key that the cluster may use to access Azure Data Lake Gen2.
To use an additional Hadoop configuration file, set the to be the full URI to this file.
Databricks non-privileged users will only see sources to which they are subscribed in Immuta, and this can present problems if organizations have a data lake full of non-sensitive data and Immuta removes access to all of it. Immuta addresses this challenge by allowing Immuta users to access any tables that are not protected by Immuta (i.e., not registered as a data source or a table in a native workspace). Although this is similar to how privileged users in Databricks operate, non-privileged users cannot bypass Immuta controls.
Protected until made available by policy: This setting means that users can only see tables that Immuta has explicitly subscribed them to.
Available until protected by policy: This setting means all tables are open until explicitly registered and protected by Immuta. This setting allows both non-Immuta reads and non-Immuta writes:
: Immuta users with regular (non-privileged) Databricks roles may SELECT from tables that are not registered in Immuta. This setting does not allow reading data directly with commands like spark.read.format("x"). Users are still required to read data and query tables using Spark SQL. When non-Immuta reads are enabled through the cluster policy, Immuta users will see all databases and tables when they run show databases or show tables. However, this does not mean they will be able to query all of them.
The includes instructions for applying these settings to your cluster.
In Immuta, a Databricks data source is considered ephemeral, meaning that the compute resources associated with that data source will not always be available.
Ephemeral data sources allow the use of ephemeral overrides, user-specific connection parameter overrides that are applied to Immuta metadata operations.
When a user runs a Spark job in Databricks, the Immuta plugin automatically submits ephemeral overrides for that user to Immuta for all applicable data sources to use the current cluster as compute for all subsequent metadata operations for that user against the applicable data sources.
For more details about ephemeral overrides and how to configure or disable them, see the .
Immuta projects combine users and data sources under a common purpose. Sometimes this purpose is for a single user to organize their data sources or to control an entire schema of data sources through a single projects screen; however, most often this is an Immuta purpose for which the data has been approved to be used and will restrict access to data and streamline team collaboration. Consequently, data owners can restrict access to data for a specified purpose through projects.
When a user is working within the context of a project, data users will only see the data in that project. This helps to prevent data leaks when users collaborate. Users can switch project contexts to access various data sources while acting under the appropriate purpose. Consider adjusting the following project settings to suit your organization's needs:
Project UDFs (web service and on-cluster caches): Immuta caches a mapping of user accounts and users' current projects in the Immuta Web Service and on-cluster. When users change their project with UDFs instead of the Immuta UI, Immuta invalidates all the caches on-cluster (so that everything changes immediately) and the cluster submits a request to change the project context to a web worker. Immediately after that request, another call is made to a web worker to refresh the current project. To allow use of project UDFs in Spark jobs, . Otherwise, caching could cause dissonance among the requests and calls to multiple web workers when users try to change their project contexts.
Preventing users from changing projects within a session: If your compliance requirements restrict users from changing projects within a session, you can block the use of Immuta's project UDFs on a Databricks Spark cluster. To do so, .
This section describes how Immuta interacts with common Databricks features.
Databricks users can see the Databricks change data feed (CDF) on queried tables if they are allowed to read raw data and meet specific qualifications. Immuta does not support applying policies to the changed data, and the CDF cannot be read for data source tables if the user does not have access to the raw data in Databricks or for .
The CDF can be read if the querying user is allowed to read the raw data and ONE of the following statements is true:
the table is in the current workspace
the table is in a scratch path
non-Immuta reads are enabled AND the table does not intersect with a workspace under which the current user is not acting
non-Immuta reads are enabled AND the table is not part of an Immuta data source
The trusted libraries feature allows Databricks cluster administrators to avoid Immuta Security Manager errors when using third-party libraries. An administrator can specify an installed library as trusted, which will enable that library's code to bypass the Immuta security manager. This feature does not impact Immuta's ability to apply policies; trusting a library only allows code through that otherwise would have been blocked by the Security Manager.
The following types of libraries are supported when installing a third-party library using the Databricks UI or the Databricks Libraries API:
Library source is Upload, DBFS or DBFS/S3 and the Library Type is Jar.
Library source is Maven
When users install third-party libraries, those libraries will be denied access to sensitive resources by default. However, cluster administrators can specify which of the installed Databricks libraries should be trusted by Immuta. See the to add a trusted library to your configuration.
Limitations
Installing trusted libraries outside of the Databricks Libraries API (e.g., ADD JAR ...) is not supported.
Databricks installs libraries right after a cluster has started, but there is no guarantee that library installation will complete before a user's code is executed. If a user executes code before a trusted library installation has completed, Immuta will not be able to identify the library as trusted. This can be solved by either
waiting for library installation to complete before running any third-party library commands or
Connect any of these to work with your Databricks Spark integration so data owners can tag their data.
Immuta supports the use of external metastores in :
Local mode: The metastore client running inside a cluster connects to the underlying metastore database directly via JDBC.
Remote mode: Instead of connecting to the underlying database directly, the metastore client connects to a separate metastore service via the Thrift protocol. The metastore service connects to the underlying database. When running a metastore in remote mode, DBFS is not supported.
For more details about these deployment modes, see .
Users on Databricks Runtimes 8+ can manage notebook-scoped libraries with .
However, this functionality differs from the , and Python libraries are not supported as trusted libraries. The Immuta Security Manager will deny the code of libraries installed with %pip access to sensitive resources.
Scratch paths are cluster-specific remote file paths that Databricks users are allowed to directly read from and write to without restriction. The creator of a Databricks cluster specifies the set of remote file paths that are designated as scratch paths on that cluster when they configure a Databricks cluster. Scratch paths are useful for scenarios where non-sensitive data needs to be written out to a specific location using a Databricks cluster protected by Immuta.
To configure a scratch path, use the .
Learn about what Immuta creates in your Databricks environment to enforce access controls
In the Databricks Spark integration, Immuta installs an Immuta-maintained Spark plugin on your Databricks cluster. When a user queries data that has been registered in Immuta as a data source, the plugin injects policy logic into the plan Spark builds so that the results returned to the user only include data that specific user should see.
The sequence diagram below breaks down this process of events when an Immuta user queries data in Databricks.
A Databricks workspace with the Premium tier, which includes cluster policies (required to configure the Spark integration)
A cluster that uses one of these supported Databricks Runtimes:
11.3 LTS
14.3
Supported languages
Python
R (not supported for Databricks Runtime 14.3)
Scala (not supported for Databricks Runtime 14.3)
A Databricks cluster that is one of these supported compute types:
Custom access mode
A Databricks workspace and cluster with the ability to directly make HTTP calls to the Immuta web service. The Immuta web service also must be able to connect to and perform queries on the Databricks cluster, and to call .
The Databricks Spark integration only works with Spark 3.
When an administrator configures the Databricks Spark integration, Immuta generates a cluster policy that the administrator then applies to the Databricks cluster. When the cluster starts after the cluster policy has been applied, the Databricks cluster that Immuta provides downloads Spark plugin artifacts onto the cluster that has the init script and puts the artifacts in the appropriate locations on local disk for use by Spark.
Once the init script runs, the Spark application running on the Databricks cluster will have the appropriate artifacts on its CLASSPATH to use Immuta for authorization and policy enforcement.
Immuta adds the following artifacts to your Databricks environment:
Once the Immuta-enabled cluster is running, the following user actions spur various processes. The list below provides an overview of each process:
: When a data owner registers a Databricks securable as a data source, data source metadata (column type, securable name, column names, etc.) is retrieved from the Metastore and stored in the Immuta Metadata Database. If tags are then applied to the data source, Immuta stores this metadata in the Metadata Database as well.
Data source is deleted: When a data source is deleted, the data source metadata is deleted from the Metadata Database. Depending on the settings configured for the integration, users will either be able to query that data now that it is no longer registered in Immuta, or access to the securable will be revoked for all users. See the for details about this setting.
: Information about the policy and the columns or securables it applies to is stored in the Metadata Database. When a user queries the data in Databricks, the Spark plugin retrieves the policy information, the user metadata, and the data source metadata from the Metadata Database and injects this information as policy logic into the Spark logical plan. Immuta caches policy information and data source definitions in memory on the Spark application to reduce calls to the Metadata Database and boost performance.
The image below illustrates these processes and how they interact.
The Databricks Spark integration allows users to author subscription and data policies to enforce access controls. See the corresponding pages for details about specific types of policies supported:
Immuta supports clusters on Databricks Runtime 14.3. The integration for this Databricks Runtime differs from the integration for other supported Runtimes in the following ways:
: The Security Manager is disabled for Databricks Runtime 14.3. Because the Security Manager is used to prevent users from circumventing access controls when using R and Scala, those languages are unsupported. Only Python and SQL clusters are supported.
Py4J security and process isolation automatically enabled: Immuta relies on Databricks process isolation and Py4J security to prevent user code from performing unauthorized actions. After selecting Runtime 14.3 during configuration, Immuta will automatically enable process isolation and Py4J security.
dbutils is unsupported: Immuta relies on Databricks process isolation and Py4J security to prevent user code from performing unauthorized actions. This means that dbutils is not supported for Databricks Spark integrations using Databricks Runtime 14.3 LTS.
The table below compares the features supported for clusters on Databricks Runtime 11.3 and Databricks Runtime 14.3.
The Databricks Spark integration supports the following authentication methods to configure the integration:
OAuth machine-to-machine (M2M): Immuta uses the to integrate with , which allows Immuta to authenticate with Databricks using a client secret. Once Databricks verifies the Immuta service principal’s identity using the client secret, Immuta is granted a temporary OAuth token to perform token-based authentication in subsequent requests. When that token expires (after one hour), Immuta requests a new temporary token. See the for more details.
Personal access token (PAT): This token gives Immuta temporary permission to push the cluster policies to the configured Databricks workspace and overwrite any cluster policy templates previously applied to the workspace when configuring the integration or to register securables as Immuta data sources.
Immuta captures the code or query that triggers the Spark plan in Databricks, making audit records more useful in assessing what users are doing. To audit what triggers the Spark plan, Immuta hooks into Databricks where notebook cells and JDBC queries execute and saves the cell or query text. Then, Immuta pulls this information into the audits of the resulting Spark jobs.
Immuta supports auditing all queries run on a Databricks cluster, regardless of whether users touch Immuta-protected data or not. To configure Immuta to do so, set the in the Spark cluster configuration when configuring your integration.
See the for more details about the audit capabilities in the Databricks Spark integration.
Non-administrator users on an Immuta-enabled Databricks cluster must not have access to view or modify Immuta configuration or the immuta-spark-hive.jar file, as this poses a security loophole around Immuta policy enforcement. allow you to securely apply environment variables to Immuta-enabled clusters.
Databricks secrets can be used in the environment variables configuration section for a cluster by referencing the secret path instead of the actual value of the environment variable. For example, if a user wanted to make the MY_SECRET_ENV_VAR=abcd_1234 value secret, they could instead create a Databricks secret and reference it as the value of that variable by following these steps:
Create the secret scope my_secrets and add a secret with the key my_secret_env_var containing the sensitive environment variable.
Reference the secret in the environment variables section as MY_SECRET_ENV_VAR={{secrets/my_secrets/my_secret_env_var}}.
At runtime, {{secrets/my_secrets/my_secret_env_var}} would be replaced with the actual value of the secret if the owner of the cluster has access to that secret.
There are limitations to isolation among users in Scala jobs on a Databricks cluster, even when using Immuta’s Security Manager. When data is broadcast, cached (spilled to disk), or otherwise saved to SPARK_LOCAL_DIR, it's impossible to distinguish between which user’s data is composed in each file/block. If you are concerned about this vulnerability, Immuta suggests that you
limit Scala clusters to Scala jobs only and
require equalized projects, which will force all users to act under the same set of attributes, groups, and purposes with respect to their data access. To require that Scala clusters be used in equalized projects and avoid the risk described above, set the to true.
Once this configuration is complete, users on the cluster will need to switch to an Immuta equalized project before running a job. Once the first job is run using that equalized project, all subsequent jobs, no matter the user, must also be run under that same equalized project. If you need to change a cluster's project, you must restart the cluster.
When data is read in Spark using an Immuta policy-enforced plan, the masking and redaction of rows is performed at the leaf level of the physical Spark plan, so a policy such as "Mask using hashing the column social_security_number for everyone" would be implemented as an expression on a project node right above the FileSourceScanExec/LeafExec node at the bottom of the plan. This process prevents raw data from being shuffled in a Spark application and, consequently, from ending up in SPARK_LOCAL_DIR.
This policy implementation coupled with an equalized project guarantees that data being dropped into SPARK_LOCAL_DIR will have policies enforced and that those policies will be homogeneous for all users on the cluster. Since each user will have access to the same data, if they attempt to manually access other users' cached data, they will only see what they have access to via equalized permissions on the cluster. If project equalization is not turned on, users could dig through that directory and find data from another user with heightened access, which would result in a data leak.
The has guidance for resolving issues with your installation.
The Google BigQuery integration allows users to query policy protected data directly in BigQuery as secure views within an Immuta-created dataset. Immuta controls who can see what within the views, allowing data governors to create complex ABAC policies and data users to query the right data within the BigQuery console.
Google BigQuery is configured through the Immuta console and a script provided by Immuta. While you can complete some steps within the BigQuery console, it is easiest to install using gcloud and the Immuta script.
Once Google BigQuery has been configured, BigQuery admins can start creating subscription and data policies to meet compliance requirements and users can start querying policy protected data directly in BigQuery.
Create a global or .
Revoke user access to the original datasets and grant users access to the Immuta created datasets in BigQuery.
What permissions will Immuta have in my BigQuery environment?
You can find a list of the permissions the custom Immuta role has .
What integration features will Immuta support for BigQuery?
For private preview, Immuta supports a basic version of the BigQuery integration where Immuta can enforce specific policies on data in a single BigQuery project. At this time, workspaces, tag ingestion, user impersonation, query audit, and multiple integrations are not supported.
In this policy push integration, Immuta creates views that contain all policy logic. Each view has a 1-to-1 relationship with the original table. Access controls are applied in the view, allowing organizations to leverage Immuta’s powerful set of attribute-based policies and query data directly in BigQuery.
BigQuery is organized by projects (which can be thought of as databases), datasets (which can be compared to schemas), tables, and views. When you enable the integration, an Immuta dataset is created in BigQuery that contains the Immuta-required user entitlements information. These objects within the Immuta dataset are intended to only be used and altered by the Immuta application.
After data sources are registered, Immuta uses the custom user and role, created before the integration is enabled, to push the Immuta data sources as views into a mirrored dataset of the original table. Immuta manages grants on the created view to ensure only users subscribed to the Immuta data source will see the data.
The Immuta integration uses a mirrored dataset approach. That is, if the source dataset is named mydataset, Immuta will create a dataset named mydataset_secure, assuming that _secure is the specified Immuta dataset suffix. This mirrored dataset is an , allowing it to access the data of the original dataset. It will contain the Immuta-managed views, which have identical names to the original tables they’re based on.
Following the principle of least privilege, Immuta does not have permission to manage Google Cloud Platform users, specifically in granting or denying access to a project and its datasets. This means that data governors should limit user access to original datasets to ensure data users are accessing the data through the Immuta created views and not the backing tables. The only users who need to have access to the backing tables are the credentials used to register the tables in Immuta.
Additionally, a data governor must grant users access to the mirrored datasets that Immuta will create and populate with views. Immuta and BigQuery’s best practice recommendation is to grant access via groups in Google Cloud Platform. Because users still must be registered in Immuta and subscribed to an Immuta data source to be able to query Immuta views, all Immuta users can be granted access to the mirrored datasets that Immuta creates.
The status of the integration is visible on the integrations tab of the Immuta application settings page. If errors occur in the integration, a banner will appear in the Immuta UI with guidance for remediating the error.
The definitions for each status and the state of configured data platform integrations is available in the . However, the UI consolidates these error statuses and provides detail in the error messages.
This integration can only be enabled through a manual bootstrap using the Immuta API.
This integration can only be enabled to work in a single region.
BigQuery does not allow views partitioned by pseudo-columns. If you would like to partition a table by a pseudo-column and have Immuta govern it, take the following steps:
Create a view in BigQuery of the partitioned table, with the pseudo-column aliased. For example,
This integration supports the following policy types:
Column masking
Mask using hashing (SHA256())
Mask by making NULL
Mask using constant
See the resources below to start implementing and using the BigQuery integration:
Building global and to govern data
to collaborate
Follow this guide to connect your Google BigQuery data warehouse to Immuta.
Google BigQuery integration (PrPr) enabled.
Immuta role with SYSTEM_ADMIN permissions and an .
.
The Google BigQuery integration requires you to create a Google Cloud service account and role that will be used by Immuta to
create a Google BigQuery dataset that will be used to store a table of user entitlements, UDFs for policy enforcement, etc.
manage the table of user entitlements via updates when entitlements change in Immuta.
create datasets and secure views with access control policies enforced, which mirror tables inside of datasets you ingest as Immuta data sources.
You have two options to create the required Google Cloud service account and role:
The bootstrap.sh script is a shell script provided by Immuta that creates prerequisite Google Cloud IAM objects for the integration to connect. When you run this script from your command line, it will create the following items, scoped at the project-level:
A new Google Cloud IAM role
A new Google Cloud service account, which will be granted the newly-created role
A JSON keyfile for the newly-created service account
You will need to use the objects created in these steps to .
Google Cloud IAM roles required to run the script
To execute bootstrap.sh from your command line, you must be authenticated to the gcloud CLI utility as a user with all of the following roles:
roles/iam.roleAdmin
roles/iam.serviceAccountAdmin
roles/serviceusage.serviceUsageAdmin
Having these three roles is the least-privilege set of Google Cloud IAM roles required to successfully run the bootstrap.sh script from your command line. However, having either of the following Google Cloud IAM roles will also allow you to run the script successfully:
roles/editor
roles/owner
Install .
Set the account property in the core section for Google Cloud CLI to the account gcloud should use for authentication. (You can run gcloud auth list to see your currently available accounts):
In Immuta, navigate to the App Settings page and click the Integrations tab.
Click Add Integration
Alternatively, you may use the Google Cloud Console to create the prerequisite role, service account, and private key file for the integration to connect to Google BigQuery.
with the following privileges:
bigquery.datasets.create
bigquery.datasets.delete
Once the Google Cloud IAM custom role and service account are created, you can enable the Google BigQuery integration. This section illustrates how to enable the integration on the Immuta app settings page. To configure this integration via the Immuta API, see the .
In Immuta, navigate to the App Settings page and click the Integrations tab.
Click Add Integration and select Google BigQuery from the dropdown menu.
Click Select Authentication Method and select Key File.
You can disable the Google BigQuery integration automatically or manually.
Click the App Settings icon, and then click the Integrations tab.
Select the Google BigQuery integration you would like to disable, and select the Disable Integration checkbox.
Click Save.
The privileges required to run the cleanup script are the same as the Google Cloud IAM roles required to run the bootstrap.sh script.
Click the App Settings icon, and then click the Integrations tab.
Select the Google BigQuery integration you would like to disable, and click Download Scripts.
Click Save. Wait until Immuta has finished saving your configuration changes before proceeding.
Build and
to securely collaborate on analytical workloads
IMMUTA_SPARK_DATABRICKS_ALLOW_NON_IMMUTA_WRITES: Immuta users with regular (non-privileged) Databricks roles can run DDL commands and data-modifying commands against tables or spaces that are not registered in Immuta. With non-Immuta writes enabled through the cluster policy, users on the cluster can mix any policy-enforced data they may have access to via any registered data sources in Immuta with non-Immuta data and write the ensuing result to a non-Immuta write space where it would be visible to others. If this is not a desired possibility, the cluster should instead be configured to only use Immuta’s project workspaces.executing a Spark query. This will force Immuta to wait for any trusted Immuta libraries to complete installation before proceeding.
When installing a library using Maven as a library source, Databricks will also install any transitive dependencies for the library. However, those transitive dependencies are installed behind the scenes and will not appear as installed libraries in either the Databricks UI or using the Databricks Libraries API. Only libraries specifically listed in the IMMUTA_SPARK_DATABRICKS_TRUSTED_LIB_URIS environment variable will be trusted by Immuta, which does not include installed transitive dependencies. This effectively means that any code paths that include a class from a transitive dependency but do not include a class from a trusted third-party library can still be blocked by the Immuta security manager. For example, if a user installs a trusted third-party library that has a transitive dependency of a file-util library, the user will not be able to directly use the file-util library to read a sensitive file that is normally protected by the Immuta security manager.
In many cases, it is not a problem if dependent libraries aren't trusted because code paths where the trusted library calls down into dependent libraries will still be trusted. However, if the dependent library needs to be trusted, there is a workaround:
Add the transitive dependency jar paths to the . In the driver log4j logs, Databricks outputs the source jar locations when it installs transitive dependencies. In the cluster driver logs, look for a log message similar to the following:
In the above example, where slf4j is the transitive dependency, you would add the path dbfs:/FileStore/jars/maven/org/slf4j/slf4j-api-1.7.25.jar to the IMMUTA_SPARK_DATABRICKS_TRUSTED_LIB_URIS environment variable and restart your cluster.
Behavior change in Immuta v2025.1 and newer
If a table is registered in Immuta and does not have a subscription policy applied to it, that data will be visible to users, even if the Protected until made available by policy setting is enabled.
If you have enabled this setting, author an "Allow individually selected users" global subscription policy that applies to all data sources.
Security vulnerability
Using this feature could create a security vulnerability, depending on the third-party library. For example, if a library exposes a public method named readProtectedFile that displays the contents of a sensitive file, then trusting that library would allow end users access to that file. Work with your Immuta support professional to determine if the risk does not apply to your environment or use case.
SQL
A policy is deleted: When a policy is deleted, the policy information is deleted from the Metadata Database. If users were granted access to the data source by that policy, their access is revoked.
Databricks user is mapped to Immuta: When a Databricks user is mapped to Immuta, their metadata is stored in the Metadata Database.
Databricks user queries data: When a user queries the data in Databricks, Immuta intercepts the call from Spark down to the Metastore. Then, the Immuta-maintained Spark plugin retrieves the policy information, the user metadata, and the data source metadata from the Metadata Database and injects this information as policy logic into the Spark logical plan. Once the physical plan is applied, Databricks returns policy-enforced data to the user.
Databricks Connect is unsupported: Databricks Connect is unsupported because Py4J security must be enabled to use it.
✅
✅
✅
✅
✅
Non-Immuta reads and writes
✅
✅
✅
✅
✅
✅
Python
✅
✅
SQL
✅
✅
R
✅
❌
Scala
✅
❌
Immuta project workspaces
✅
❌
Smart mask ordering
✅
❌
Masking and tagging complex columns (STRUCT, ARRAY, MAP)
✅
❌
Photon support
✅
❌
dbutils
✅
❌
Databricks Connect
✅
❌
Write policies
❌
❌
Support for allowlisting networks or local filesystem paths
❌
✅
Subscription policies
✅
✅
Data policies
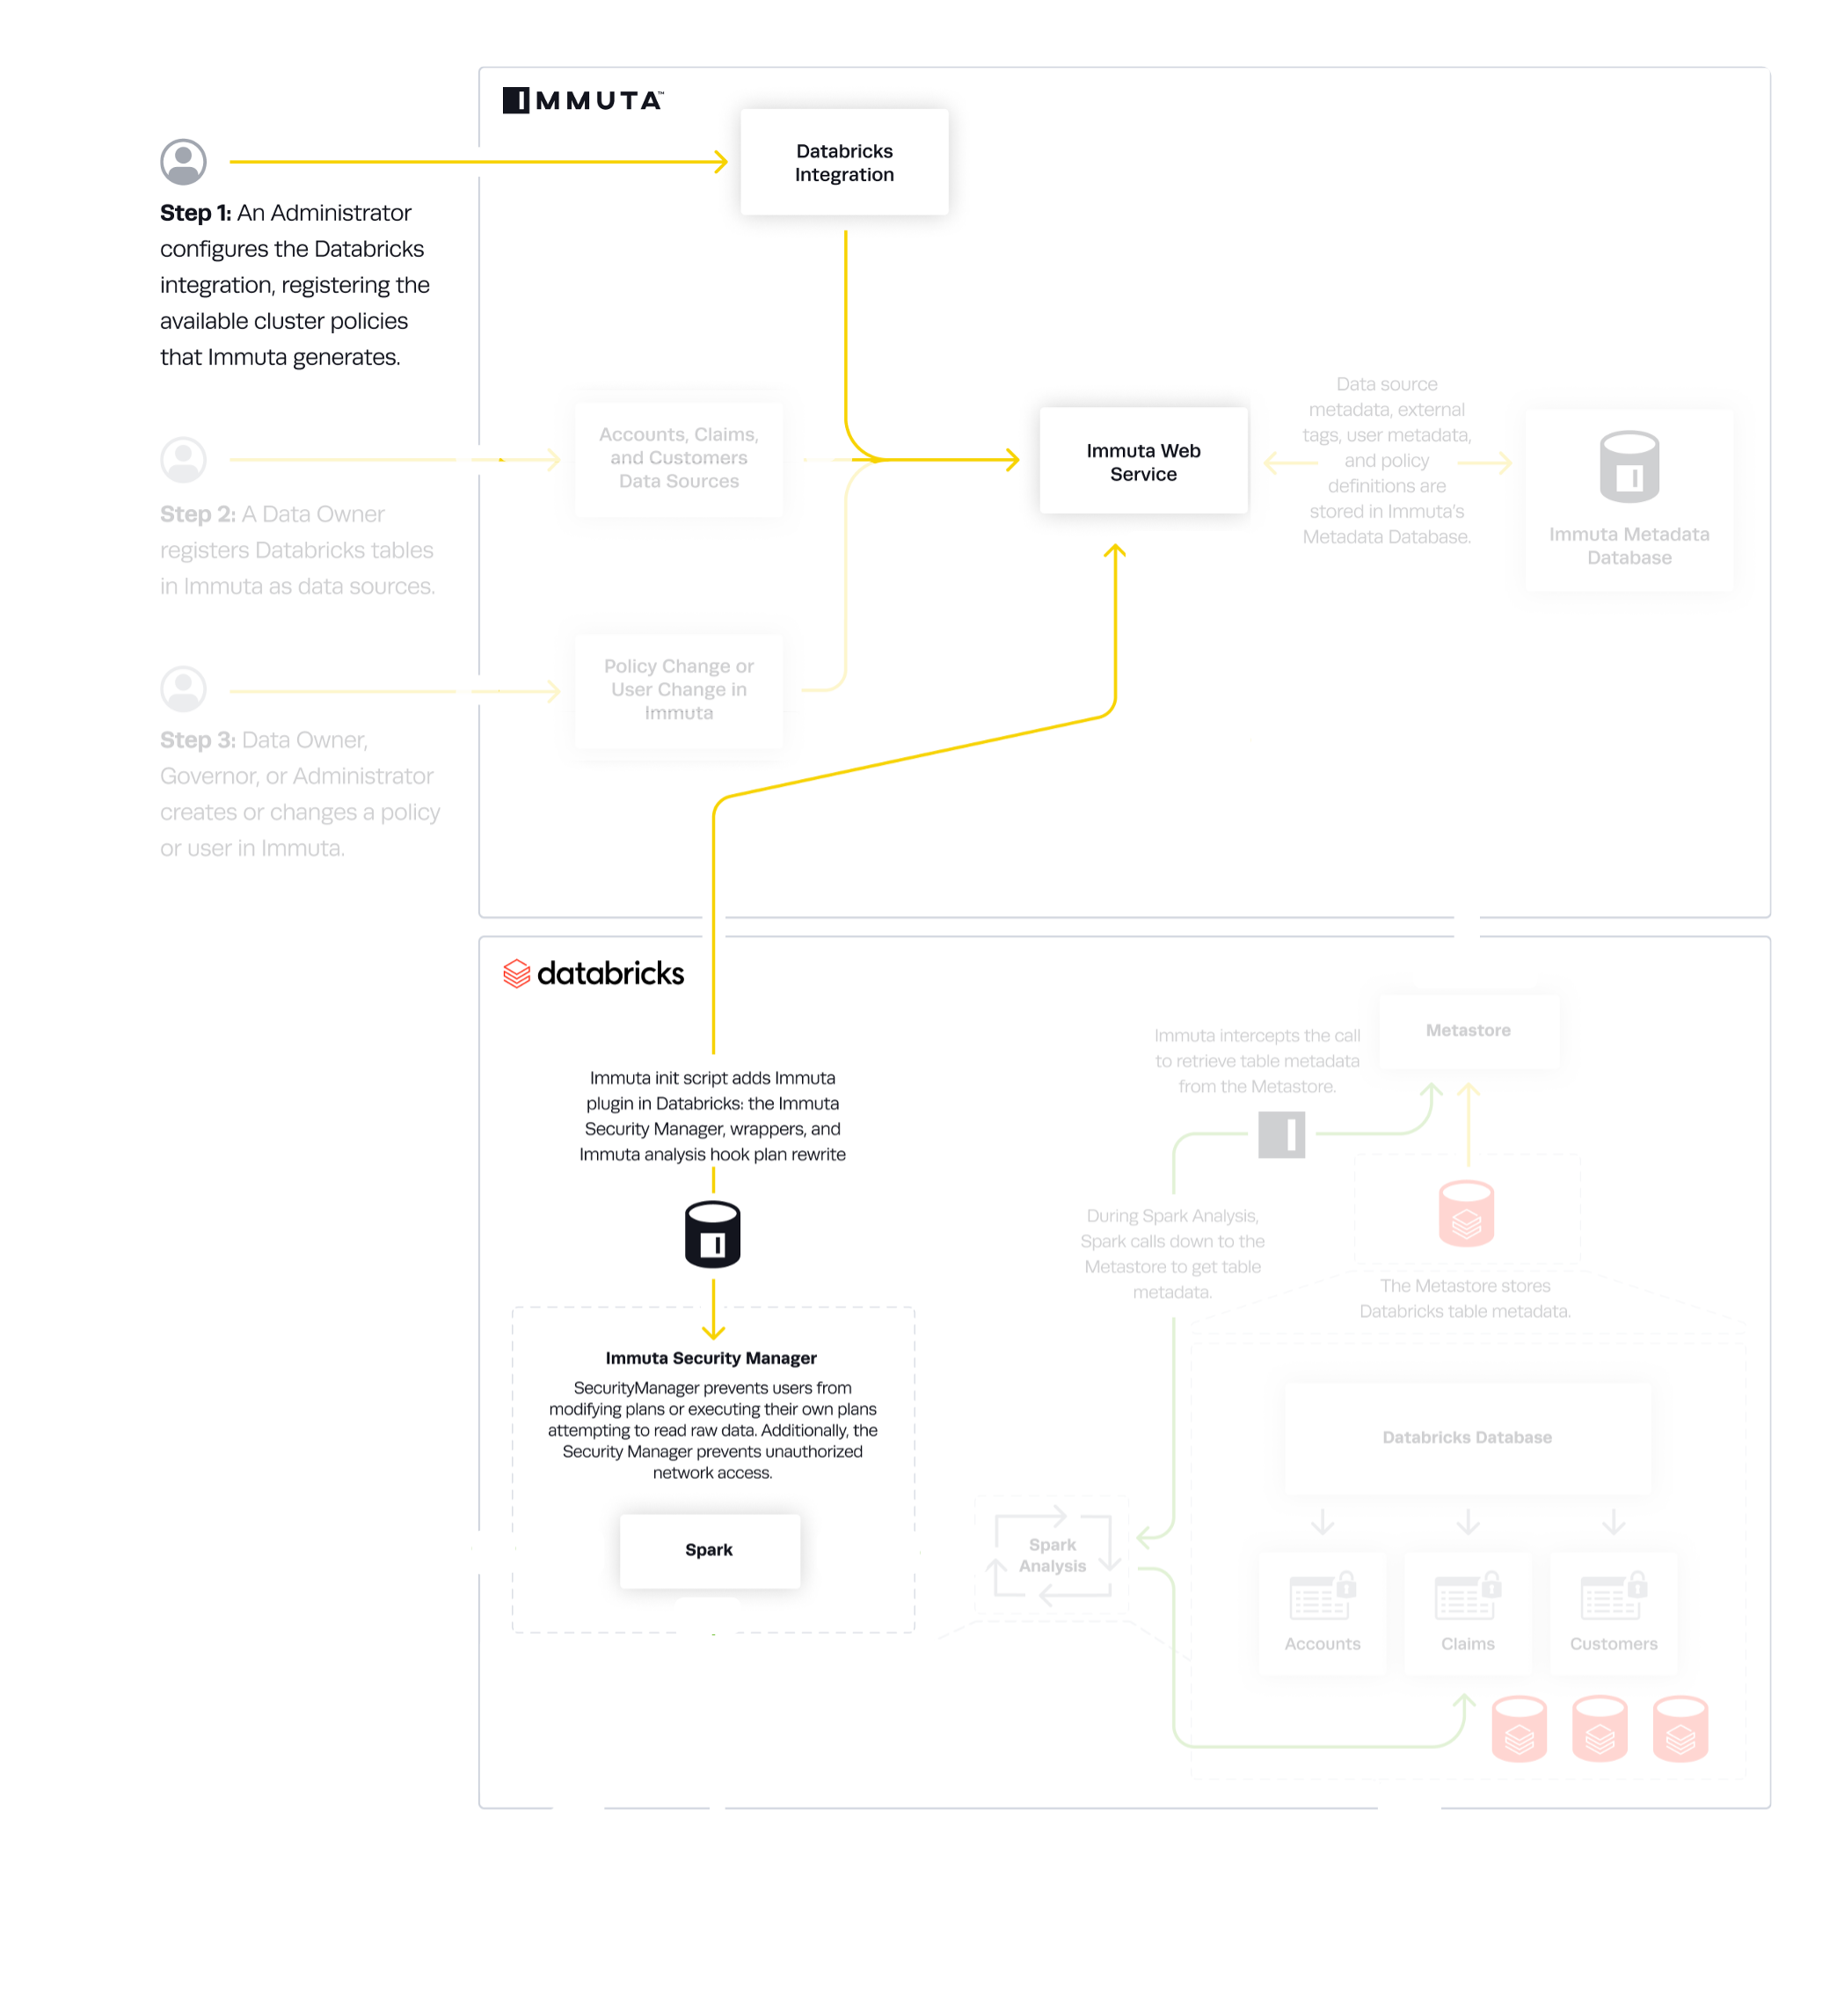
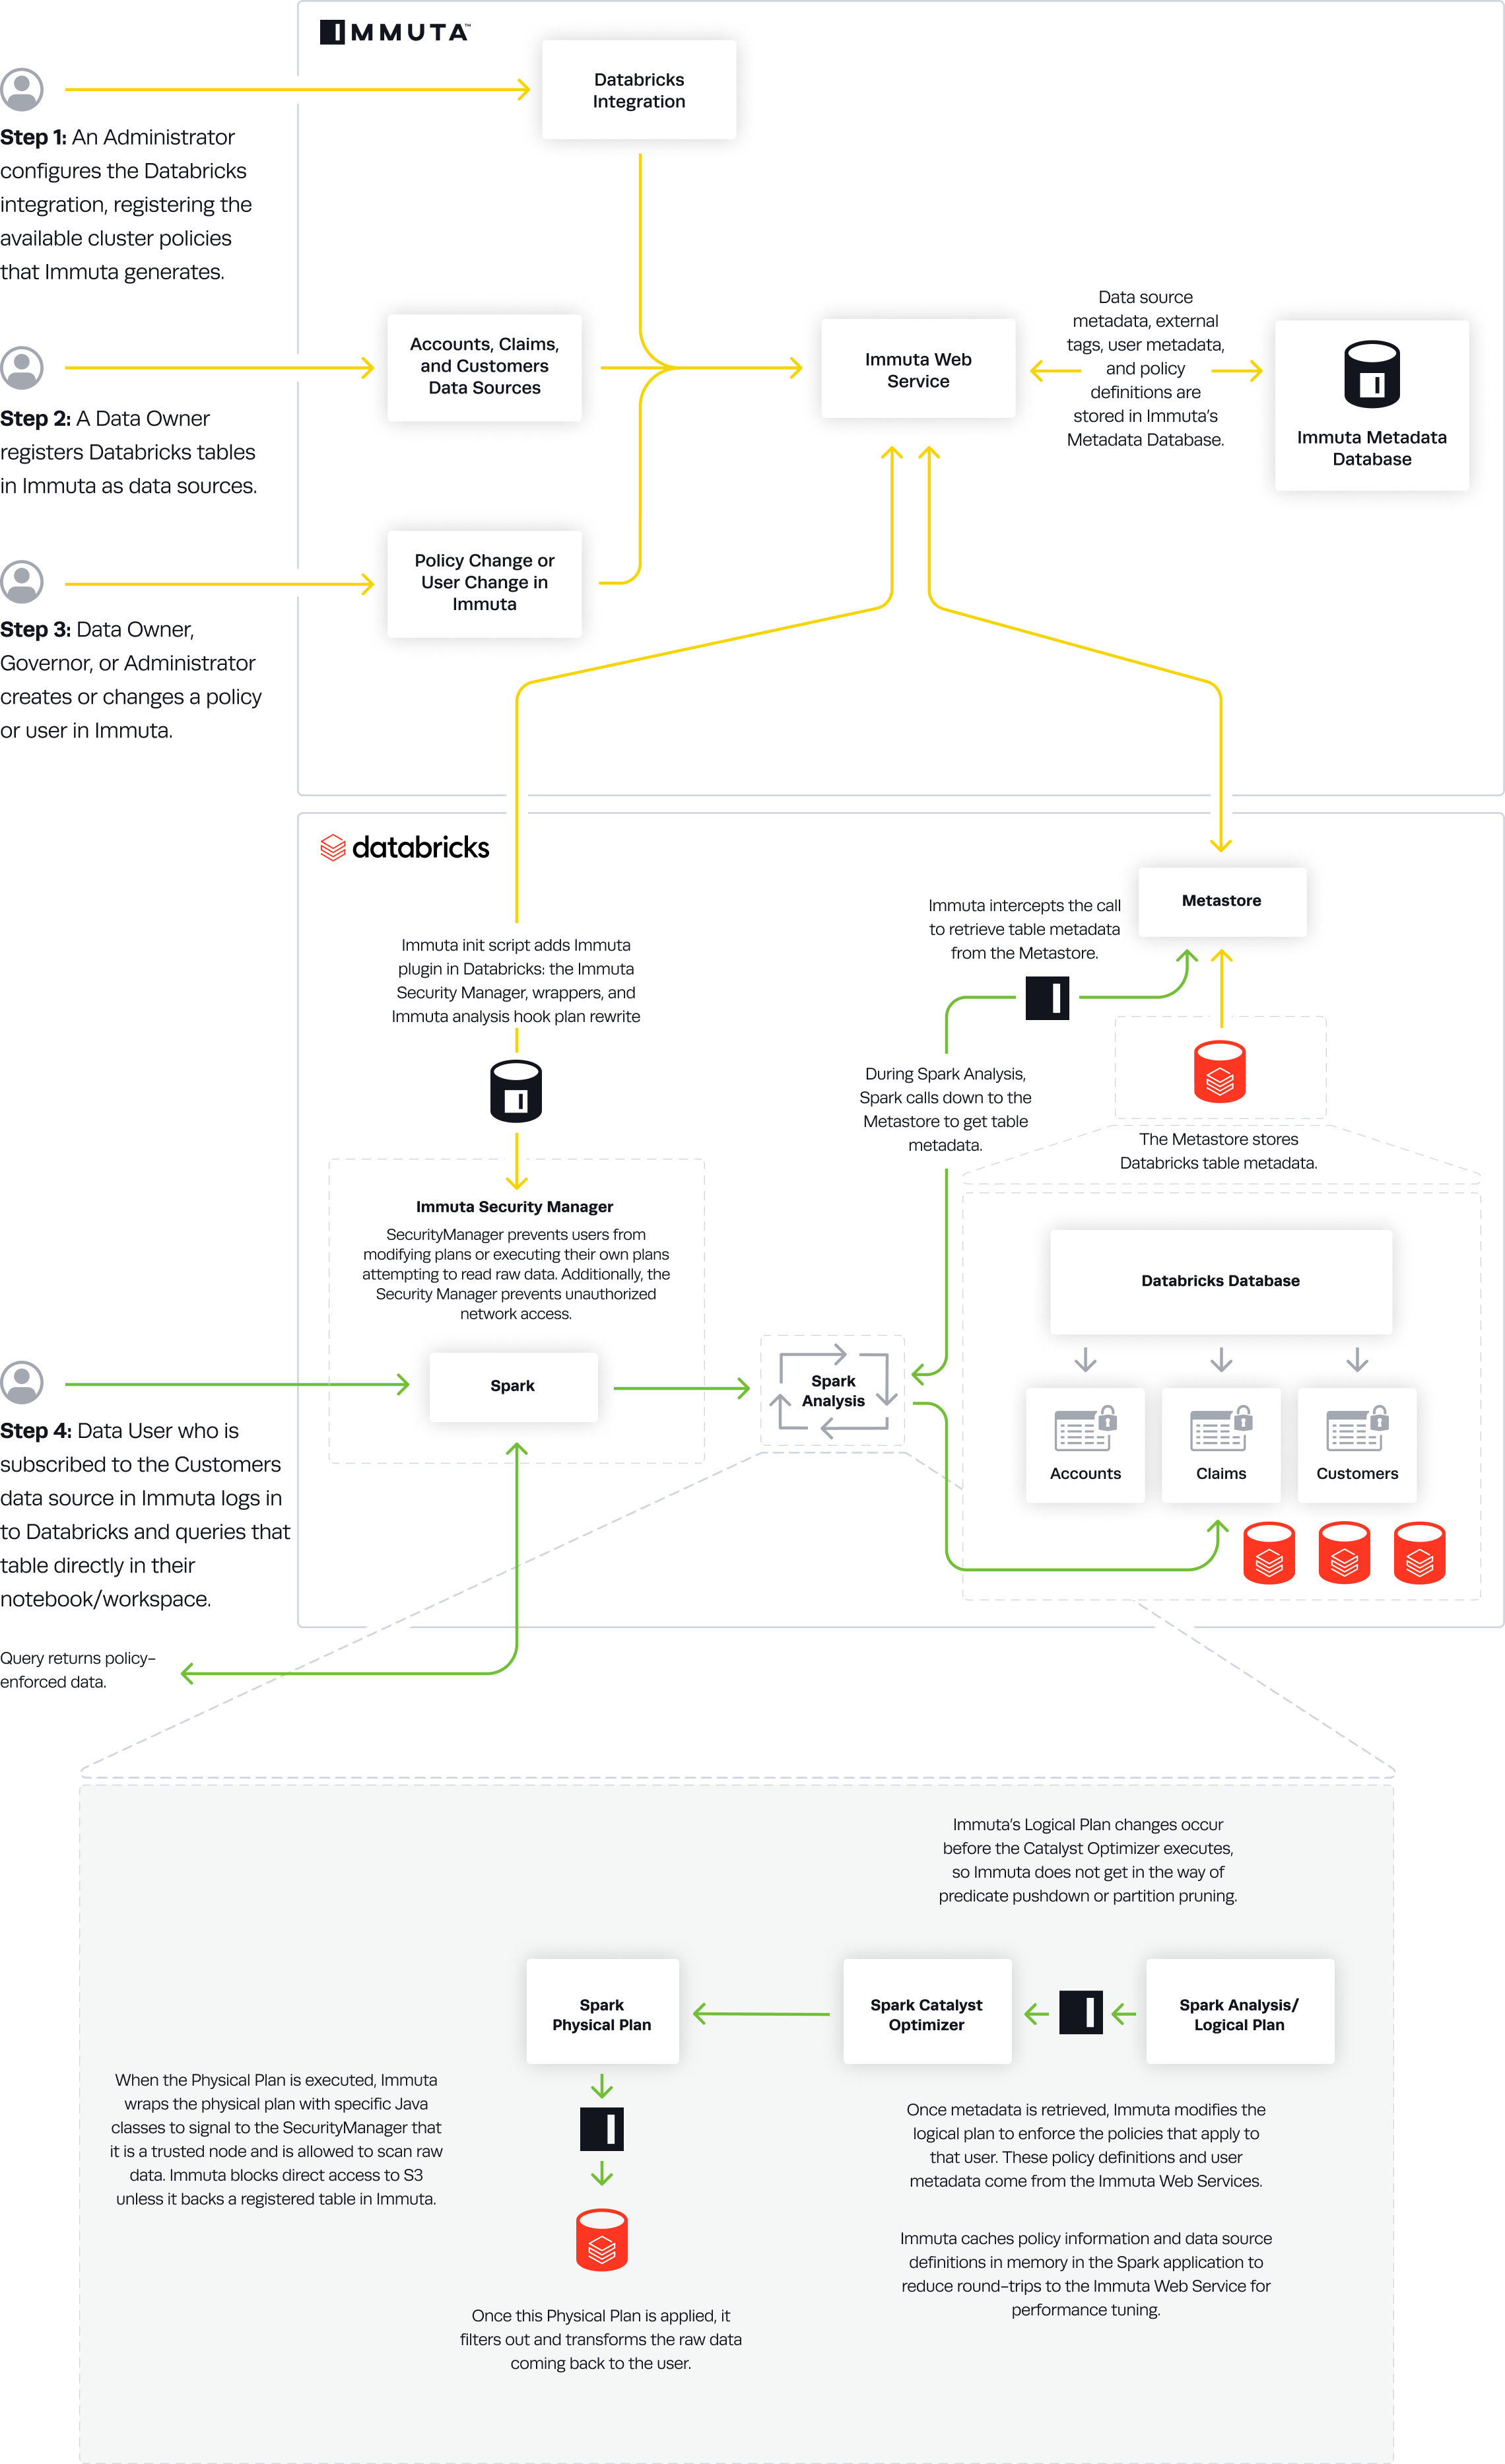
✅
Users query data from the Immuta created datasets directly in BigQuery.
Register this view as a BigQuery data source in Immuta.
Immuta will then be able to create Immuta-managed views off of this view with the pseudo-column aliased.
Mask using a regular expression
Mask by date rounding
Mask by numeric rounding
Mask using custom functions
Row filtering based on user attributes and/or object attributes
Filter rows using custom WHERE clause
Click Select Authentication Method and select Key File.
Click Download Script(s).
Before you run the script, update your permissions to execute it:
chmod 755 <path to downloaded script>Run the script, where
PROJECT_ID is the Google Cloud Platform project to operate on.
ROLE_ID is the name of the custom role to create.
NAME will create a service account with the provided name.
OUTPUT_FILE is the path where the resulting private key should be written. File system write permission will be checked on the specified path prior to the key creation.
undelete-role (optional) will undelete the custom role from the project. Roles that have been deleted for a long time can't be undeleted. This option can fail for the following reasons:
The role specified does not exist.
The active user does not have permission to access the given role.
enable-api (optional) provided you’ve been granted access to enable the Google BigQuery API, will enable the service.
bigquery.datasets.getbigquery.datasets.update
bigquery.jobs.create
bigquery.jobs.get
bigquery.jobs.list
bigquery.jobs.listAll
bigquery.routines.create
bigquery.routines.delete
bigquery.routines.get
bigquery.routines.list
bigquery.routines.update
bigquery.tables.create
bigquery.tables.delete
bigquery.tables.export
bigquery.tables.get
bigquery.tables.getData
bigquery.tables.list
bigquery.tables.setCategory
bigquery.tables.update
bigquery.tables.updateData
bigquery.tables.updateTag
Create a service account and grant it the custom role you just created.
Project Id: The Google Cloud Platform project to operate on, where your Google BigQuery data warehouse is located. A new dataset will be provisioned in this Google BigQuery project to store the integration configuration.
Service Account: The service account you created in create a Google Cloud service account and role for Immuta to use to connect to Google BigQuery.
Complete the following fields:
Immuta Dataset: The name of the Google BigQuery dataset to provision inside of the project. Important: if you are using multiple environments in the same Google BigQuery project, this dataset to provision must be unique across environments.
Immuta Role: The custom role you created in create a Google Cloud service account and role for Immuta to use to connect to Google BigQuery.
Dataset Suffix: The suffix that will be postfixed to the name of each dataset created to store secure views, one per dataset that you ingest a table for as a data source in Immuta. Important: if you are using multiple environments in the same Google BigQuery project, this suffix must be unique across environments.
GCP Location: The dataset’s location. After a dataset is created, the location can't be changed. Note that
If you choose EU for the dataset location, your Core BigQuery Customer Data resides in the EU.
Click Test Google BigQuery Integration.
Click Save.
Run the cleanup script.
gcloud config set account ACCOUNTGCP location must match dataset region
The region set for the GCP location must match the region of your datasets. Set GCP location to a general region (for example, US) to include child regions.
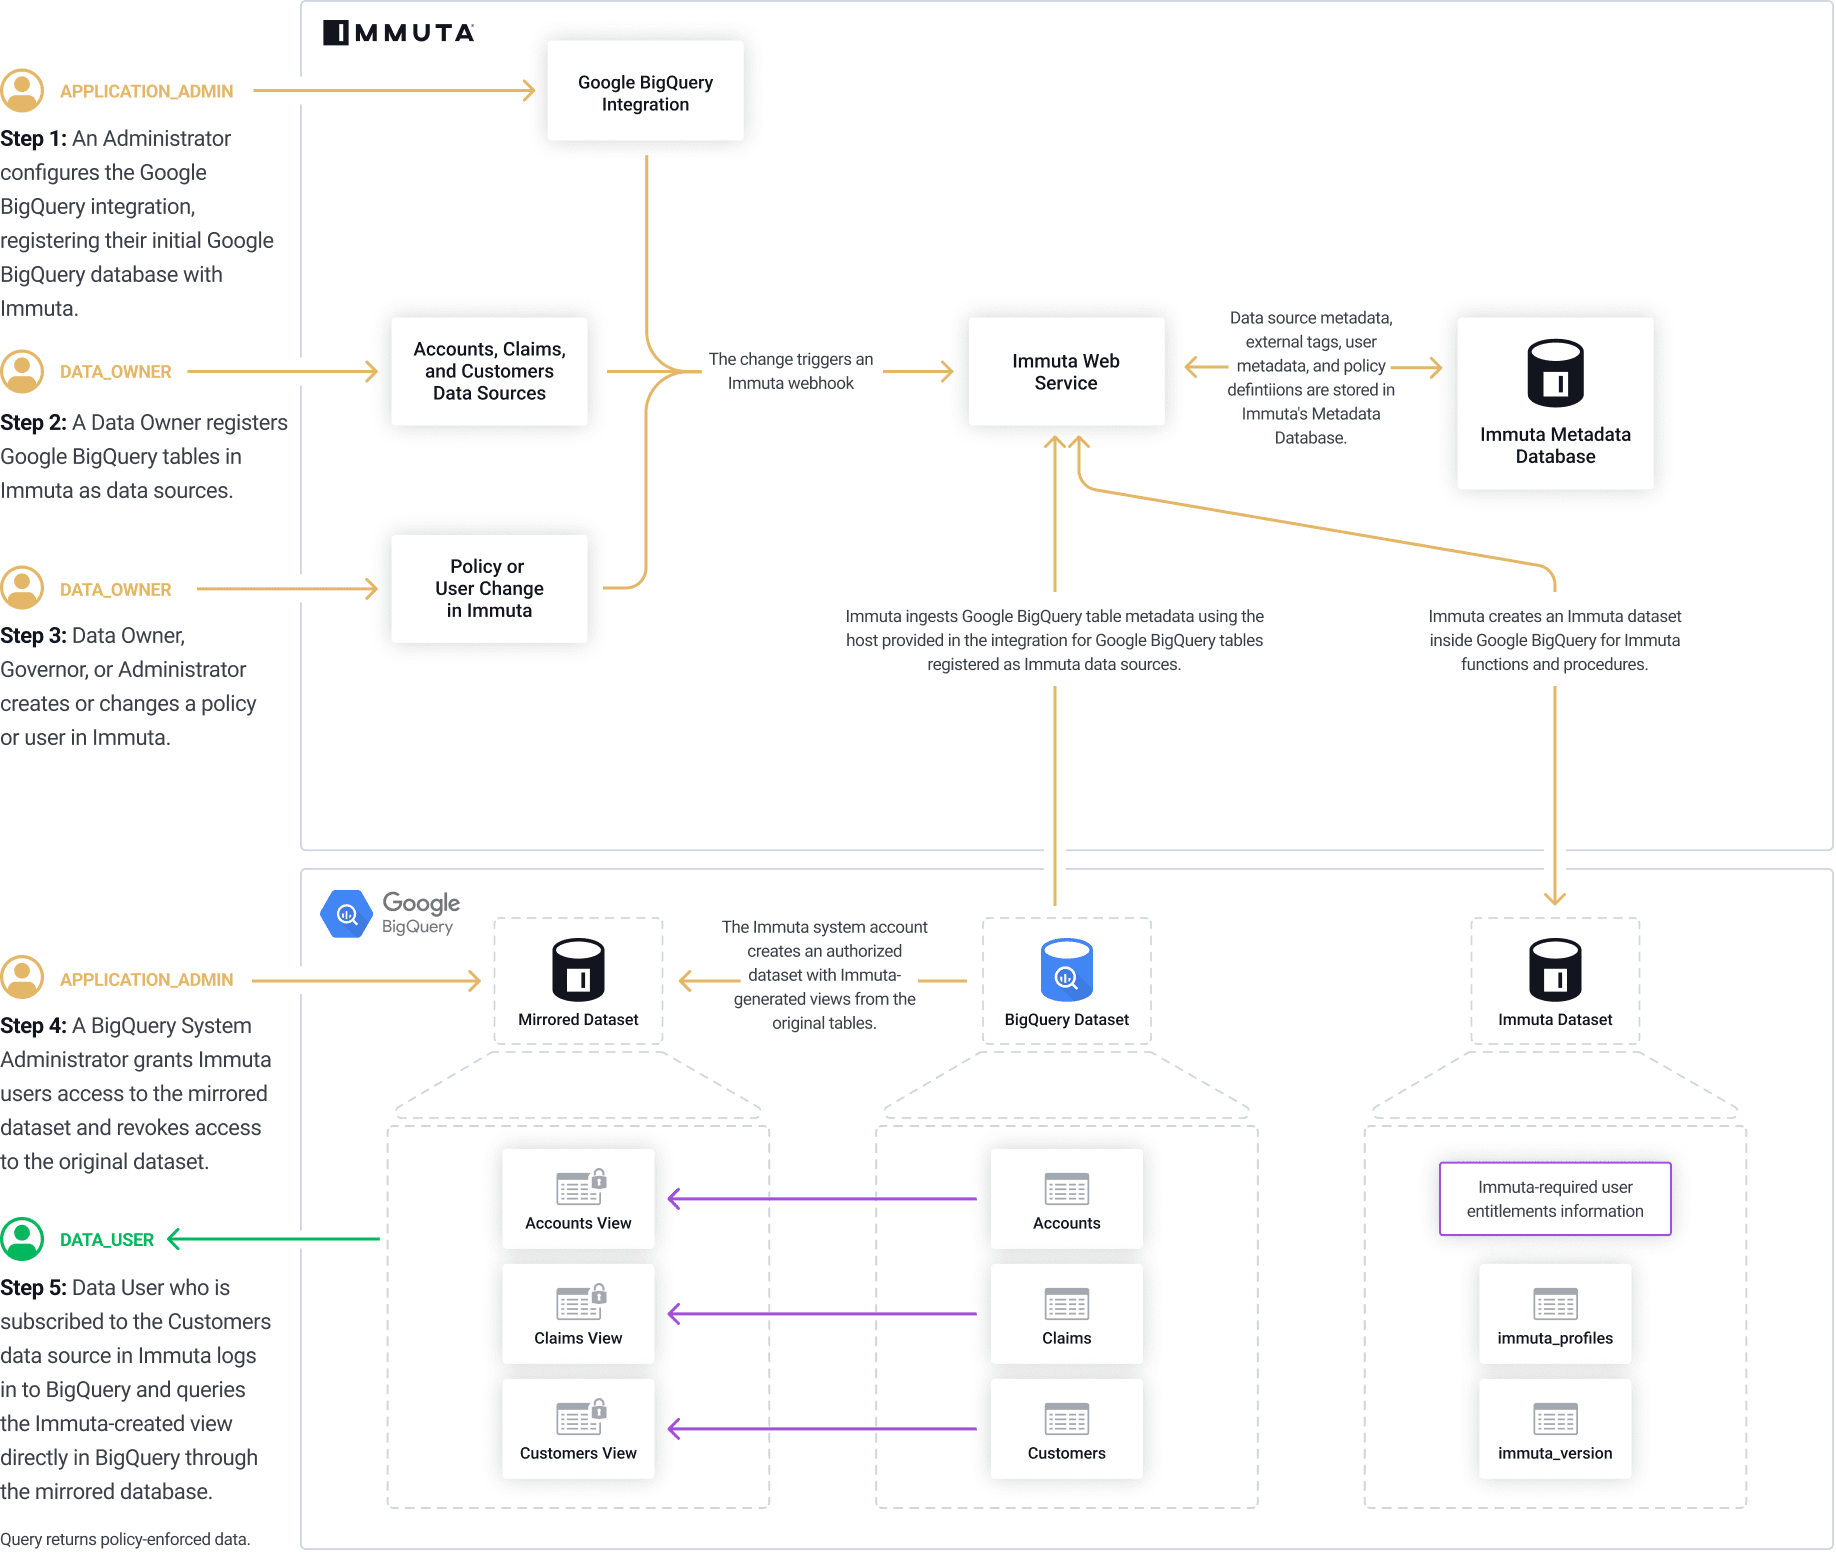
create view `sales`.`emea`.`sales_view` as SELECT *, _PARTITIONTIME as __partitiontime from `sales`.`emea`.`sales`chmod 755 <path to downloaded script>$ bootstrap.sh \
--project PROJECT_ID \
--role ROLE_ID \
--service_account NAME \
--keyfile OUTPUT_FILE \
[--undelete-role] \
[--enable-api]INFO LibraryDownloadManager: Downloaded library dbfs:/FileStore/jars/maven/org/slf4j/slf4j-api-1.7.25.jar as
local file /local_disk0/tmp/addedFile8569165920223626894slf4j_api_1_7_25-784af.jarIMMUTA_DATABRICKS_SPARKLYR_SUPPORT_ENABLED=truesc <- spark_connect(method = "databricks")dbGetQuery(sc, "show tables in immuta")spark.databricks.passthrough.enabled true
spark.databricks.pyspark.trustedFilesystems com.databricks.s3a.S3AFileSystem,shaded.databricks.azurebfs.org.apache.hadoop.fs.azurebfs.SecureAzureBlobFileSystem,shaded.databricks.v20180920_b33d810.org.apache.hadoop.fs.azurebfs.SecureAzureBlobFileSystem,com.databricks.adl.AdlFileSystem,shaded.databricks.V2_1_4.com.google.cloud.hadoop.fs.gcs.GoogleHadoopFileSystem,shaded.databricks.org.apache.hadoop.fs.azure.NativeAzureFileSystem,shaded.databricks.org.apache.hadoop.fs.s3a.S3AFileSystem,org.apache.hadoop.fs.ImmutaSecureFileSystemWrapper
spark.hadoop.fs.s3a.aws.credentials.provider com.amazonaws.auth.InstanceProfileCredentialsProviderIMMUTA_DATABRICKS_SPARKLYR_SUPPORT_ENABLED=true
IMMUTA_SPARK_REQUIRE_EQUALIZATION=true
IMMUTA_SPARK_CURRENT_USER_SCIM_FALLBACK=falseimmuta.spark.acl.assume.not.privileged true
immuta.api.key=<user’s API key>IMMUTA_SPARK_SHOW_IMMUTA_DATABASE=falseThis is a guide on how to deploy Immuta on OpenShift.
The following managed services must be provisioned and running before proceeding. For further assistance consult the recommendations table for your respective cloud provider.
Feature availability
If deployed without Elasticsearch/OpenSearch, several core services and features will be unavailable. See the for details.
PostgreSQL
(Optional) Elasticsearch/OpenSearch Service
This checklist outlines the necessary prerequisites for successfully deploying Immuta.
Create an OpenShift project named immuta.
Get the UID range allocated to the project. Each running container's UID must fall within this range. This value will be referenced later on.
Get the GID range allocated to the project. Each running container's GID must fall within this range. This value will be referenced later on.
Switch to project
Create a container registry pull secret. Your credentials to authenticate with ocir.immuta.com are provided by Immuta; there is currently no self-service lookup — contact your Immuta representative or Immuta Support if you do not have them.
Connect to the database as an admin (e.g., postgres) by creating an ephemeral container inside the Kubernetes cluster. A shell prompt will not be displayed after executing the kubectl run command outlined below. Wait 5 seconds, and then proceed by entering a password.
Create the immuta role.
Grant administrator privileges to the immuta role, where <admin-role> is rds_superuser (Amazon RDS), azure_pg_admin (Azure Database), or cloudsqlsuperuser (Google Cloud SQL). Upon successfully completing this installation guide, you can optionally revoke this role grant.
Create databases.
Grant role immuta additional privileges. Refer to the for further details on database roles and privileges.
Configure the immuta database.
This section demonstrates how to deploy Immuta using the Immuta Enterprise Helm chart once the prerequisite cloud-managed services are configured.
Create a file named immuta-values.yaml with the above content, making sure to update all .
Deploy Immuta.
Wait for all pods to become ready.
Determine the name of the gateway service.
Listen on local port 8080, forwarding TCP traffic to the gateway service's port named http.
In a web browser, navigate to , to ensure the Immuta application loads.
.
.
You must be on the most or newer to upgrade directly to this version of Immuta.
Back up the audit database.
The following changes are new to 2026.2 and will require additional action before you upgrade. See details about each change in the linked sections below:
immutatemporal database.Configure the temporal_visibility database.
Exit the interactive prompt. Type \q, and then press Enter.
Control+C to stop port forwarding.Feature availability
If deployed without Elasticsearch/OpenSearch, several core services and features will be unavailable. See the deployment requirements for details.
Avoid these special characters in generated passwords
whitespace, $, &, :, \, /, ', "
\c temporal_visibility
GRANT CREATE ON SCHEMA public TO immuta;
CREATE EXTENSION btree_gin;echo <token> | helm registry login --password-stdin --username <username> ocir.immuta.comoc new-project immutaoc get project immuta --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'oc get project immuta --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'oc create secret docker-registry immuta-oci-registry \
--docker-server=https://ocir.immuta.com \
--docker-username="<username>" \
--docker-password="<token>" \
--docker-email=support@immuta.comoc run pgclient \
--stdin \
--tty \
--rm \
--image docker.io/bitnami/postgresql -- \
psql --host <postgres-fqdn> --username <postgres-admin> --dbname postgres --port 5432 --passwordCREATE ROLE immuta with LOGIN ENCRYPTED PASSWORD '<postgres-password>';
ALTER ROLE immuta SET search_path TO bometadata,public;GRANT <admin-role> TO immuta;CREATE DATABASE immuta OWNER immuta;
CREATE DATABASE temporal OWNER immuta;
CREATE DATABASE temporal_visibility OWNER immuta;GRANT ALL ON DATABASE immuta TO immuta;
GRANT ALL ON DATABASE temporal TO immuta;
GRANT ALL ON DATABASE temporal_visibility TO immuta;\c immuta
CREATE EXTENSION pgcrypto;global:
imageRegistry: ocir.immuta.com
imagePullSecrets:
- name: immuta-oci-registry
postgresql:
host: <postgres-fqdn>
port: 5432
username: immuta
password: <postgres-password>
audit:
config:
elasticsearchEndpoint: <elasticsearch-endpoint>
searchAuthenticationType: <'UsernamePassword' or 'AWS'>
# If you use OpenSearch and authenticate with username and password, uncomment the lines below by deleting the hash symbols
#elasticsearchUsername: <elasticsearch-username>
#elasticsearchPassword: <elasticsearch-password>
# If you use OpenSearch and authenticate with AWS role, uncomment the lines below by deleting the hash symbols. When using AWS role authentication, elasticsearchUsername (above) must be set to ''.
#searchAwsRegion: '<deployment-OS-region>'
# If Immuta is deployed in an AWS account that is different than OpenSearch, then you must configure a trust relationship between the Immuta role and an OpenSearch role
#searchAwsRoleArn: '<assumed-role-arn>'
postgresql:
database: immuta
deployment:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
#init:
#extraEnvVars:
# Audit retention defaults to 7 days. To change the retention period, uncomment the lines below by deleting the hash symbols and update the value
#- name: AUDIT_RETENTION_POLICY_IN_DAYS
#value: 90
worker:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
discover:
deployment:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
onboarding:
postgresql:
database: immuta
secure:
postgresql:
database: immuta
ssl: false
web:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
backgroundWorker:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
temporal:
enabled: true
schema:
createDatabase:
enabled: false
server:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
config:
persistence:
default:
sql:
database: temporal
tls:
enabled: true
visibility:
sql:
database: temporal_visibility
tls:
enabled: true
frontend:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
history:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
matching:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
worker:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
schema:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
proxy:
deployment:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
enabled: true
allowPrivilegeEscalation: false
capabilities:
drop:
- ALLglobal:
imageRegistry: ocir.immuta.com
imagePullSecrets:
- name: immuta-oci-registry
postgresql:
host: <postgres-fqdn>
port: 5432
username: immuta
password: <postgres-password>
audit:
enabled: false
discover:
deployment:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
onboarding:
postgresql:
database: immuta
secure:
extraEnvVars:
- name: FeatureFlag_AuditService
value: false
postgresql:
database: immuta
ssl: true
web:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
backgroundWorker:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
temporal:
enabled: true
schema:
createDatabase:
enabled: false
server:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
config:
persistence:
default:
sql:
database: temporal
tls:
enabled: true
visibility:
sql:
database: temporal_visibility
tls:
enabled: true
frontend:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
history:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
matching:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
worker:
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
schema:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
allowPrivilegeEscalation: false
capabilities:
drop:
- ALL
proxy:
deployment:
podSecurityContext:
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.uid-range"}}{{"\n"}}'
runAsUser: <user-id>
# A number that is within the project range:
# oc get project <project-name> --output template='{{index .metadata.annotations "openshift.io/sa.scc.supplemental-groups"}}{{"\n"}}'
runAsGroup: <group-id>
seccompProfile:
type: RuntimeDefault
containerSecurityContext:
enabled: true
allowPrivilegeEscalation: false
capabilities:
drop:
- ALLhelm install immuta oci://ocir.immuta.com/stable/immuta-enterprise \
--values immuta-values.yaml \
--version 2026.2.0oc wait --for=condition=Ready pods --alloc get service --selector "app.kubernetes.io/component=gateway" --output nameoc port-forward <service-name> 8080:httpoc project immuta\c temporal
GRANT CREATE ON SCHEMA public TO immuta;Ingress migration: The ingress configuration values in the Helm chart have moved.
Onboarding service: The Immuta deployment now has an onboarding service, which must be represented in the Helm chart.
Tenant ID: A global tenant ID must now be manually set in the Helm chart as a UUID.
OpenSearch index: Your OpenSearch cluster index names must now be manually set in the Helm chart.
Guardrail subscription policies: Global policies now have the option to grant or guardrail users' access. The migration to these two options is automated, but you should check your subscription policies before the upgrade to ensure you understand the impact.
Add the Onboarding service to your immuta-values.yaml file. This value is required and must be set to use the same database as secure.postgresql.database.
secure:
postgresql:
database: immuta
ssl: true
onboarding:
postgresql:
database: immutaSet the new tenant ID as a UUID under global.tenantId in immuta-values.yaml:
global:
tenantId: <NEW_UUID> under audit.config.searchIndexName and audit.config.searchIndexAliasName in immuta-values.yaml:
, , and upgrade Immuta using one of the methods below.
If you encounter an upgrade failure, see the Troubleshooting page for a list of error messages and remediation steps.
This section describes changes that require action before you upgrade Immuta. For a full list of new features and behavior changes, see the 2026.2 release notes.
The ingress configuration values that were previously in secure.ingress in the immuta-values.yaml file have moved to gateway.ingress.
The snippets below show a sample comparison of the 2026.1 ingress configuration and the 2026.2 ingress configuration.
2026.1 Helm values
secure:
postgresql:
database: immuta
ssl: true
ingress:
enabled: true
hostname: <immuta-fqdn>
annotations:
# Determines which type of load balancer is provisioned
# gce-internal
# gce
kubernetes.io/ingress.class: gce
# Listen on both 80 and 443
kubernetes.io/ingress.allow-http: 'true'
# Redirect traffic from 80 to 443
cloud.google.com/frontend-config: immuta2026.2 Helm values
secure:
postgresql:
database: immuta
ssl: true
gateway:
ingress:
enabled: true
hostname: <immuta-fqdn>
annotations:
# Determines which type of load balancer is provisioned
# gce-internal
# gce
kubernetes.io/ingress.class: gce
# Listen on both 80 and 443
kubernetes.io/ingress.allow-http: 'true'
# Redirect traffic from 80 to 443
cloud.google.com/frontend-config: immutaThe Helm chart will not upgrade if secure.ingress is still present; however, removing that content without following one of the migration methods linked below will delete your ingress resource and load balancer irrevocably. In order to upgrade Immuta, use one of the following methods detailed in the upgrade Immuta section to migrate ingress:
Method A: Zero load-balancer impact (recommended): This migration method keeps the ingress resource across the upgrade and only changes what it points at.
Method B: Chart-managed ingress (requires DNS control): You can use this method if your team controls DNS and load-balancer provisioning directly. This method gets you a fully chart-managed ingress at the cost of one planned DNS cutover.
Method C: Not using the Helm chart's ingress: Use this method if you do not use the Helm chart's ingress and instead use OpenShift or a corporate load balancer pointed at the secure service. This method has minimal impact, but includes one recommended follow-up.
2026.2 introduces the Onboarding service. The Helm value onboarding.postgresql.database is required and must be set to use the same database as secure.postgresql.database, not a new database. The upgrade will fail without it. See the upgrade Immuta section for instructions.
2026.1 Helm values
secure:
postgresql:
database: immuta
ssl: true2026.2 Helm values
secure:
postgresql:
database: immuta
ssl: true
onboarding:
postgresql:
database: immutaThis section applies to self-managed deployments with audit-service enabled.
As part of the upgrade to 2026.2, update the audit tenant ID in the Helm values and the configuration used to send events to audit-service. The tenant ID must be a UUID. It will identify your audit history and must stay the same for future upgrades.
This section applies to self-managed deployments with audit-service enabled.
Before you begin
Confirm that the OpenSearch user has the indices:data/write/update/byquery permission for the audit index. This is a new permission requirement for 2026.2.
Find your OpenSearch index names
Run the following report on your current deployment, before upgrading:
This report reads your search cluster through the audit service’s own credentials, changes nothing, and prints the values to set when upgrading.
Output example:
Use those names in the immuta-values.yaml file when upgrading Immuta.
Guardrail subscription policies prevent users from gaining access to data unless they meet specific conditions. For some customers, moving to this new feature entails an automated migration of existing subscription policy logic. Subscription policies that use the always required option will become guardrail policies and subscription policies that use the shared responsibility option will become grant policies.
Always required
Guardrail policy
Shared responsibility
Grant policy
When migrating always required to guardrail subscription policies, there is one key difference in behavior: An always required policy would still subscribe users, but a guardrail policy will not; instead, guardrail policies ensure that users only get access to data if they are part of the eligible set of users, but no user will be actually subscribed unless there is also at least one grant policy targeting the data source. The table below illustrates this behavior with a policy example.
Policy
Subscribe users when user is a member of group Finance on all data sources tagged sales.
Prevent users from gaining access unless user is a member of group Finance on all data sources tagged sales.
Result
Everyone from Finance gets subscribed
Before you upgrade Immuta to 2026.2, run an impact assessment by following the steps in the upgrade Immuta section to identify what data sources have subscription policies applied to them that will be affected by the upgrade.
Click below to expand explanations of the migration scenarios so that you understand policies that will be created in your tenant and how they will affect users' access.
Once the guardrail feature is enabled, the Immuta system will automatically handle the shareResponsibility parameter in subscription policy payloads.
The system enforces the following rules:
"subscriptionType": "policy" always equals "shareResponsibility": true
"subscriptionType": "guardrail" always equals "shareResponsibility": false
This ensures backwards compatibility so that you can continue sending your existing policy payloads. However, user-provided values for the shareResponsibility parameter will be ignored, as they are now implicitly defined as part of the subscriptionType. See the below table for a summary of the behavior change.
"subscriptionType": "policy"
"shareResponsibility": true
"subscriptionType": "policy"
"shareResponsibility": true
"subscriptionType": "policy"
"shareResponsibility": false
"subscriptionType": "policy"
"shareResponsibility": true
"subscriptionType": "guardrail"
"shareResponsibility": true
After you complete the upgrade to 2026.2, connections will be enabled by default and you will see a banner to upgrade your integrations to connections. Follow the steps in the UI to complete the upgrade.
helm template <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --version 2026.2.0 -n <namespace> -f immuta-values.yaml \
--show-only charts/audit/templates/search-index-report-job.yaml | kubectl -n <namespace> apply -f -
kubectl -n <namespace> wait --for=condition=complete job/<release-name>-audit-search-index-report --timeout=5m
kubectl -n <namespace> logs job/<release-name>-audit-search-index-report
kubectl -n <namespace> delete job <release-name>-audit-search-index-report[SEARCH-INDEX-REPORT] Existing audit index for tenant <id>: <index> (alias <alias>). Add to your values file:
audit:
config:
searchIndexName: <index>
searchIndexAliasName: <alias>Upgrading with a migrated values file WITHOUT the keep annotation deletes the ingress resource and the load balancer, and there is no self-service recovery without DNS control. See the for guidance.
Learn about how the Snowflake integration works and what Immuta creates in your environment to administer Snowflake access controls directly on objects in Snowflake
Using the Snowflake connection, you can register a Snowflake integration for your Snowflake Enterprise account.
The sequence diagram below outlines the events that occur when an Immuta user wants to query a Snowflake table that has been registered as an Immuta data source.
Immuta utilizes connections to register and manage data from your entire Snowflake environment all at once. This approach simplifies data registration and allows Immuta to automatically monitor your Snowflake platform for changes. Data sources are then added or removed to reflect the current state of your data platform.
When a connection is first registered, Immuta will ask your application admin to provide the following:
The name of an Immuta system database in Snowflake that Immuta will control and create schemas (immuta_procedures, immuta_policies, and immuta_functions) in to contain policy definitions and user entitlements. This database will be created when you run the setup script.
A Snowflake role with the required privileges that the system account will use to maintain state of data objects between Snowflake and Immuta.
A set of Snowflake credentials to a system account with the to connect between Snowflake and Immuta. These credentials will be used to initially register all your as data objects. Immuta will also continue to use those credentials for scheduled , , and to orchestrate policies in Snowflake.
The application admin will then run the setup script in Snowflake, which will create the following:
The new Immuta system database to contain policy definitions and user entitlements.
A new system Snowflake role to orchestrate policies in Snowflake, which will be attached to the Snowflake system account.
When policies are applied to Snowflake objects, the following will be done in your Snowflake environment:
Subscription policies will require a new role to be created for each user, which will be granted access to the object in Snowflake. The role prefix is set on the . For example, if the user is jane.doe@immuta.com and if the role prefix is set to IMMUTA, the role will be IMMUTA_USER_jane.doe@immuta.com and granted access to the table.
Data policies will require Immuta to manage and apply and to Snowflake objects that are registered as Immuta data sources using the system Snowflake account and role.
After the setup and registration is complete, Immuta ingests and stores connection metadata in the Immuta metadata database. In the example below, the Immuta application administrator connects the database that contains marketing-data, research-data, and cs-data tables. Immuta registers these tables as data objects and stores the table metadata in the Immuta metadata database. Creating the connection does not impact any user's existing access in Snowflake until subscription policies are applied to the tables.
Beyond making the registration of your data more intuitive, connections provide more control. Instead of performing operations on individual schemas or tables, you can perform operations (such as object sync) at the connection level.
See the for details about connections and how to manage them. To configure your Snowflake connection, see the .
By default, the Snowflake integration is designed to be minimally invasive: if a table does not have policy sync enabled, users will still have access to it in Snowflake.
Immuta enforces read and write on Snowflake tables by granting access to the appropriate tables in Snowflake.
Once the connection is registered, this is what happens when a user applies a subscription policy to a Snowflake data source:
Immuta creates a role for the user querying the table in Snowflake, if one doesn't already exist. The role will be <IMMUTA>_USER_<username>.
Snowflake stores that role in its internal system catalog.
Immuta issues grants to that user's role in Snowflake to enforce policy. The provides an example of this policy enforcement.
You can author in Immuta to enforce fine-grained access controls on Snowflake data objects registered as Immuta data sources. For more details about how enforcement works, see the .
When a data policy is applied to a Snowflake data source in Immuta,
A data owner, data governor, or administrator or a in Immuta.
Immuta manages and applies and to Snowflake tables that are registered as Immuta data sources using the system Snowflake account and role.
A Snowflake user who is subscribed to the data source in Immuta queries the corresponding table directly in Snowflake and sees policy-enforced data.
See the integration support matrix on the for a list of supported data policy types in Snowflake.
See the for details about the Snowflake privileges granted to users when they are subscribed to a data source protected by a subscription policy.
The privileges the Snowflake integration requires align to the least privilege security principle. The table below describes each privilege required in Snowflake for the setup user or the system account user. The references to IMMUTA_DB , IMMUTA_WH, and IMMUTA_IMPERSONATOR_ROLE in the table can be replaced with what you chose for the name of your Immuta database, warehouse, and impersonation role when setting up the integration, respectively.
The following user actions spur various processes in the Snowflake integration so that Immuta data remains synchronous with data in Snowflake. The list below provides an overview of each process:
Data source created: Immuta registers data source metadata and stores that metadata in the Immuta metadata database.
: When a user account is mapped to Immuta, their metadata is stored in the metadata database.
User subscribed to a data source: When a user is added to a data source by a data owner or through a subscription policy, Immuta creates a role for that user (if a role for them does not already exist) and grants Snowflake privileges to their role.
The Snowflake integration allows users to author subscription and data policies to enforce access controls. See the corresponding pages for details about specific types of policies supported:
The Immuta Snowflake integration supports the following Snowflake feature.
: However, you cannot add a masking policy to an external table column while creating the external table in Snowflake because masking policies cannot be attached to virtual columns.
The Snowflake integration supports the following authentication methods to register a connection. The credentials provided must be for an account with the permissions listed in the .
Key pair: Users can authenticate with a .
Snowflake External OAuth: Users can authenticate with . For more information about this authentication option, see the .
The built-in Immuta IAM can be used as a complete solution for authentication and user entitlement. However, you can connect your existing identity management provider to Immuta to use that system for authentication and user entitlement instead. Each of the includes a set of configuration options that enable Immuta to communicate with the IAM system and map the users, permissions, groups, and attributes into Immuta.
For policies to impact the right users, the user account in Immuta must be mapped to the user account in Snowflake. You can ensure these accounts are mapped correctly in the following ways:
: If usernames in Snowflake align with usernames in the external IAM and those accounts align with an IAM attribute, you can enter that IAM attribute on the app settings page to automatically map user IDs in Immuta to Snowflake.
: You can manually map user IDs for individual users.
For guidance on connecting your IAM to Immuta, see the .
Excepted roles and users are assigned when the connection is registered, and no policies will apply to these users' queries, despite any Immuta policies enforced on the tables they are querying. Consequently, roles and users added to this list should be limited to service accounts.
Immuta excludes the listed roles and users from policies by wrapping all policies in a CASE statement that will check if a user is acting under one of the listed usernames or roles. If a user is on the list, then the policy will not be acted on the queried table. If the user is not, then the policy will be executed like normal. Immuta does not distinguish between role and username, so if you have a role and user with the exact same name, both the user and any user acting under that role will have full access to the data sources and no policies will be enforced for them.
Add service accounts to the excepted roles/users list so that Immuta subscription and data policies will not unintentionally impact their jobs.
When using both tables and their views as data sources, add the owner of the view in Snowflake as an excepted role/user. Otherwise, the backing table's policies will be applied to that view.
You can enable Snowflake tag ingestion so that Immuta will ingest Snowflake object tags from your Snowflake instance into Immuta and add them to the appropriate data sources. The Snowflake tags' key and value pairs will be reflected in Immuta as two levels: the key will be the top level and the value the second. As Snowflake tags are hierarchical, Snowflake tags applied to a database will also be applied to all of the schemas in that database, all of the tables within those schemas, and all of the columns within those tables. For example: If a database is tagged PII, all of the tables and columns in that database will also be tagged PII.
Snowflake tag ingestion supports two authentication methods:
Username and password
Key pair
To enable Snowflake tag ingestion, see the .
Credentials
If you want all Snowflake data sources to have Snowflake data tags ingested into Immuta, ensure the credentials provided on the for the external catalog feature can access all the data sources registered in Immuta. Any data sources the credentials do not have access to will not be tagged in Immuta. In practice, it is recommended to just use the same credentials for the and tag ingestion.
Caveats
Snowflake has some . If you manually refresh the governance page to see all tags created globally, users can experience a delay of up to two hours. However, if you run object sync or a health check to find where those tags are applied, the delay will not occur because Immuta will only refresh tags for those specific tables.
Snowflake workspaces are deprecated and are not supported with Snowflake table grants enabled, which is the default for all new connections.
If there are errors in generating or applying policies natively in Snowflake, the data source will be locked and only users on the and the credentials used to register the connection will be able to access the data.
Once a Snowflake connection is deactivated in Immuta, the user must remove the access that was granted in Snowflake. If that access is not revoked, users will be able to access the raw table in Snowflake.
Custom WHERE clause limitations
The Immuta Snowflake integration uses Snowflake governance features to let users query data natively in Snowflake. This means that Immuta also inherits some Snowflake limitations using correlated subqueries with and . These limitations appear when writing , but do not remove the utility of row-level policies.
Requirement for a custom WHERE policy: The Immuta system account must have SELECT privileges on all tables/views referenced in a subquery via the system Snowflake role created by the setup script. Reach out to your Immuta support professional if you do not know the role to grant privileges to.
Subquery limitations
Any subqueries that error in Snowflake will also error in Immuta.
Including one or more subqueries in the Immuta policy condition may cause errors in Snowflake. If an error occurs, it may happen during policy creation or at query-time. To avoid these errors, limit the number of subqueries, limit the number of JOIN operations, and simplify WHERE clause conditions.
For more information on the Snowflake subquery limitations see
Users will query data in Snowflake, using USE SECONDARY ROLES ALL, which allows them to use the privileges from all roles that have been granted to them including the <IMMUTA>_USER_<username> role and their current active primary role.
CREATE ROLE ON ACCOUNT WITH GRANT OPTION
Setup user
All
The setup user must create a ROLE for Immuta that will be used to manage the integration and policies once it has been initialized.
MANAGE GRANTS ON ACCOUNT
Setup user
All
The user registering the connection must be able to GRANT global privileges and access to objects within the Snowflake account. All privileges that are documented here must be granted to the system account user by the setup user manually or through the setup script.
ALL PRIVILEGES ON DATABASE IMMUTA_DB
ALL PRIVILEGES ON ALL SCHEMAS IN DATABASE IMMUTA_DB
USAGE ON FUTURE PROCEDURES IN SCHEMA IMMUTA_DB.IMMUTA_PROCEDURES
System account user
All
Immuta requires these privileges because Immuta must have full ownership of the Immuta database where Immuta objects are managed.
USAGE ON WAREHOUSE IMMUTA_WH
System account user
All
To make changes to state in the Immuta database, Immuta requires access to compute (a Snowflake warehouse). Some state changes are DDL operations, and others are DML and require compute.
IMPORTED PRIVILEGES ON DATABASE SNOWFLAKE
System account user
Audit
To ingest audit information from Snowflake, Immuta must have access to the SNOWFLAKE.ACCOUNT_USAGE.ACCESS_HISTORY view. See the for details.
APPLY MASKING POLICY ON ACCOUNT
APPLY ROW ACCESS POLICY ON ACCOUNT
System account user
Data policies
Immuta must be able to apply policies to objects throughout your organization's Snowflake account and query for existing policies on objects using the POLICY_REFERENCES .
USAGE on the external volume if registering Iceberg tables
System account user
Data policies on Iceberg tables
Immuta must have this privilege to apply data policies to Iceberg tables.
SELECT on all tables and views registered in Immuta
System account user
Identification and specialized masking policies that require fingerprinting
Immuta must have this privilege to run the necessary queries for on your data sources.
OWNERSHIP ON ROLE IMMUTA_IMPERSONATOR_ROLE
System account user
Impersonation
If impersonation is enabled, Immuta must be able to manage the Snowflake roles used for impersonation in order to manage the impersonation feature.
USAGE on all databases and schemas with registered data sources
REFERENCES on all tables and views registered in Immuta
System account user
Object sync
Immuta must be able to see metadata on securables to register them as data sources.
MANAGE GRANTS ON ACCOUNT or OWNERSHIP on the objects that Immuta will secure
System account user
Subscription policies
Immuta must be able to MANAGE GRANTS on objects throughout your organization's Snowflake account.
CREATE ROLE ON ACCOUNT
System account user
Subscription policies
Immuta must be able to create roles as targets for Immuta subscription policy permissions in your organization’s Snowflake account.
APPLY TAG ON ACCOUNT
System account user
Tag ingestion
To ingest table, view, and column tag information from Snowflake, Immuta must have this permission. Immuta reads from the TAG_REFERENCES .
IMPORTED PRIVILEGES ON DATABASE SNOWFLAKE
System account user
Tag ingestion
To ingest table, view, and column tag information from Snowflake, Immuta must have access to the SNOWFLAKE.ACCOUNT_USAGE.ACCESS_HISTORY view. See the for details.
USAGE ON DATABASE IMMUTA_DB
USAGE ON SCHEMA IMMUTA_DB.IMMUTA_PROCEDURES
USAGE ON SCHEMA IMMUTA_DB.IMMUTA_FUNCTIONS
PUBLIC role
All
Immuta has stored procedures and functions that are used for policy enforcement and do not expose or contain any sensitive information. These objects must be accessible by all users to facilitate the use and creation of policies or views to enforce Immuta policies in Snowflake.
SELECT ON IMMUTA_DB.IMMUTA_SYSTEM.ALLOW_LIST
PUBLIC role
All
Immuta retains a list of excepted roles and users when using the Snowflake integration. The roles and users in this list will be exempt from policies applied to tables in Snowflake to give organizations flexibility in case there are entities that should not be bound to Immuta policies in Snowflake (for example, a system or application role or user).
Subscription policy deleted: Immuta revokes privileges from the affected roles.
Data policy created or updated: Snowflake row access policies and column masking policies are applied to the Snowflake object to reflect the Immuta policy. See the Protecting data page for details about this process.
Data policy deleted: Immuta removes the policy from the Snowflake object.
User removed from a data source: Immuta revokes privileges from the user's role.
Materialized view
✅
✅
External table
✅
✅
Event table
✅
✅
Iceberg table
✅
✅
Dynamic table
✅
✅
You cannot add a masking policy to an external table column while creating the external table because a masking policy cannot be attached to a virtual column.
If you create an Immuta data source from a Snowflake view created using a select * from query, Immuta cannot get the column metadata because Snowflake views are not automatically updated based on backing table changes. To remedy this, you can create views that have the specific columns you want or you can CREATE AND REPLACE the view in Snowflake whenever the backing table is updated and manually run the object sync job on the data source page.
If a user is created in Snowflake after that user is already registered in Immuta, Immuta does not grant usage on the per-user role automatically - meaning Immuta does not govern this user's access without manual intervention. If a Snowflake user is created after that user is registered in Immuta, the user account must be disabled and re-enabled to trigger a sync of Immuta policies to govern that user. Whenever possible, Snowflake users should be created before registering those users in Immuta.
Snowflake tables from imported databases are not supported. Instead, create a view of the table and register that view as a data source.
Data sources created from connections cannot be deleted. To remove the Immuta-applied policies from a Snowflake table, remove the policies from the data source, then disable it. To remove the Immuta-managed policies from all Snowflake tables, deactivate the connection.
CREATE DATABASE ON ACCOUNT WITH GRANT OPTION
Setup user
All
The setup script this user runs creates an Immuta database in your organization's Snowflake account where all Immuta managed objects (UDFs, masking policies, row access policies, and user entitlements) will be written and stored.
Table
✅
✅
View
✅

✅
Run a same-version upgrade. Replace the content in angle brackets with your release name and the version of Immuta you're currently on (not the one you will upgrade to), respectively.
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version <your-current-immuta-version>Edit your immuta-values.yaml file and remove secure.ingress (or set secure.ingress: null) and set gateway.ingress.enabled: false.
gateway:
ingress:
enabled: falseRun an impact assessment for the guardrail policy migration to get a list of data sources that fall into one of the two outlined policy migration scenarios. The access criteria for any data sources listed under Scenario 2 (ACCESS CHANGES) in the report has become less restrictive, potentially leading to more users getting subscribed to those data sources after the upgrade. Determine whether to accept those changes or adjust those policies to be always required before upgrading Immuta. For guidance, see the second policy migration scenario. The sequence of commands below does not upgrade Immuta or run the full Helm chart; it only runs the temporary Kubernetes Job that generates a list of data sources affected by the guardrail policy migration and then deletes the Job.
helm template immuta oci://ocir.immuta.com/stable/immuta-enterprise --version 2026.2.0 -n <ns> -f immuta-values.yaml \
--show-only charts/secure/templates/guardrail-report-job.yaml | kubectl -n <ns> apply -f -
kubectl -n <ns> wait --for=condition=complete job/immuta-secure-guardrail-report --timeout=5m
kubectl -n <ns> logs job/immuta-secure-guardrail-report
kubectl -n <ns> delete job immuta-secure-guardrail-reportUpgrade to 2026.2. The kept ingress will be skipped, not deleted. During the migration, audit history queries are slower and audit writes pause for a few minutes. Do not interrupt the command, and do not run it a second time while the first is still running.
Replace the content in angle brackets with your release name.
Set a Helm timeout. The upgrade rebuilds indexes on the auditrecord table, and on a large table this takes longer than Helm’s default 5 minutes. If this default is not adjusted, when Helm times out it will mark the release as failed while the migration keeps running. Budget about 30 minutes for every 100 million rows in bometadata.auditrecord and pass it as --timeout.
Verify the pods are running and jobs are complete.
kubectl -n <ns> get pods # all Running / Completed
kubectl -n <ns> get jobs # all Complete, incl. onboarding-db-migrator and temporal-cleanup
kubectl -n <ns> get ingress # <release>-secure still present
kubectl -n <ns> get deploy <release>-gateway # 1/1 readyCut over the kept ingress backend to <release>-gateway, port 8000. Expect up to about 10 seconds of HTTP 503 at the cutover. The kept ingress will be unmanaged by Helm.
kubectl -n <ns> patch ingress <release>-secure --type=json -p '[
{"op":"replace","path":"/spec/rules/0/http/paths/0/backend/service/name","value":"<release>-gateway"},
{"op":"replace","path":"/spec/rules/0/http/paths/0/backend/service/port","value":{"number":8000}}
]'Confirm that traffic transits the gateway.
kubectl -n <ns> logs deploy/<release>-gateway --since=1m | grep -c DownstreamStatusThe ingress is now unmanaged by Helm and will keep working indefinitely; future helm upgrade runs will not affect it. If you later want a chart-managed ingress, complete the steps outlined in Method B at any time.
Edit the immuta-values.yaml file and move the secure.ingress values to gateway.ingress. See the Ingress configuration guide for instructions specific to your ingress controller. For example,
gateway:
ingress:
enabled: true
hostname: immuta.example.com
ingressClassName: alb
annotations: { ...your ALB annotations, cert ARN, etc... }Run an impact assessment for the guardrail policy migration to get a list of data sources that fall into one of the two outlined policy migration scenarios. The access criteria for any data sources listed under Scenario 2 (ACCESS CHANGES) in the report has become less restrictive, potentially leading to more users getting subscribed to those data sources after the upgrade. Determine whether to accept those changes or adjust those policies to be always required before upgrading Immuta. For guidance, see the second policy migration scenario. The sequence of commands below does not upgrade Immuta or run the full Helm chart; it only runs the temporary Kubernetes Job that generates a list of data sources affected by the guardrail policy migration and then deletes the Job.
helm template immuta oci://ocir.immuta.com/stable/immuta-enterprise --version 2026.2.0 -n <ns> -f immuta-values.yaml \
--show-only charts/secure/templates/guardrail-report-job.yaml | kubectl -n <ns> apply -f -
kubectl -n <ns> wait --for=condition=complete job/immuta-secure-guardrail-report --timeout=5m
kubectl -n <ns> logs job/immuta-secure-guardrail-report
kubectl -n <ns> delete job immuta-secure-guardrail-reportUpgrade to 2026.2. A second load balancer is provisioned for the new <release>-gateway ingress while the old one keeps serving. During the migration, audit history queries are slower and audit writes pause for a few minutes. Do not interrupt the command, and do not run it a second time while the first is still running.
Replace the content in angle brackets with your release name.
Set a Helm timeout. The upgrade rebuilds indexes on the auditrecord table, and on a large table this takes longer than Helm’s default 5 minutes. If this default is not adjusted, when Helm times out it will mark the release as failed while the migration keeps running. Budget about 30 minutes for every 100 million rows in bometadata.auditrecord and pass it as --timeout.
Validate the new load balancer directly by its DNS name, and then flip your DNS record (lower TTL beforehand). Both load balancers serve during the transition; rollback is a DNS flip.
Delete the kept legacy ingress.
Run an impact assessment for the guardrail policy migration to get a list of data sources that fall into one of the two outlined policy migration scenarios. The access criteria for any data sources listed under Scenario 2 (ACCESS CHANGES) in the report has become less restrictive, potentially leading to more users getting subscribed to those data sources after the upgrade. Determine whether to accept those changes or adjust those policies to be always required before upgrading Immuta. For guidance, see the second policy migration scenario. The sequence of commands below does not upgrade Immuta or run the full Helm chart; it only runs the temporary Kubernetes Job that generates a list of data sources affected by the guardrail policy migration and then deletes the Job.
helm template immuta oci://ocir.immuta.com/stable/immuta-enterprise --version 2026.2.0 -n <ns> -f immuta-values.yaml \
--show-only charts/secure/templates/guardrail-report-job.yaml | kubectl -n <ns> apply -f -
kubectl -n <ns> wait --for=condition=complete job/immuta-secure-guardrail-report --timeout=5m
kubectl -n <ns> logs job/immuta-secure-guardrail-report
kubectl -n <ns> delete job immuta-secure-guardrail-reportUpgrade Immuta to the latest release. During the migration, audit history queries are slower and audit writes pause for a few minutes. Do not interrupt the command, and do not run it a second time while the first is still running.
Replace the content in angle brackets with your release name.
Set a Helm timeout. The upgrade rebuilds indexes on the auditrecord table, and on a large table this takes longer than Helm’s default 5 minutes. If this default is not adjusted, when Helm times out it will mark the release as failed while the migration keeps running. Budget about 30 minutes for every 100 million rows in bometadata.auditrecord and pass it as --timeout.
Policy 1 (always required): Subscribe users when user is a member of group Finance
Policy 2 (always required): Subscribe users when user is a member of group Marketing
Policy 3 (always required): Subscribe users when user is a member of group HR
Policy 1 (grant policy): Subscribe users when user is a member of group Finance
Policy 1.1 (guardrail policy): Prevent users from gaining access unless user is a member of group Finance
Policy 2 (grant policy): Subscribe users when user is a member of group Marketing
Merged policy logic
Users will be subscribed to the data source
when they are member of group Finance AND Marketing AND HR.
Users will be subscribed to the data source when they are (a member of group Finance OR Marketing OR HR)
AND
(a member of group Finance AND Marketing AND HR).
In this scenario, the final access criteria remains the same: A user will not get subscribed to this data source unless they are a member of all the three required groups. However, in order for nobody to lose access, the migration turns each always required policy into two policies — one grant policy and one corresponding guardrail policy — ultimately resulting in a higher number of policies than before the upgrade.
Policies
Policy 1 (shared responsibility): Subscribe users when user is a member of group Sales
Policy 2 (always required): Subscribe users when user is a member of group Manufacturing
Policy 1 (grant policy): Subscribe users when user is a member of group Sales
Policy 2 (grant policy): Subscribe users when user is a member of group Manufacturing
Policy 2.1 (guardrail policy): Prevent users from gaining access unless user is a member of group Manufacturing
Merged policy logic
Users will be subscribed they are a member of group Sales AND Manufacturing.
In this example, the policies are combined with AND because there is an always required policy in play.
Users will be subscribed to this data source when they are (a member of group Sales OR Manufacturing) AND (a member of group Manufacturing).
In this scenario, the final access criteria does not remain the same: A user will now get subscribed to this data source as long as they are a member of group Manufacturing; being a member of group Sales is no longer a hard requirement. The access criteria for this data source has become less restrictive, potentially leading to more users getting subscribed to this data source after the upgrade.
Given that this scenario leads to a change in access, you have the following options:
Do nothing and accept the change in behavior for affected data sources
Change the shared responsibility policy into an always required policy, which will turn the data source into a scenario 1 migration case instead.
Contact your Immuta representative if you would like receive guidance in making the right decision for your case.
audit:
config:
searchIndexName: <INDEX-NAME>
searchIndexAliasName: <INDEX-ALIAS>Nobody gets subscribed, but if there is any grant policy trying to give access to someone that is not in Finance, those users will be blocked
"subscriptionType": "guardrail"
"shareResponsibility": false
"subscriptionType": "guardrail"
"shareResponsibility": false
"subscriptionType": "guardrail"
"shareResponsibility": false
secure:
ingress:
enabled: true
hostname: <immuta-fqdn>
ingressClassName: nginx
annotations:
nginx.ingress.kubernetes.io/proxy-body-size: '64m'
helm.sh/resource-policy: "keep"secure:
ingress:
enabled: true
hostname: <immuta-fqdn>
ingressClassName: nginx
annotations:
nginx.ingress.kubernetes.io/proxy-body-size: '64m'
helm.sh/resource-policy: "keep"Upgrading with a migrated values file WITHOUT the keep annotation deletes the ingress resource and the load balancer, and there is no self-service recovery without DNS control.
The keep annotation only works through values plus a Helm upgrade. Annotating the live object with kubectl does not work.
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version <your-current-immuta-version>Policies
If external-dns manages records by ingress hostname, two ingresses claiming the same host will fight. Use a temporary hostname for validation or an external-dns exclusion annotation until the flip.
Learn about how the Databricks Unity Catalog integration works and what Immuta creates in your environment to administer access controls directly on objects in Databricks Unity Catalog
Using the Databricks Unity Catalog connection, you can register a Databricks Unity Catalog integration to register data sources, apply policies to securables, audit user queries, and use other supported Immuta features.
The sequence diagram below outlines the events that occur when an Immuta user wants to query a Databricks Unity Catalog table that has been registered as an Immuta data source.
Immuta’s integration with Unity Catalog allows you to enforce fine-grained access controls on Unity Catalog securable objects with Immuta policies. Instead of manually creating UDFs or granting access to each table in Databricks, you can author your policies in Immuta and have Immuta manage and orchestrate Unity Catalog access-control policies on your data in Databricks clusters or SQL warehouses.
Immuta utilizes connections to register and manage data from your entire Databricks Unity Catalog environment all at once. This approach simplifies data registration and allows Immuta to automatically monitor your Databricks Unity Catalog platform for changes. Data sources are then added or removed to reflect the current state of your data platform.When a connection is first registered, Immuta will ask your application admin to provide the following:
The name of an Immuta system catalog in Databricks Unity Catalog that Immuta will control and create schemas in to contain policy definitions and user entitlements.
A set of Databricks credentials to a service principal with the to manage all data protected by Immuta. These credentials will be used to initially register all your as data objects. Immuta will also continue to use those credentials for scheduled , , and to orchestrate policies in Databricks Unity Catalog.
The application admin will then run the setup script in Databricks Unity Catalog, which will create the following:
The new Immuta system catalog to contain the immuta_system schema with internal Immuta data and the immuta_policies_n schema with the Immuta policy UDFs
After the setup and registration is complete, Immuta ingests and stores connection metadata in the Immuta metadata database. In the example below, the Immuta application administrator connects the database that contains marketing-data, research-data, and cs-data tables. Immuta registers these tables as data objects and stores the view metadata in the Immuta metadata database. Creating the connection does not impact any user's existing access in Databricks Unity Catalog until policy sync is enabled for those tables.
Beyond making the registration of your data more intuitive, connections provide more control. Instead of performing operations on individual schemas or tables, you can perform operations (such as object sync) at the connection level.
See the for details about connections and how to manage them. To configure your Databricks Unity Catalog integration and register data, see the .
When policies require changes to be pushed to Unity Catalog, Immuta updates the internal tables in the immuta_system schema with the updated policy information. If necessary, new UDFs are pushed to replace any out-of-date policies in the immuta_policies_n schemas and any row filters or column masks are updated to point at the new policies. Many of these operations require compute on the configured Databricks cluster or SQL warehouse, so compute must be available for these policies to succeed.
Immuta enforces read and write on Databricks Unity Catalog data sources by granting access to the appropriate securables in Databricks.
Once the connection is registered, this is what happens when a user applies a subscription policy to a Databricks Unity Catalog data source:
Immuta determines which users should have access based on the subscription policy.
If an appropriate Immuta-managed Databricks group does not already exist, Immuta creates one at the Databricks account level.
Immuta grants the required Unity Catalog privileges on the catalog, schema, or table to that Immuta-managed group using the Unity Catalog API.
Immuta adds the entitled users to the group.
Immuta-managed groups are created at the account level and not assigned to any particular workspace.
When Immuta creates Databricks Unity Catalog groups to enforce access controls, the group naming convention differs slightly based on whether access was granted by an automatic subscription policy or the group was manually subscribed to the data source.
Automatic subscription of a user or Immuta group: The group name comprises the Immuta external ID, the connectionKey, and the policy hash.
Naming convention: IMMUTA_<Immuta external ID>_<connectionKey>_<policy hash>
Example: IMMUTA_123456789_UnityCatalogConnection_ce86d2f5f86471f66fcd08741d0eb0f4447a6e73a005094c9da07753a8d630f7
You can author in Immuta to enforce fine-grained access controls on Databricks Unity Catalog data sources. For more details abour how enforcement works, see the .
When a data policy is applied to a Databricks Unity Catalog data source in Immuta,
A data owner, data governor, or administrator , or a in Immuta.
Immuta generates and applies SQL user-defined functions (UDFs) in Databricks to enforce the configured policy.
Row-level security is enforced by applying SQL UDFs that filter rows returned to the querying user.
Column-level security
See the integration support matrix on the for a list of supported data policy types for Databricks Unity Catalog.
See the for details about the Databricks Unity Catalog privileges granted to users when they are subscribed to a data source protected by a subscription policy.
The privileges the Databricks Unity Catalog integration requires align to the least privilege security principle. The table below describes each privilege required in Databricks Unity Catalog for the setup user and the Immuta service principal.
The following user actions spur various processes in the Databricks Unity Catalog integration so that Immuta data remains synchronous with data in Databricks Unity Catalog:
Data source created: Immuta registers data source metadata and stores that metadata in the Immuta metadata database.
Data source deleted: Immuta deletes the data source metadata from the metadata database and removes subscription policies from that table.
User account is mapped to Immuta: When a user account is mapped to Immuta, their metadata is stored in the metadata database.
If you have , the ingestion of these catalogs (and their securables) into Immuta may get skipped. Ingestion for catalogs where the workspace associated with the Immuta service principal has read-only access are skipped because Immuta will be blocked from enforcing policies on such catalogs, even if the Immuta service principal were given explicit privilege grants (e.g., MANAGE) on the catalog.
See the following table to determine whether Immuta ingests catalogs with each binding:
When enabling Unity Catalog support in Immuta, the catalog for all Databricks data sources will be updated to point at the default hive_metastore catalog. Internally, Databricks exposes this catalog as a proxy to the workspace-level Hive metastore that schemas and tables were kept in before Unity Catalog. Since this catalog is not a real Unity Catalog catalog, it does not support any Unity Catalog policies. Therefore, Immuta will ignore any data sources in the hive_metastore in any Databricks Unity Catalog integration, and policies will not be applied to tables there.
However, with you can use hive_metastore and enforce subscription and data policies with the .
The Unity Catalog integration supports the following policy types:
Conditional masking
Constant
The Databricks Unity Catalog integration supports the following authentication methods to configure the integration and create data sources:
Personal access token (PAT): This is the access token for the Immuta service principal. This service principal must have the metastore privileges listed in the section for the metastore associated with the Databricks workspace. If this token is configured to expire, update this field regularly for the integration to continue to function.
OAuth machine-to-machine (M2M): Immuta uses the to integrate with , which allows Immuta to authenticate with Databricks using a client secret. Once Databricks verifies the Immuta service principal’s identity using the client secret, Immuta is granted a temporary OAuth token to perform token-based authentication in subsequent requests. When that token expires (after one hour), Immuta requests a new temporary token. See the for more details.
The built-in Immuta IAM can be used as a complete solution for authentication and user entitlement. However, you can connect your existing identity management provider to Immuta to use that system for authentication and user entitlement instead. Each of the includes a set of configuration options that enable Immuta to communicate with the IAM system and map the users, permissions, groups, and attributes into Immuta.
For policies to impact the right users, the user account in Immuta must be mapped to the user account in Databricks Unity Catalog. You can ensure these accounts are mapped correctly in the following ways:
: If usernames in Databricks Unity Catalog align with usernames in the external IAM and those accounts align with an IAM attribute, you can enter that IAM attribute on the app settings page to automatically map user IDs in Immuta to Databricks Unity Catalog.
: You can manually map user IDs for individual users.
For guidance on connecting your IAM to Immuta, see the .
The Databricks group configured as the policy exemption group in Immuta will be exempt from Immuta data policy enforcement. This account-level group is created and managed in Databricks, not in Immuta. This group does not need to be assigned to a Databricks workspace.
If you have service or system accounts that need to be exempt from masking and row-level policy enforcement, add them to an account-level group in Databricks and include this group name in the Databricks Unity Catalog configuration in Immuta. Then, group members will be excluded from having data policies applied to them when they query Immuta-protected tables in Databricks.
Typically, service or system accounts that perform the following actions are added to an exemption group in Databricks:
Automated queries
ETL
Report generation
If you have multiple groups that must be exempt from data policies, add each group to a single group in Databricks that you then set as the policy exemption group in Immuta.
The service principal used to register data sources in Immuta will be automatically added to the exemption group for the Databricks securables it registers. Consequently, accounts added to the exemption group and used to register data sources in Immuta should be limited to service accounts.
You can enable tag ingestion to allow Immuta to ingest Databricks Unity Catalog table and column tags so that you can use them in Immuta policies to enforce access controls. When you enable this feature, Immuta uses the credentials and connection information from the Databricks Unity Catalog integration to pull tags from Databricks and apply them to data sources as they are registered in Immuta. If Databricks data sources preexist the Databricks Unity Catalog tag ingestion enablement, those data sources will automatically sync to the catalog and tags will apply.
Immuta checks for changes to tags in Databricks and syncs Immuta data sources to those changes every hour by default. Immuta's tag ingestion process has a delta logic in order to establish all resources that have had a tag or description change inside Databricks Unity Catalog within a given timeframe to reduce excessive processing time and reduce compute cost.
Once external tags are applied to Databricks data sources, those tags can be used to create and .
To enable Databricks Unity Catalog tag ingestion, see the .
After making changes to tags in Databricks, you can so that the changes immediately apply to the data sources in Immuta. Otherwise, tag changes will automatically sync within a one hour timeframe. Please note that you may see this timeframe being exceeded in cases where Immuta has to process a lot of tag changes.
When syncing data sources to Databricks Unity Catalog tags, Immuta pulls the following information:
Table tags: These tags apply to the table and appear on the data source details tab. Databricks tags' key and value pairs are reflected in Immuta as a hierarchy with each level separated by a . delimiter. For example, the Databricks Unity Catalog tag Location: US would be represented as Location.US in Immuta.
Column tags: These tags are applied to data source columns and appear on the columns listed for the data source. Databricks tags' key and value pairs are reflected in Immuta as a hierarchy with each level separated by a . delimiter. For example, the Databricks Unity Catalog tag Location: US
Only tags that apply to Databricks data sources in Immuta are available to build policies in Immuta. Immuta will not pull tags in from Databricks Unity Catalog unless those tags apply to registered data sources.
Cost implications: Tag ingestion in Databricks Unity Catalog requires compute resources. Therefore, having many Databricks data sources or frequently manually syncing data sources to Databricks Unity Catalog may incur additional costs.
Databricks Unity Catalog tag ingestion only supports tenants with fewer than 10,000 data sources registered.
Direct group memberships: A principal can be a member of up to 1,500 groups.
Unity Catalog privileges per object: Databricks limits privileges to 4,000 privileges for parent objects and 1,000 privileges for non-parent objects.
Groups per account: Databricks has a limit of 250,000 groups for Databricks customers using Account SCIM 2.1. All other Databricks environments are subject to a 5,000 group limit.
Row access policies with more than 1023 columns are unsupported. This is an underlying limitation of UDFs in Databricks. Immuta will only create row access policies with the minimum number of referenced columns. This limit will therefore apply to the number of columns referenced in the policy and not the total number in the table.
If a registered data source is owned by a Databricks group at the table level, then the Unity Catalog integration cannot apply data masking policies to that table in Unity Catalog.Therefore, set all table-level ownership on your Unity Catalog data sources to an individual user or service principal instead of a Databricks group. Catalogs and schemas can still be owned by a Databricks group, as ownership at that level doesn't interfere with the integration.
The following features are currently unsupported:
Immuta project workspaces
Multiple IAMs on a single cluster
Row filters and column masking policies on the following object types:
Functions
Immuta's Amazon S3 integration allows users to apply to data in S3 to restrict what prefixes, buckets, or objects users can access. To enforce access controls on this data, Immuta creates S3 grants that are administered by S3 Access Grants, an AWS feature that defines access permissions to data in S3.
No location is registered in your AWS Access Grants instance before configuring the integration in Immuta.
Enable AWS IAM Identity Center (IDC) (recommended): is the best approach for user provisioning because it treats users as users, not users as roles. Consequently, access controls are enforced for the querying user, nothing more. This approach eliminates over-provisioning and permits granular access control. Furthermore, IDC uses trusted identity propagation, meaning AWS propagates a user's identity wherever that user may operate within the AWS ecosystem. As a result, a user's identity always remains known and consistent as they navigate across AWS services, which is a key requirement for organizations to properly govern that user. Enabling IDC does not impact any existing access controls; it is additive. Immuta will manage the GRANTs for you using IDC if it is enabled and configured in Immuta. See the
USAGE ON FUTURE FUNCTIONS IN SCHEMA IMMUTA_DB.IMMUTA_FUNCTIONS
USAGE ON SCHEMA IMMUTA_DB.IMMUTA_SYSTEM
SELECT ON IMMUTA_DB.IMMUTA_SYSTEM.USER_PROFILE
Policy 2.1 (guardrail policy): Prevent users from gaining access unless user is a member of group Marketing
Policy 3 (grant policy): Subscribe users when user is a member of group HR
Policy 3.1 (guardrail policy): Prevent users from gaining access unless user is a member of group HR
helm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0 --timeout 3hhelm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0 --timeout 3hhelm upgrade <release-name> oci://ocir.immuta.com/stable/immuta-enterprise --values immuta-values.yaml --version 2026.2.0 --timeout 3hUsers who are no longer entitled to access the data source are removed from the group, causing them to lose access to the securable object.
Manual subscription of an Immuta group: The group name comprises the Immuta external ID, the connectionkey, and the Immuta group name.
Naming convention: IMMUTA_<Immuta external ID>_<connectionKey>_MANUAL_<group name>
Example: IMMUTA_123456789_UnityCatalogConnection_MANUAL_Research
A Databricks user who is subscribed to the data source in Immuta queries the corresponding table directly in Databricks and the SQL UDFs are evaluated during query execution, ensuring that only authorized rows and unmasked column values are returned.
This privilege allows the setup user to create an Immuta-owned catalog and tables.
Metastore admin
Setup user
This privilege is required only if enabling query audit, which requires granting access to system tables to the Immuta service principal. To grant access, a user that is both a metastore admin and an account admin must grant USE and SELECT permissions on the system schemas to the service principal. See for more details.
Workspace admin
Immuta service principal
This privilege allows Immuta to create and manage Databricks groups to enforce access controls. Immuta-managed groups are created at the account level and not assigned to any particular workspace.
USE CATALOG and MANAGE on all catalogs containing securables registered as Immuta data sources
USE SCHEMA on all schemas containing securables registered as Immuta data sources
Immuta service principal
These privileges allow the service principal to ingest catalogs and determine if they have specific workspace-catalog binding behavior defined. These privileges also allow the service principal to apply row filters and column masks on the securable.
MODIFY and SELECT on all securables registered as Immuta data sources
Immuta service principal
These privileges allow the service principal to apply row filters and column masks on the securable. Additionally, they are required for to run on the securable.
OWNER on the Immuta catalog
Immuta service principal
The Immuta service principal must own the catalog Immuta creates during setup that stores the Immuta policy information. The Immuta setup script grants ownership of this catalog to the Immuta service principal when you configure the integration.
USE CATALOG on the system catalog
USE SCHEMA on the system.access and system.query schemas
Immuta service principal
These privileges allow Immuta to audit user queries in Databricks Unity Catalog.
databricks_pii_access group
Immuta service principal
This membership allows Immuta to see the query text for Databricks Unity Catalog query audit.
USE CATALOG on the system catalog
USE SCHEMA on the system.access schema
SELECT
Immuta service principal
These privileges allow Immuta to ingest and apply Databricks Unity Catalog tags to Immuta data sources.
User subscribed to a data source by an automatic subscription policy: Immuta creates a group for the affected users (if a group for them does not already exist) and grants Databricks privileges on the data object to that group.
Automatic subscription policy applied to or updated on a data source: Immuta calculates the users and data sources affected by the policy change and grants or revokes privileges on the Databricks Unity Catalog object by adding or removing users from the Immuta-created group in Databricks.
Subscription policy deleted: Immuta calculates the users and Databricks groups affected by the policy and revokes privileges on the Databricks Unity Catalog object by removing users from the Immuta-created group in Databricks. If there are no longer any members of an Immuta-created group in Databricks, that group is deleted by Immuta.
User manually added to or removed from a data source: Immuta provisions access in these scenarios by granting or revoking Databricks access to the securable object directly from the user.
User added to a data source by a data owner: Immuta grants Databricks privileges on the data object directly to that user.
User removed from a data source: If the user was previously subscribed to the data source through an automatic subscription policy, Immuta removes the user from the Immuta-created group in Databricks. If the user was previously manually added to the data source by a data owner, Immuta revokes the Databricks privileges from the user.
❌
Materialized view
✅
✅
Metric views
✅
❌
Streaming table
✅
✅
External table
✅
✅
Foreign table
✅
✅
Volumes (external and managed)
✅
❌
Models
✅
❌
Functions
✅
❌
Delta Shares
✅
Supported with caveats
Custom masking
Hashing
Null (including on ARRAY, MAP, and STRUCT type columns)
Regex: You must use the global regex flag (g) when creating a regex masking policy in this integration. You cannot use the case insensitive regex flag (i) when creating a regex masking policy in this integration. See the limitations section for examples.
Rounding (date and numeric rounding)
Matching (only show rows where)
Custom WHERE
Never
Where user
Where value in column
Minimization
Time-based restrictions
Location.USTable comments field: This content appears as the data source description on the data source details tab.
Column comments field: This content appears as column descriptions on the columns tab.
If you disable table grants, Immuta revokes the grants. Therefore, if users had access to a table before enabling Immuta, they’ll lose access.
If multiple Immuta tenants are connected to your Databricks environment, you must create a separate Immuta catalog for each of those tenants during configuration. Having multiple Immuta tenants use the same Immuta catalog causes failures in policy enforcement.
You must use the global regex flag (g) when creating a regex masking policy in this integration, and you cannot use the case insensitive regex flag (i) when creating a regex masking policy in this integration. See the examples below for guidance:
regex with a global flag (supported): /^ssn|social ?security$/g
regex without a global flag (unsupported): /^ssn|social ?security$/
regex with a case insensitive flag (unsupported): /^ssn|social ?security$/gi
regex without a case insensitive flag (supported): /^ssn|social ?security$/g
Models
Views
Volumes
Mixing masking policies on the same column
R and Scala cluster support
Scratch paths
User impersonation
Policy enforcement on raw Spark reads
Python UDFs for advanced masking functions
Direct file-to-SQL reads
Data policies (except for masking with NULL) on ARRAY, MAP, or STRUCT type columns
Shallow clones
Account admin
Setup user
This privilege allows the setup user to grant the Immuta service principal the necessary permissions to orchestrate Unity Catalog access controls and maintain state between Immuta and Databricks Unity Catalog.
CREATE CATALOG on the Unity Catalog metastore
Table
✅
✅
View
Open access with no bindings
✅
Read-only isolated access
❌
Read and write isolated access


Setup user
✅
✅
APPLICATION_ADMIN Immuta permission to configure the integration
CREATE_S3_DATASOURCE Immuta permission to register S3 prefixes
The AWS account credentials or optional AWS IAM role you provide Immuta to configure the integration must
have the to create locations and issue grants:
accessgrantslocation resource:
s3:CreateAccessGrant
Follow AWS documentation to create an Access Grants instance using the S3 console, AWS CLI, AWS SDKs, or the REST API. AWS supports one Access Grants instance per region per AWS account.
Follow the instructions at the top of the "Register a location" page in AWS documentation to create an AWS IAM role and edit the trust policy to give the S3 Access Grants service principal access to this role in the resource policy file. You will add this role to your integration configuration in Immuta so that Immuta can register this role with your Access Grants location. The policy should include at least the following permissions, but might need additional permissions depending on other local setup factors. An example trust policy is provided below.
sts:AssumeRole
sts:SetSourceIdentity
Follow the instructions at the top of the "Register a location" page in AWS documentation to create an IAM policy with the following permissions, and attach the policy to the IAM role you created to grant the permissions to the role. The policy should include the following permissions. An example policy is provided below.
s3:GetObject
s3:GetObjectVersion
s3:GetObjectAcl
s3:GetObjectVersionAcl
s3:ListMultipartUploadParts
s3:PutObject
s3:PutObjectAcl
s3:PutObjectVersionAcl
s3:DeleteObject
s3:DeleteObjectVersion
s3:AbortMultipartUpload
s3:ListBucket
s3:ListAllMyBuckets
If you use server-side encryption with AWS Key Management Service (AWS KMS) keys to encrypt your data, the following permissions are required for the IAM role in the policy. If you do not use this feature, do not include these permissions in your IAM policy:
kms:Decrypt
kms:GenerateDataKey
Opt to create an AWS IAM role that Immuta can use to create Access Grants locations and issue grants. This role must have the S3 permissions listed in the permissions section. An example policy is provided below.
If you use AWS IAM Identity Center, associate your IAM Identity Center instance with your S3 Access Grants instance. Then add the permissions listed in the sample policy below to your IAM policy, and attach the policy to the IAM role you created to grant the permissions to the role.
In Immuta, click App Settings in the navigation menu and click the Integrations tab.
Click + Add Integration.
Select Amazon S3 from the dropdown menu and click Continue Configuration.
Complete the connection details fields, where
Friendly Name is a name for the integration that is unique across all Amazon S3 integrations configured in Immuta.
AWS Account ID is the ID of your AWS account.
AWS Region is the AWS region to use.
S3 Access Grants Location IAM Role ARN is the role the S3 Access Grants service assumes to vend credentials to the grantee. When a grantee accesses S3 data, the Access Grants service attaches session policies and assumes this role in order to vend credentials scoped to a prefix or bucket to the grantee. This role needs full access to all paths under the S3 location prefix.
Select your authentication method:
Automatically discover AWS credentials: Searches and obtains credentials using the . This method requires a configured . Contact your Immuta representative to customize your deployment and set up an IAM role for a service account that can give Immuta the credentials to set up the integration. Then, complete the steps below.
Access using access key and secret access key: Provide your AWS Access Key ID and AWS Secret Access Key.
Click Verify Credentials.
Click Next to review and confirm your connection information, and then click Complete Setup.
Follow the Create an S3 data source guide to register prefixes in Immuta.
To create an S3 data source using the API, see the Create and manage an Amazon S3 data source API guide.
You can edit the following settings for an existing Amazon S3 integration on the app settings page:
friendly name
authentication type and values (access key, secret, and role)
To edit settings for an existing integration via the API, see the Configure an Amazon S3 integration API guide.
Requirements: USER_ADMIN Immuta permission and either the GOVERNANCE or CREATE_S3_DATASOURCE Immuta permission
Build read or write subscription policies in Immuta to enforce access controls.
Map AWS IAM principals to each Immuta user to ensure Immuta properly enforces policies:
Click Identities and select Users in the navigation menu.
Navigate to the user's page and click the more actions icon next to their username.
Select Change S3 User or AWS IAM Role from the dropdown menu.
Use the dropdown menu to select the User Type. Then complete the S3 field. User and role names are case-sensitive. See the for details.
: Only a single Immuta user can be mapped to an IAM role. This restriction prohibits enforcing policies on AWS users who could assume that role. Therefore, if using role principals, create a new user in Immuta that represents the role so that the role then has the permissions applied specifically to it.
Click Save.
See the for details about supported principals.
Requirement: User must be subscribed to the data source in Immuta
Request access to Amazon S3 data through S3 Access Grants. If you're accessing S3 data through one of the supported S3 Access Grants integrations (such as Amazon EMR on EC2), that application will make this request on your behalf, so you can skip this step.
Immuta's Amazon S3 integration allows users to apply subscription policies to data in S3 to restrict what prefixes, buckets, or objects users can access. To enforce access controls on this data, Immuta creates S3 grants that are administered by S3 Access Grants, an AWS feature that defines access permissions to data in S3.
With this integration, users can avoid
hand-writing AWS IAM policies
managing AWS IAM role limits
manually tracking what user or role has access to what files in AWS S3 and verifying those are consistent with intent
To enforce controls on S3 data, Immuta interacts with several S3 Access Grants components:
Access Grants instance: An Access Grants instance is a logical container for individual grants that specify who can access what level of data in S3 in your AWS account and region. AWS supports one Access Grants instance per region per AWS account.
Location: A location specifies what data the Access Grants instance can grant access to. For example, registering a location with a scope of s3:// allows Access Grants to manage access to all S3 buckets in that AWS account and region, whereas setting the bucket s3://research-data as the scope limits Access Grants to managing access to that single bucket for that location. When you configure the S3 integration in Immuta, you specify a location's scope and IAM assumed role, and Immuta registers the location in your Access Grants instance and associates it with the provided IAM role for you. Each S3 integration you configure in Immuta is associated with one location, and Immuta manages all grants in that location. Therefore, grants cannot be manually created by users in an Access Grants instance location that Immuta has registered and manages. During data source registration, this location scope is prepended to the data source prefixes to build the final path used to grant or revoke access to that data in S3. For example, a location scope of s3://research-data would be prepended to the data source prefix /demographics to generate a final path of s3://research-data/demographics.
Individual grants: Individual permission grants in S3 Access Grants specify the identity that can access the data, the access level, and the location of the S3 data. Immuta creates a grant for each user subscribed to a prefix, bucket, or object by interacting with the Access Grants API. Each grant has its own ID and gives the user or role principle access to the data.
IAM assumed role: This is an IAM role you create in S3 that has full access to all prefixes, buckets, and objects in the Access Grants location registered by Immuta. This IAM role is used to vend temporary credentials to users or applications. When a grantee requests temporary credentials, the S3 Access Grants service assumes this role to vend credentials scoped to the prefix, bucket, or object specified in the grant to the grantee. The grantee then uses these credentials to access S3 data. When configuring the integration in Immuta, you specify this role, and then Immuta associates this role with the registered location in the Access Grants instance.
Temporary credentials: These just-in-time access credentials provide access to a prefix, bucket, or object with a permission level of READ or READWRITE in S3. When a user or application requests temporary credentials to access S3 data, the S3 Access Grants instance evaluates the request against the grants Immuta has created for that user. If a matching grant exists, S3 Access Grants assumes the IAM role associated with the location of the matching grant and scopes the permissions of the IAM session to the S3 prefix, bucket, or object specified by the grant and vends these temporary credentials to the requester. These credentials have a default timeout of 1 hour, but .
The diagram below illustrates how these S3 Access Grants components interact.
For more details about these Access Grants concepts, see the S3 Access Grants documentation.
After an administrator creates an Access Grants instance and an assumed IAM role in their AWS account, an application administrator configures the Amazon S3 integration in Immuta. During configuration, the administrator provides the following connection information so that Immuta can create and register a location in that Access Grants instance:
AWS account ID and region
ARN for the existing Access Grants instance
ARN for the assumed IAM role
When Immuta registers this location, it associates the assumed IAM role with the location. This allows the IAM role to create temporary credentials with access scoped to a particular S3 prefix, bucket, or object in the location. The IAM role you create for this location must have all the object- and bucket-level permissions listed in the set up S3 Access Grants instance section on all buckets and objects in the location; if it is missing permissions, the IAM role will not be able to grant those missing permissions to users or applications requesting temporary credentials.
In the example below, an application administrator registers the following location prefix and IAM role for their Access Grants instance in AWS account 123456:
Location path: s3://. This path allows a single Amazon S3 integration to manage all objects in S3 in that AWS account and region. Data owners can scope down access further when registering specific S3 prefixes and applying policies.
Location IAM role: The arn:aws:iam::123456:role/access-grants-role IAM role will be used to vend temporary credentials to users and applications.
Immuta registers this location and associated IAM role in the user's Access Grants instance:
After the S3 integration is configured, a data owner can register S3 prefixes and buckets that are in the configured Access Grants location path to enforce access controls on resources. Immuta stores the connection information for the prefix so that the metadata can be used to create and enforce subscription policies on S3 data.
A data owner or governor can apply a subscription policy to a registered prefix, bucket, or object to control who can access objects beginning with that prefix or in that bucket after it is registered in Immuta. Once a subscription policy is created and Immuta users are subscribed to the prefix, bucket, or object, Immuta calls the Access Grants API to create a grant for each subscribed user, specifying the following parameters in the payload so that Access Grants can create and store a grant for each user:
Access Grants location
READ access
User or role principle
Registered prefix, bucket, or object
In the example below, a data owner registers the s3://research-data/* bucket, and Immuta stores the connection information in the Immuta metadata database. Once the user, Taylor, is subscribed to s3://research-data/*, Immuta calls the Access Grants API to create a grant for that user to allow them to read and write S3 data in that bucket:
The status of the integration is visible on the integrations tab of the Immuta application settings page. If errors occur in the integration, a banner will appear in the Immuta UI with guidance for remediating the error.
The definitions for each status and the state of configured data platform integrations is available in the response schema of the integrations API. However, the UI consolidates these error statuses and provides detail in the error messages.
To access S3 data registered in Immuta, users must be subscribed to the prefix, bucket, or object in Immuta, and their principals must be mapped to their Immuta user accounts. Once users are subscribed, they request temporary credentials from S3 Access Grants. Access Grants looks up the grant ID associated with the requester. If no matching grant exists, they receive an access denied error. If one exists, Access Grants assumes the IAM role associated with the location and requests temporary credentials that are scoped to the prefix, bucket, or object and permissions specified by the individual grant. Access Grants vends the credentials to the requester, who uses those temporary credentials to access the data in S3.
In the example below, Taylor requests temporary credentials from S3 Access Grants. Access Grants looks up the grant ID (1) for that user, assumes the arn:aws:iam::123456:role/access-grants-role IAM role for the location, and vends temporary credentials to Taylor, who then uses the credentials to access the research-data bucket in S3:
Note that when accessing data through S3 Access Grants, the user or application interacts directly with the Access Grants API to request temporary credentials; Immuta does not act in this process at all. See the diagram below for an illustration of the process for accessing data through S3 Access Grants.
AWS services that support S3 Access Grants will request temporary credentials for users automatically. If users are not using a service that supports S3 Access Grants, they must have the permissions listed in the AWS documentation to call the Access Grants API directly themselves to request temporary credentials to access data through the access grant.
For a list of AWS services that support S3 Access Grants, see the AWS documentation.
Immuta's S3 integration allows data owners and governors to apply object-level access controls on data in S3 through subscription policies. When a user is subscribed to a registered prefix, bucket, or object, Immuta calls the Access Grants API to create an individual grant that narrows the scope of access within the location to that registered prefix, bucket, or object. See the diagram below for a visualization of this process.
When a user's entitlements change or a subscription policy is added to, updated, or deleted from a prefix, Immuta performs one of the following processes for each user subscribed to the registered prefix:
User added to the prefix: Immuta specifies a permission (READ or READWRITE) for each user and uses the Access Grants API to create an individual grant for each user.
User updated: Immuta deletes the current grant ID and creates a new one using the Access Grants API.
User deleted: Immuta deletes the grant ID using the Access Grants API.
Immuta offers two subscription policy access types to manage read and write access to data in S3:
Read access policies manage who can get objects from S3.
Write access policies manage who can modify data in S3.
Data policies, which provide more granular controls by redacting or masking values in a table, are not supported for S3.
Data owners can register an S3 prefix at any level in the S3 path by creating an Immuta data source. During this process, Immuta stores the connection information for use in subscription policies.
Each prefix added in the data registration workflow is created as a single Immuta data source, and a subscription policy added to a data source applies to any objects in that bucket or beginning with that prefix:
Therefore, data owners should register prefixes or buckets at the lowest level of access control they need for that data. Using the example above, if the data owner needed to allow different users to access s3://yellow-bucket/research-data/* than those who should access s3://yellow-bucket/analyst-data/*, the data owner must register the research-data/* and analyst-data/* prefixes separately and then apply a subscription policy to those prefixes:
When an S3 data source is deleted, Immuta deletes all the grants associated with that prefix, bucket, or object in that location.
Access can be managed in AWS using IAM users, roles, or Identity Center (IDC). Immuta supports all three methods for user provisioning in the S3 integration.
However, if you manage access in AWS through IAM roles instead of users, user provisioning in Immuta must be done using IAM role principals. This means that if users share IAM roles, you could end up in a situation where you over-provision access to everyone in the IAM role.
See the guidelines below for the best practices to avoid this behavior if you currently use IAM roles to manage access.
Enable AWS IAM Identity Center (IDC) (recommended): IDC is the best approach for user provisioning because it treats users as users, not users as roles. Consequently, access controls are enforced for the querying user, nothing more. This approach eliminates over-provisioning and permits granular access control. Furthermore, IDC uses trusted identity propagation, meaning AWS propagates a user's identity wherever that user may operate within the AWS ecosystem. As a result, a user's identity always remains known and consistent as they navigate across AWS services, which is a key requirement for organizations to properly govern that user. Enabling IDC does not impact any existing access controls; it is additive. Immuta will manage the GRANTs for you using IDC if it is enabled and configured in Immuta. See the protect data section for instructions on mapping users from AWS IDC to user accounts in Immuta.
Create an IAM role per user: If you do not have IDC enabled, create an IAM role per user that is unique to that user and assign that IAM role to each corresponding user in Immuta. Ensure that the IAM role cannot be shared with other users. This approach can be a challenge because there is an IAM role max limit of 5,000 per AWS account.
Request on behalf of IAM roles (not recommended): Create users in Immuta that map to each of your existing IAM roles. Then, when users request access to data, they request on behalf of the IAM role user rather than themselves. This approach is not recommended because everyone in that role will gain access to data when granted access through a policy, and adding future users to that role will also grant access. Furthermore, it requires policy authors and approvers to understand what role should have access to what data.
Immuta supports mapping an Immuta user to AWS in one of the following ways:
IAM role principals: Only a single Immuta user can be mapped to an IAM role. This restriction prohibits enforcing policies on AWS users who could assume that role. Therefore, if using role principals, create a new user in Immuta that represents the role so that the role then has the permissions applied specifically to it.
See the protect data section for instructions on mapping principals to user accounts in Immuta.
The Amazon S3 integration will not interfere with existing legacy S3 integrations, and multiple S3 integrations can exist in a single Immuta tenant.
AWS services that support S3 Access Grants will request temporary credentials for users automatically. If users are not using a service that supports S3 Access Grants, they must have the permissions listed in the AWS documentation to call the Access Grants API directly themselves to request temporary credentials to access data through the access grant.
For a list of AWS services that support S3 Access Grants, see the AWS documentation.
During private preview, Immuta supports up to 500 prefixes (data sources) and up to 20 Immuta users that are mapped to S3 identities principals. This is a preview limitation that will be removed in a future phase of the integration.
S3 Access Grants allows 100,000 grants per region per account. Thus, if you have 5 Immuta users with access to 20,000 registered prefixes, you would reach this limit. See AWS documentation for details.
The following Immuta features are not currently supported by the integration in private preview:
Audit
Data policies
Impersonation
Schema monitoring
Tag ingestion
Immuta does not require users to learn a new API or language to access protected data. Instead, Immuta integrates with existing tools and data platforms while remaining invisible to downstream consumers.
The table below outlines features supported by each of Immuta's data platform integrations.
The table below illustrates the subscription policy access types supported by each integration. If a data platform isn't included in the table, that integration does not support any subscription policies. For more details about read and write access policy support for these data platforms, see the .
The table below outlines the types of data policies supported for various data platforms. If a data platform isn't included in the table, that integration does not support any data policies.
For details about each of these policies, see the .
Identification has varied support for data sources from different technologies based on the identifier type. For details about how identification works in Immuta, see the .
The table below outlines what information is included in the query audit logs for each integration where query audit is supported.
Legend:
✅ This is available and the information is included in audit logs.
❌ This is not available and the information is not included in audit logs.
SELECT on the following system tables:system.access.table_lineage
system.access.column_lineage
system.access.audit
system.query.history
system.access.audit
s3:DeleteAccessGrantsLocations3:GetAccessGrantsLocation
s3:UpdateAccessGrantsLocation
accessgrantsinstance resource:
s3:CreateAccessGrantsInstance
s3:CreateAccessGrantsLocation
s3:DeleteAccessGrantsInstance
s3:GetAccessGrantsInstance
s3:GetAccessGrantsInstanceForPrefix
s3:GetAccessGrantsInstanceResourcePolicy
s3:ListAccessGrants
s3:ListAccessGrantsLocations
accessgrant resource:
s3:DeleteAccessGrant
s3:GetAccessGrant
bucket resource: s3:ListBucket
role resource:
iam:GetRole
iam:PassRole
all resources: s3:ListAccessGrantsInstances
S3 Access Grants S3 Location Scope is the base S3 location that Immuta will use for this connection when registering S3 prefixes. This path must be unique across all S3 integrations configured in Immuta. During data source registration, this prefix is prepended to the data source prefixes to build the final path used to grant or revoke access to that data in S3. For example, a location prefix of s3://research-data would be prepended to the data source prefix /demographics to generate a final path of s3://research-data/demographics.
User ID value found in AWS IAM Identity Center, not the user's email address. Ensure that you have added the content to your IAM policy JSON as outlined in the Set up S3 Access Grants instance section above to allow Immuta to use AWS Identity Center.Unset (fallback to Immuta username): When selecting this option, the S3 username is assumed to be the same as the Immuta username.
arn:aws:s3:us-east-2:6********499:access-grants/default/newlocation2
<aws_account>: Your AWS account ID.
<identity_store_id>: The globally unique identifier for the identity store (IdentityStoreId) that is connected to the Identity Center instance. This value is generated when a new identity store is created.

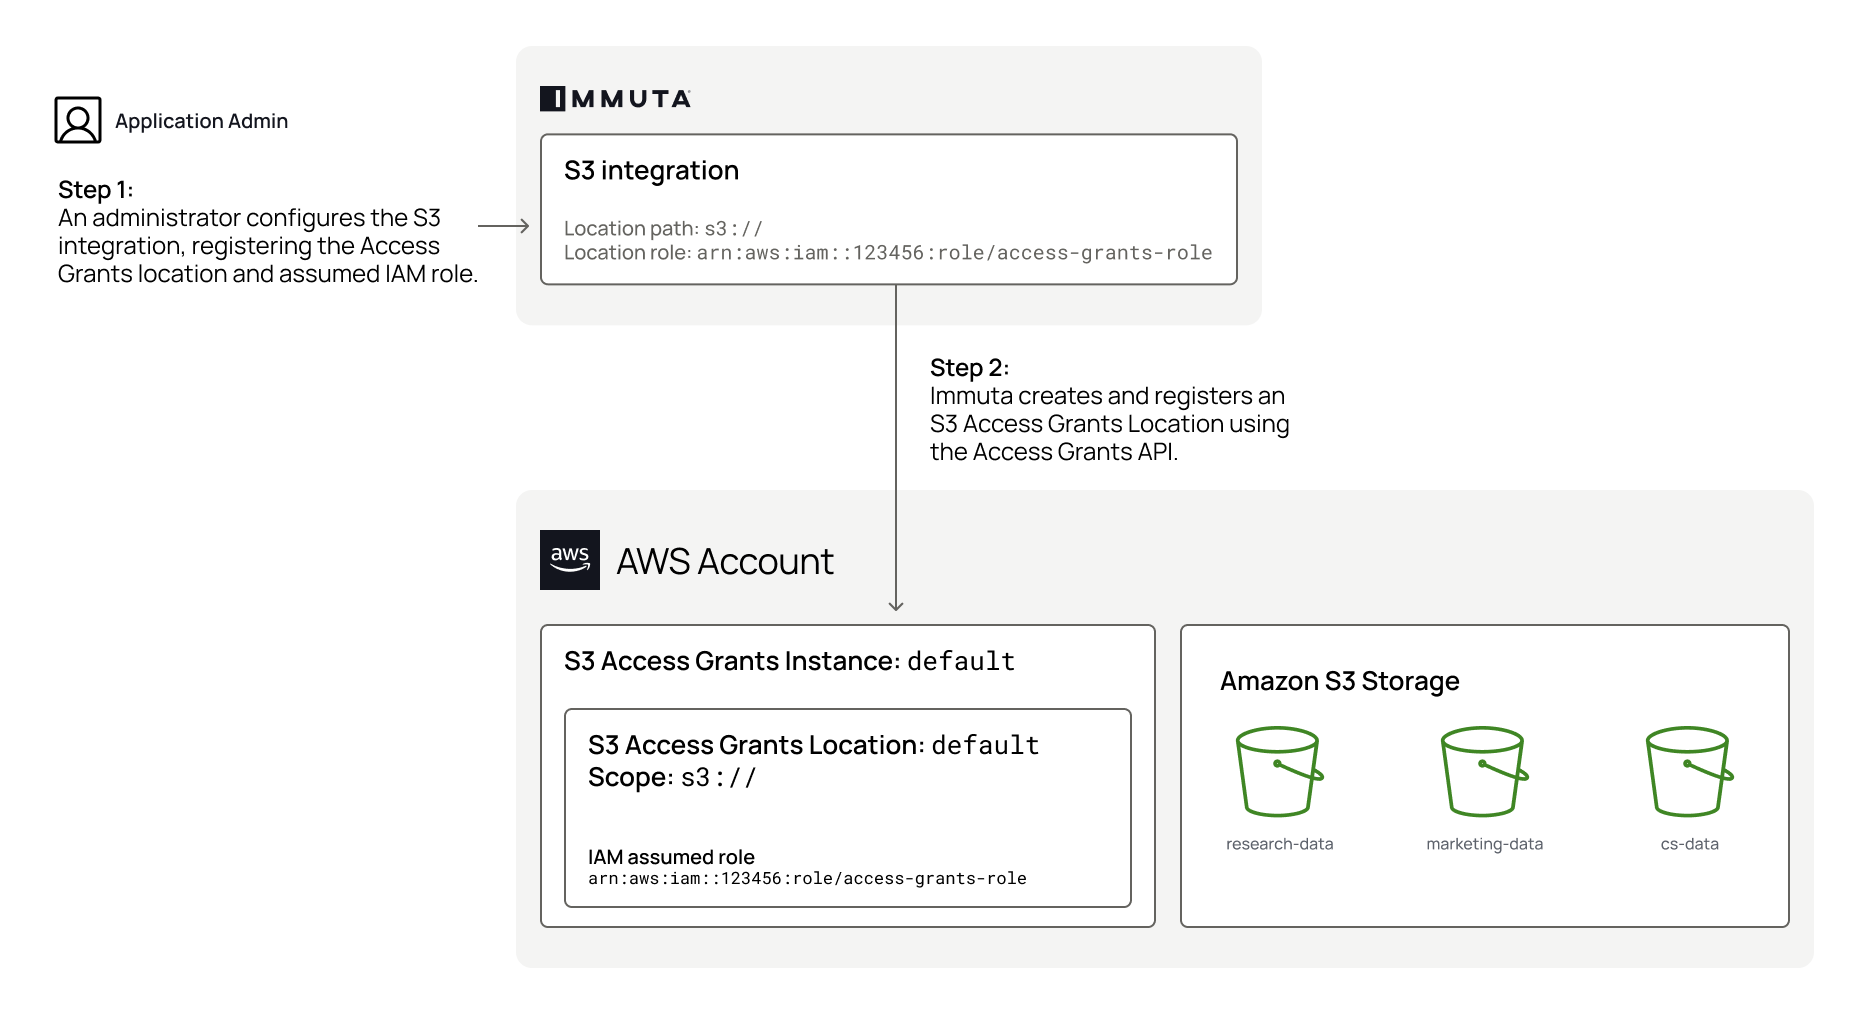
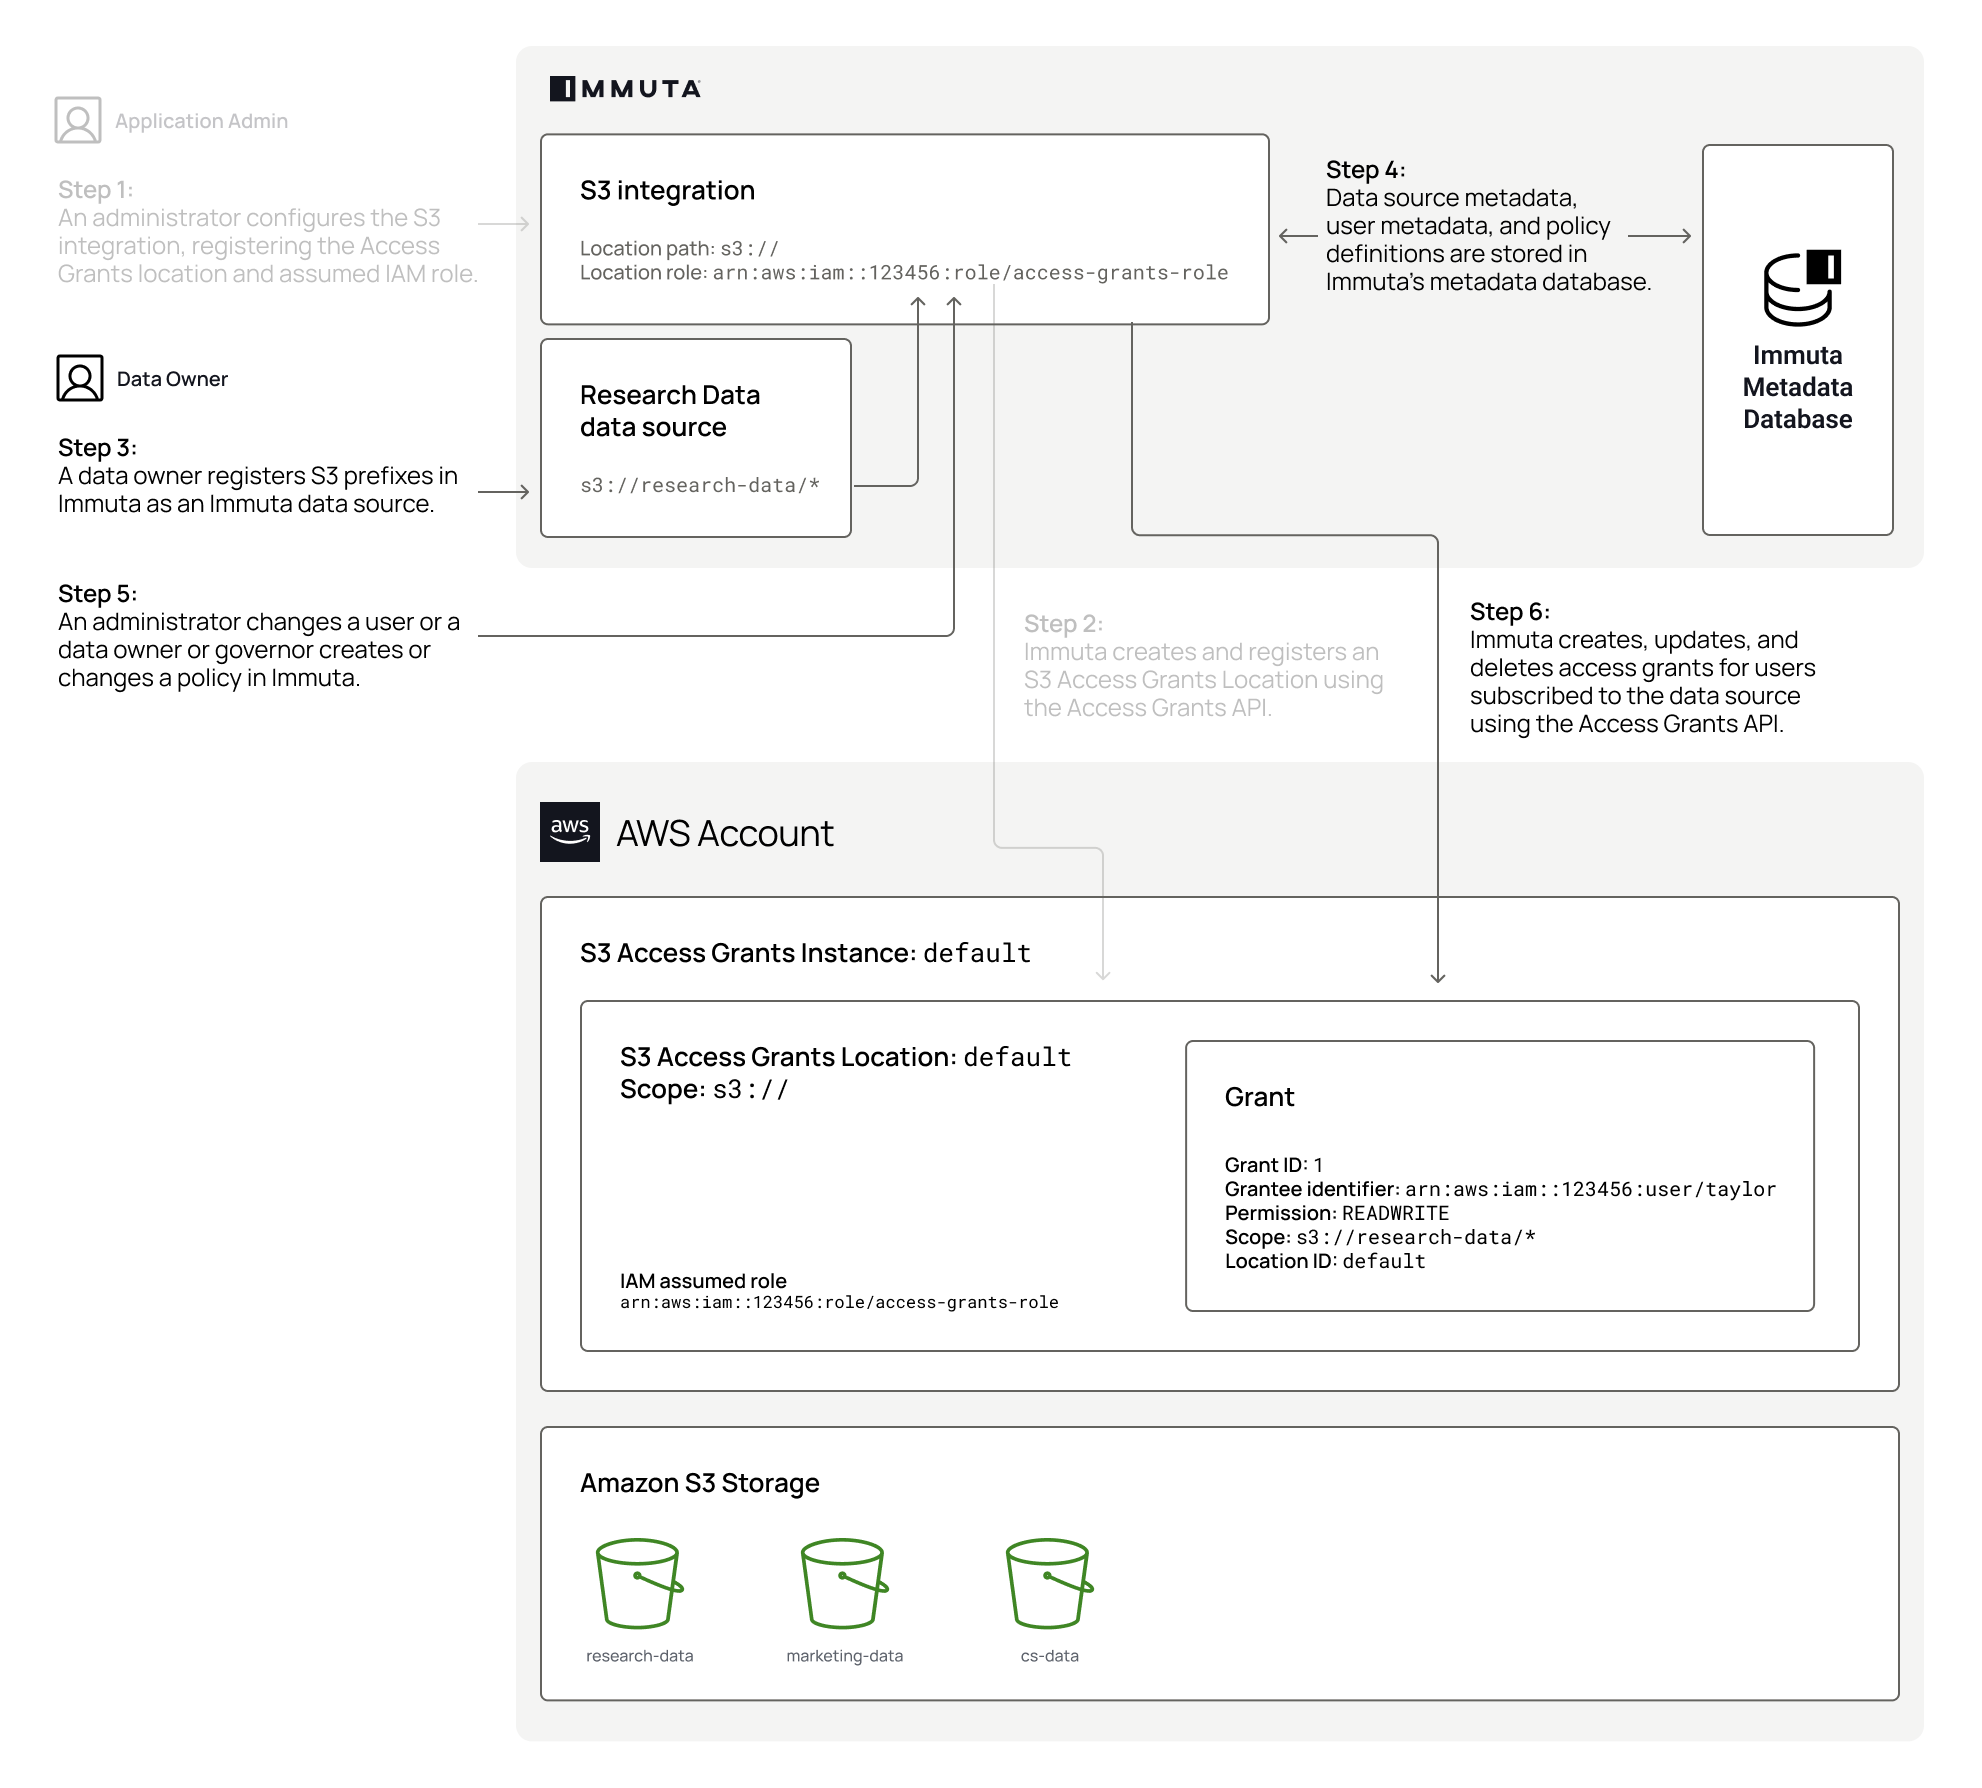
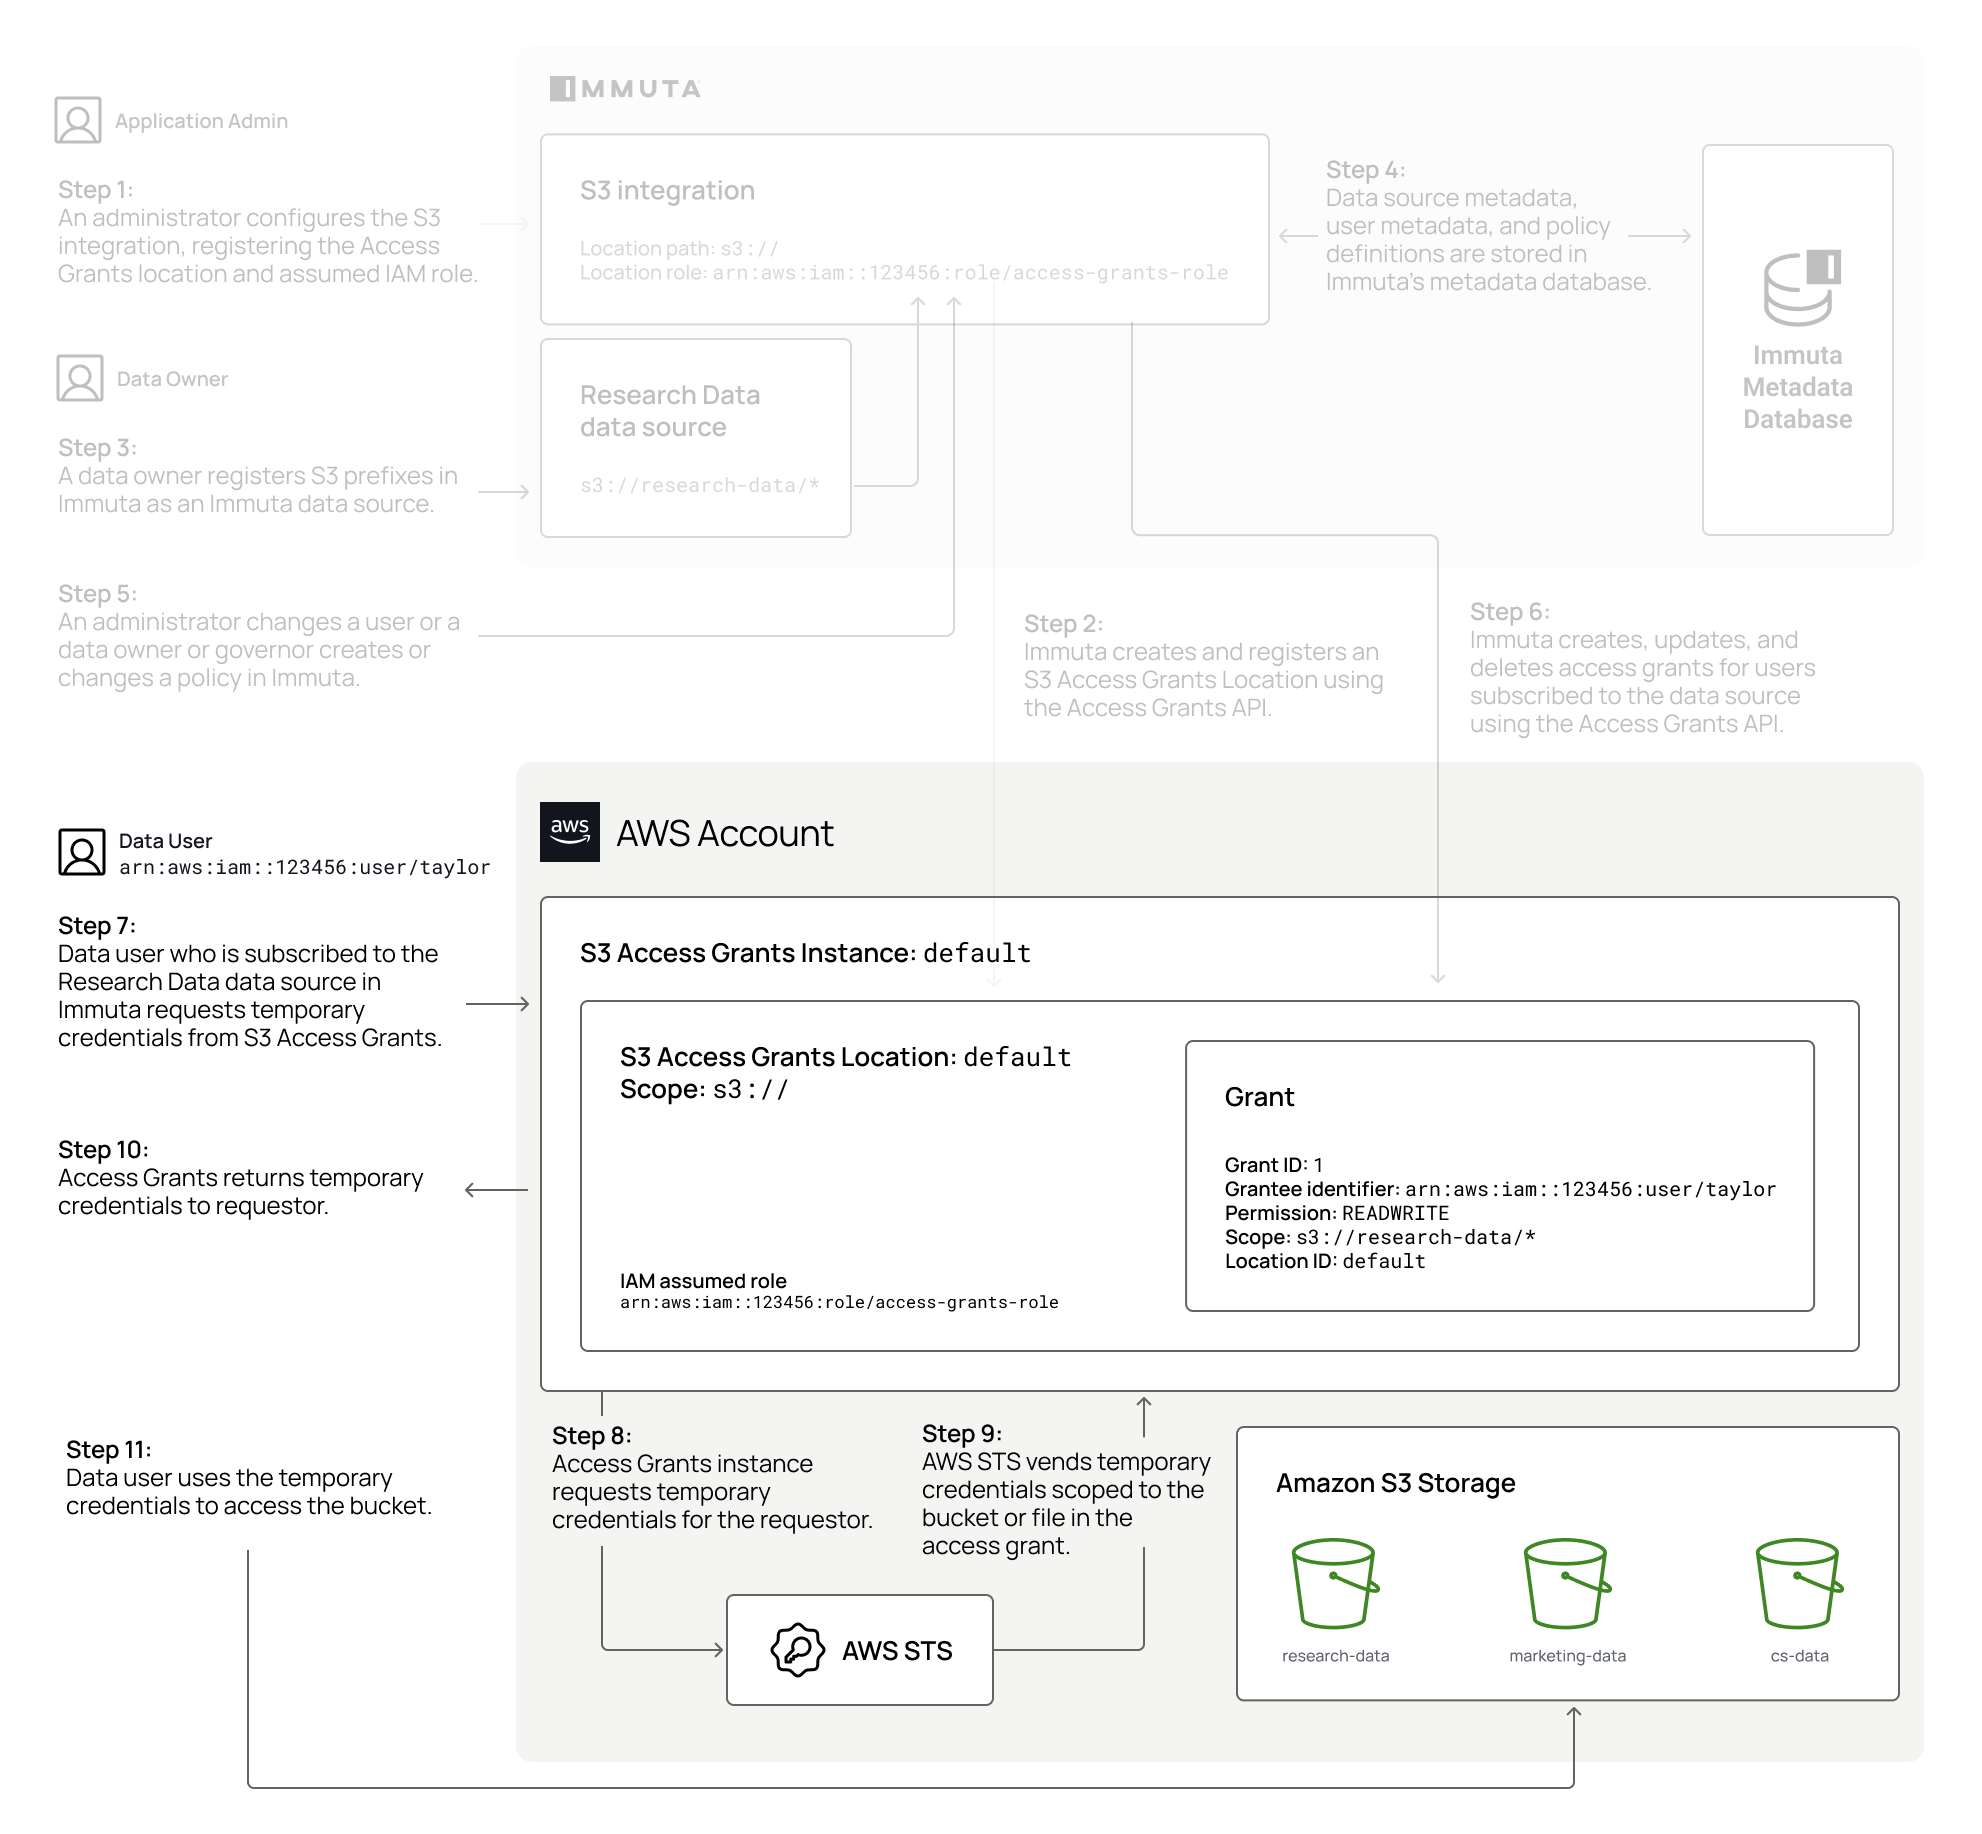
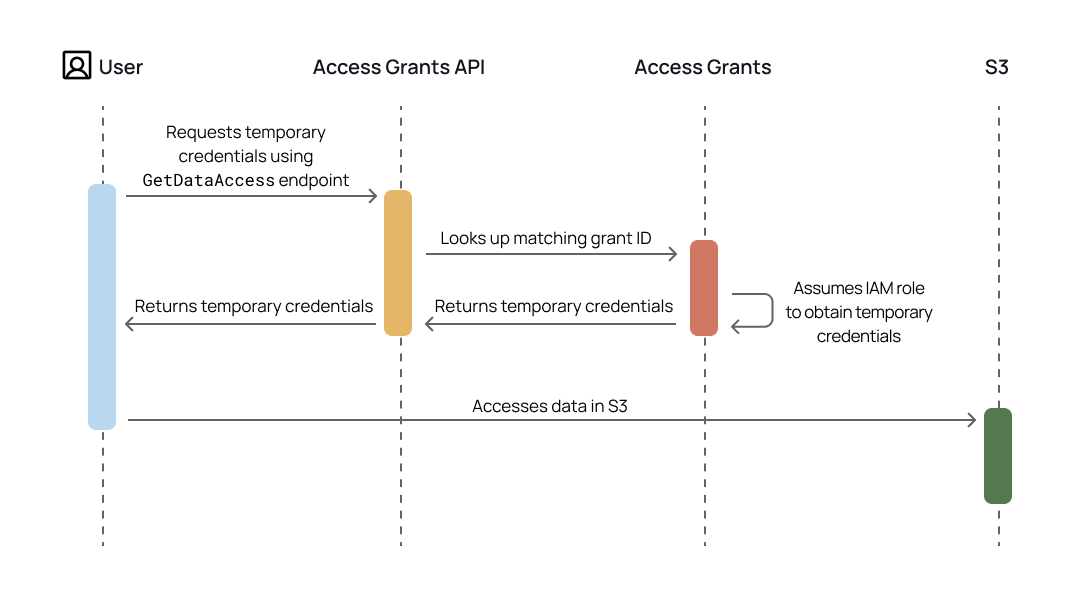
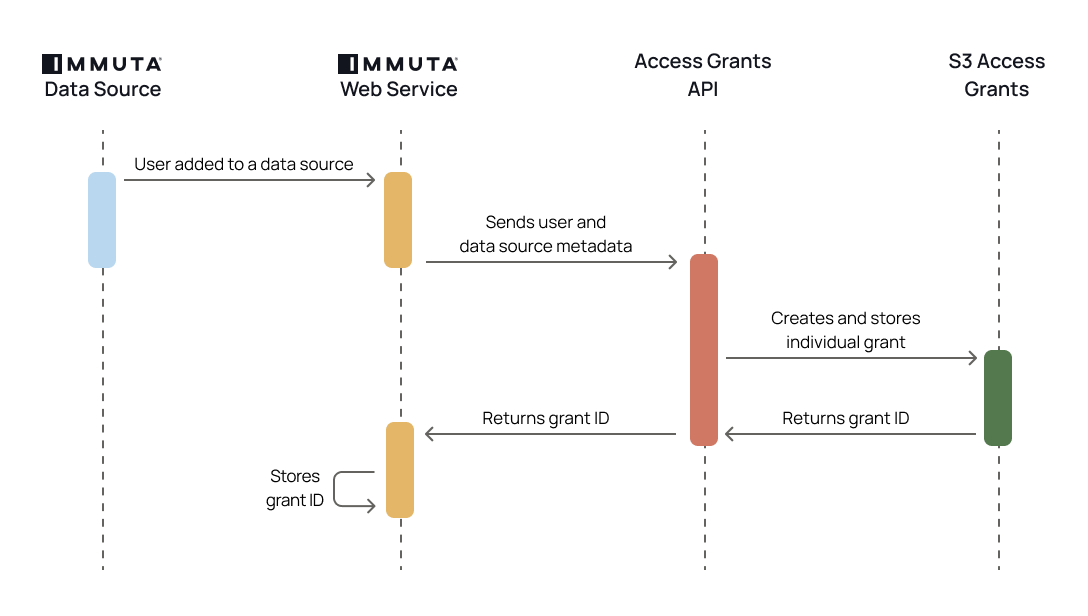
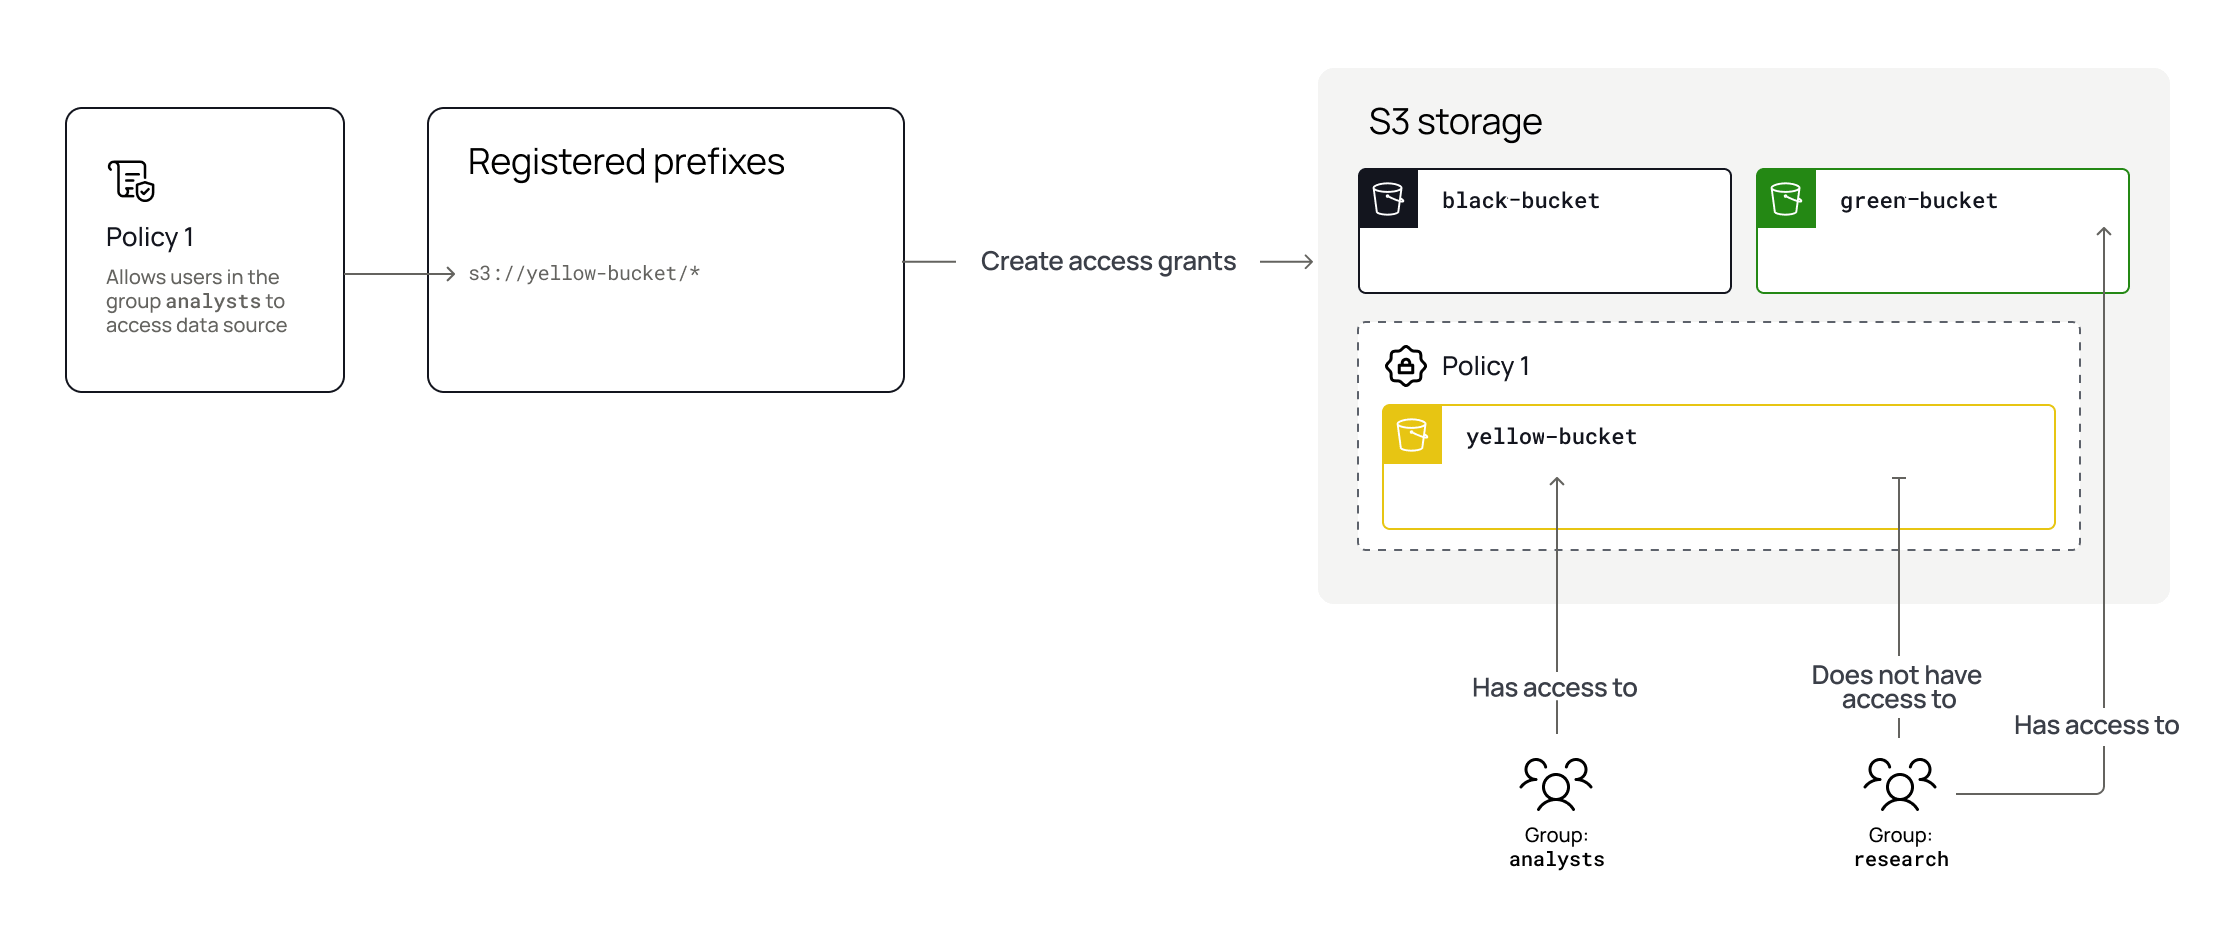
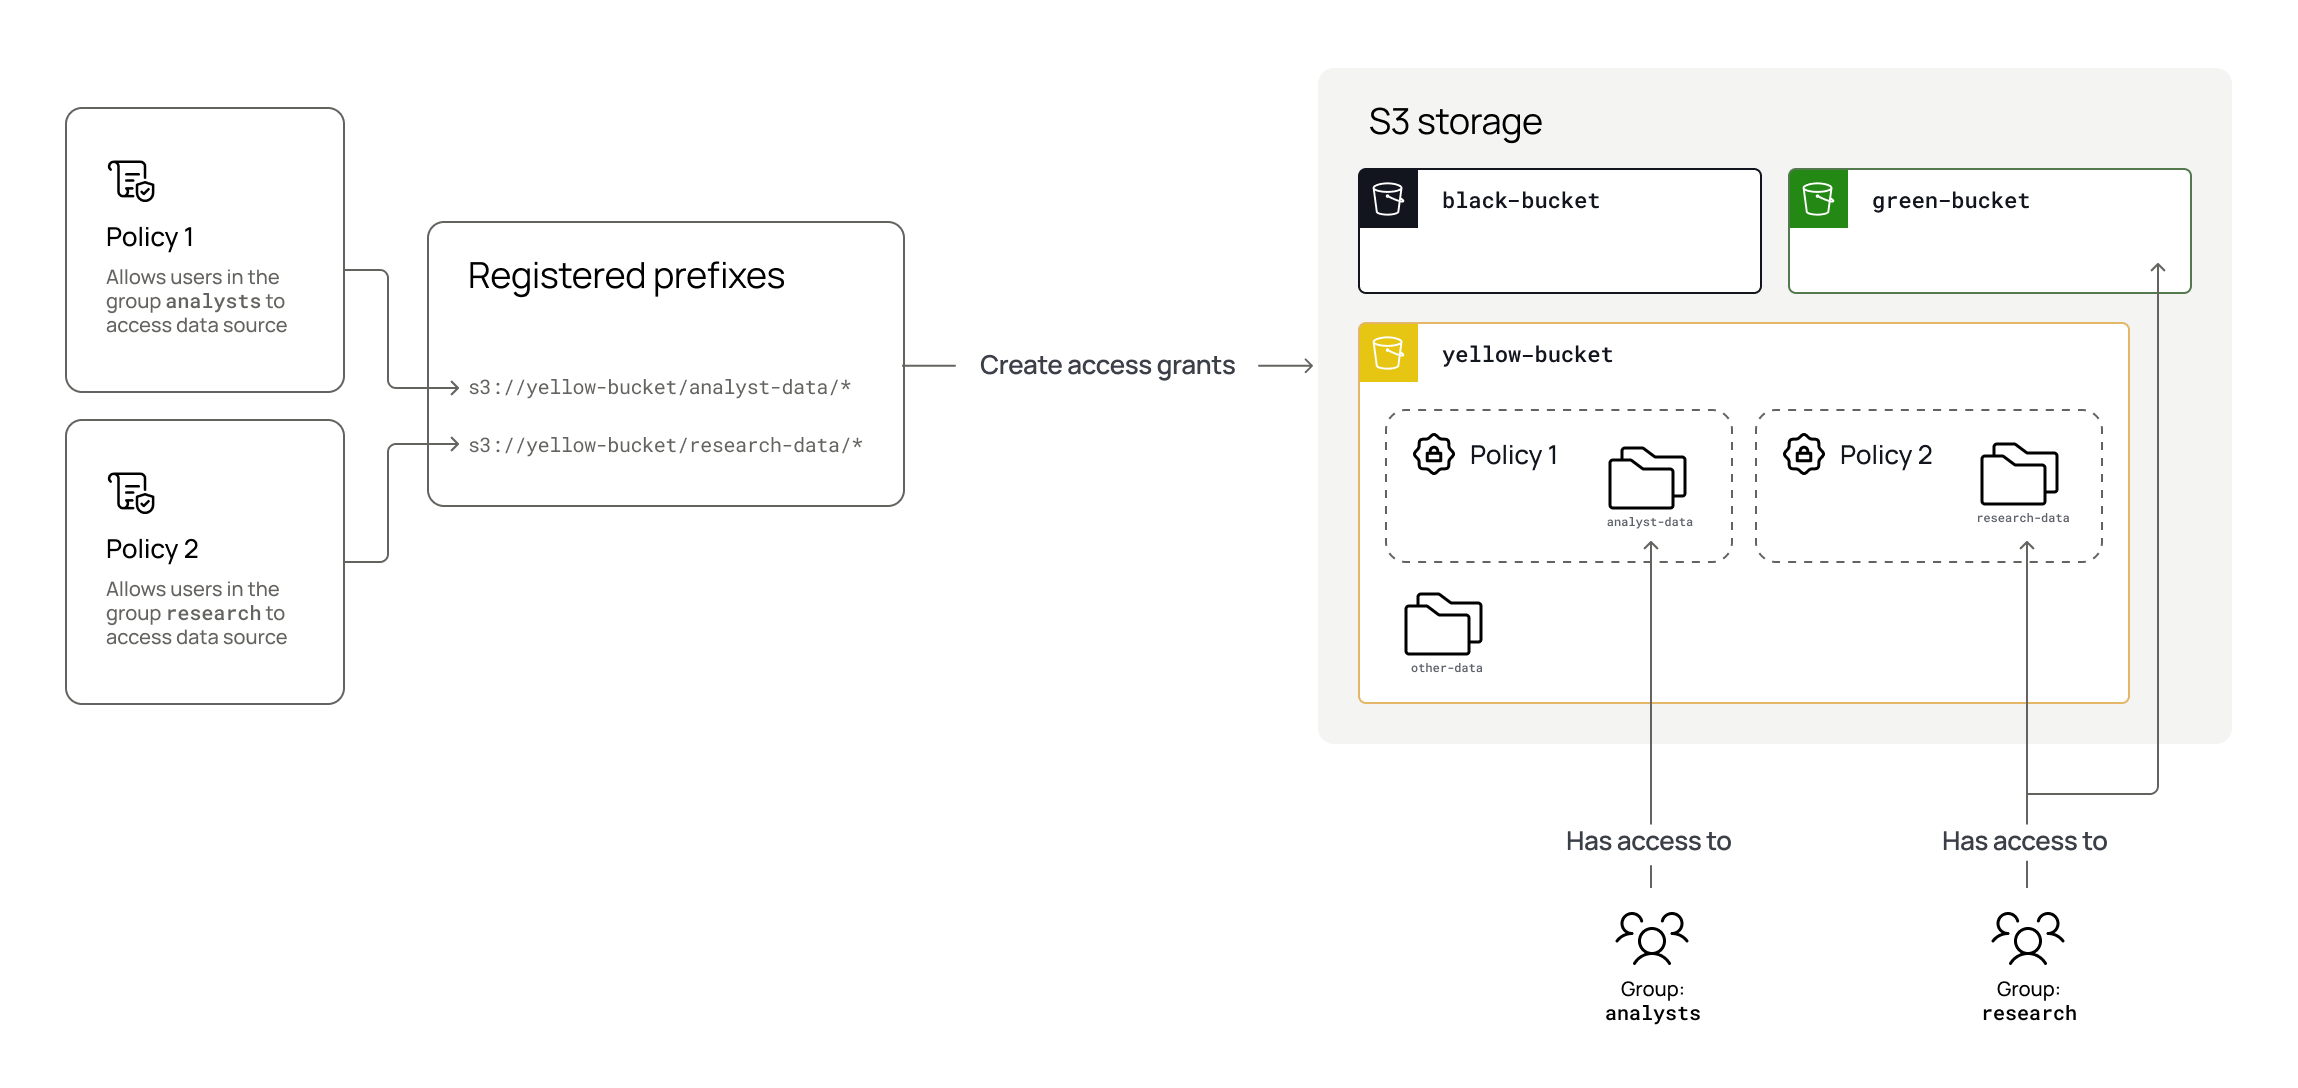
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "Stmt1234567891011",
"Effect": "Allow",
"Principal": {
"Service":"access-grants.s3.amazonaws.com"
},
"Action": [
"sts:AssumeRole",
"sts:SetSourceIdentity"
]
}
]
} {
"Version": "2012-10-17",
"Statement": [
{
"Sid": "ObjectLevelReadPermissions",
"Effect": "Allow",
"Action": [
"s3:GetObject",
"s3:GetObjectVersion",
"s3:GetObjectAcl",
"s3:GetObjectVersionAcl",
"s3:ListMultipartUploadParts"
],
"Resource": [
"<bucket arn>/*"
]
},
{
"Sid": "ObjectLevelWritePermissions",
"Effect": "Allow",
"Action": [
"s3:PutObject",
"s3:PutObjectAcl",
"s3:PutObjectVersionAcl",
"s3:DeleteObject",
"s3:DeleteObjectVersion",
"s3:AbortMultipartUpload"
],
"Resource": [
"<bucket arn>/*"
]
},
{
"Sid": "BucketLevelReadPermissions",
"Effect": "Allow",
"Action": [
"s3:ListAllMyBuckets",
"s3:ListBucket"
],
"Resource": [
"<bucket arn>"
]
}
]
}{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "RolePermissions",
"Effect": "Allow",
"Action": [
"iam:GetRole",
"iam:PassRole"
],
"Resource": "<role_arn>"
},
{
"Sid": "AccessGrants",
"Effect": "Allow",
"Action": [
"s3:CreateAccessGrant",
"s3:DeleteAccessGrantsLocation",
"s3:GetAccessGrantsLocation",
"s3:CreateAccessGrantsLocation",
"s3:GetAccessGrantsInstance",
"s3:GetAccessGrantsInstanceForPrefix",
"s3:GetAccessGrantsInstanceResourcePolicy",
"s3:ListAccessGrants",
"s3:ListAccessGrantsLocations",
"s3:ListAccessGrantsInstances",
"s3:DeleteAccessGrant",
"s3:GetAccessGrant"
],
"Resource": [
"<access_grants_instance_arn>"
]
}
]
}{
"Sid": "sso",
"Effect": "Allow",
"Action": [
"sso:DescribeInstance",
"sso:DescribeApplication",
"sso-directory:DescribeUsers"
],
"Resource": [
"<iam_identity_center_instance_arn>",
"<iam_identity_center_application_arn_for_s3_access_grants>",
"arn:aws:identitystore:::user/*",
"arn:aws:identitystore::<aws_account>:identitystore/<identity_store_id>"
]
}, {
"Sid": "idc",
"Effect": "Allow",
"Action": [
"identitystore:DescribeUser",
"identitystore:DescribeGroup"
],
"Resource": [
"<iam_identity_center_instance_arn>",
"<iam_identity_center_application_arn_for_s3_access_grants>",
"arn:aws:identitystore:::user/*",
"arn:aws:identitystore::<aws_account>:identitystore/<identity_store_id>"
]
}❌
❌
❌
Azure Synapse Analytics
✅
✅
✅
✅
❌
❌
Databricks Spark
✅
✅
✅
✅
✅
❌
Databricks Unity Catalog
✅
✅
✅
❌
✅
✅
Google BigQuery
✅
✅
✅
❌
❌
❌
Snowflake
✅
✅
✅
✅
✅
✅
Starburst (Trino)
✅
✅
✅
✅
✅
❌
✅
❌ View-based integrations are read-only
✅
❌ Write access is controlled through and
✅
✅
✅
❌ View-based integrations are read-only
✅
✅
✅
✅
✅
✅
✅
❌
✅
✅
Custom function
✅
✅
✅
✅
✅
✅
✅
Format preserving masking
❌
❌
❌
❌
❌
✅
❌
Hashing
✅
✅
✅
✅
✅
✅
✅
Masking fields within STRUCT columns
❌
❌
✅
Supported with caveats
❌
❌
❌
Minimize
✅
✅
✅
✅
❌
✅
✅
Only show data by time
✅
✅
✅
✅
❌
✅
✅
Only show rows (matching)
✅
✅
✅
✅
✅
✅
✅
Randomized response
❌
❌
❌
❌
❌
✅
❌
Regex
✅
❌
✅
✅
✅
✅
✅
Replace with NULL or constant
✅
✅
Supported with caveats
✅
✅
✅
✅
Reversible masking
✅
❌
✅
❌
❌
✅
✅
Rounding
✅
✅
✅
✅
✅
✅
✅
WHERE clause
✅
✅
✅
✅
✅
✅
✅
❌
❌
✅
Azure Synapse Analytics
❌
❌
✅
Databricks
✅
✅
✅
Google BigQuery
❌
❌
✅
Snowflake
✅
✅
✅
Starburst (Trino)
✅
✅
✅
Object queried
✅
✅
✅
✅
Columns returned
❌
✅
✅
✅
Rows returned
❌
✅
✅
✅
Query text
✅
✅
✅
✅
Unauthorized information
✅
✅
Limited support
❌
Amazon Redshift
✅
✅
✅
✅
❌
❌
Amazon S3
✅
❌
✅
❌ View-based integrations are read-only
✅
Cell-level masking
Amazon Redshift
✅
✅
✅
Table and user coverage
Registered data sources and users
All tables and users
Registered data sources and users
✅
✅
✅
Amazon S3
Registered data sources and users


